Summary of METR's predeployment evaluation of Claude Opus 5.5
Source
metr.org
Date
Why it matters
An outside evaluator tests whether Claude Opus 5.5 would dramatically accelerate AI R&D, using long-horizon tasks. It shows what third-party capability evidence for a new frontier model looks like and where it stops.
Key takeaways · AI-distilled
METR's predeployment review of Claude Opus 5.5 rests on 10 business days of API testing across five tasks (Budget NanoGPT Speedrun, LMCA conceptual arguments, Train a Program, Gaming Bot and Sunlight), plus an Anthropic questionnaire and a researcher interview.
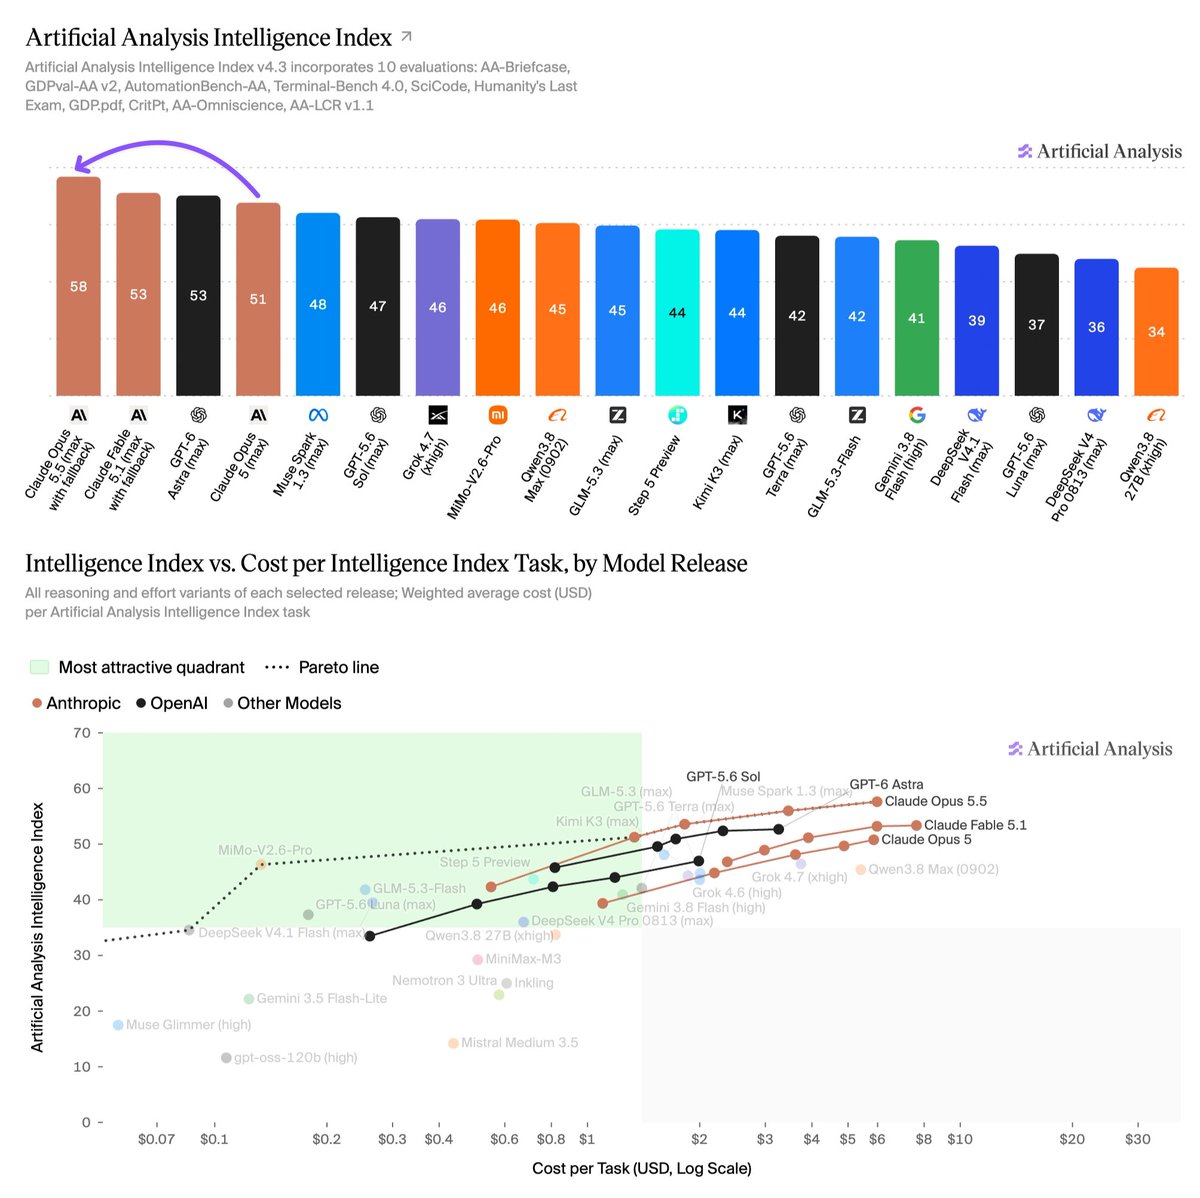
METR concludes Opus 5.5 is a modest, on-trend improvement over Fable 5.1 on both verifiable and harder-to-verify tasks, likely to speed up researchers somewhat but unlikely to fully automate AI R&D.
METR says the remaining gap is researcher 'judgment': foresight, prediction and building one's own feedback loops, and its evidence does not show Opus 5.5 improving much on these over Fable 5.1, though it calls this highly uncertain.
On whether AI sped up Opus 5.5's own development, METR cites a separate METR team's preliminary estimate of about 1.5x acceleration with perhaps a 30% chance of 2x, noting the estimate's time period was unspecified and its supporting evidence was not shared.
The evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → was unpaid, and Anthropic could review and edit METR's draft before it appeared in the system card; METR notes its findings were about AI R&D capability, not compliance with Anthropic's policy thresholds or alignmentThe work of making AI systems actually pursue what their builders and users intend, rather than something subtly or dangerously different.Full definition →.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
alignment — The work of making AI systems actually pursue what their builders and users intend, rather than something subtly or dangerously different.