@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
- Source
- x.com
- Author
- alexocheema
- Date
Context
Alex Cheema, a co-founder of EXO Labs, had predicted that the upcoming of Qwen 3.8 27B would bring intelligence close to GLM-5.2 to a 36GB MacBook at about 25 per second. In this follow-up he corrects the speed to closer to 50 tokens per second, on the condition that the software uses multi-token prediction, or MTP.
Cheema groups MTP with other methods such as DFlash. A normally produces text one token per full pass, so generating many tokens takes many passes in a row. Speculative decoding has a cheaper predictor draft several tokens ahead and lets the full model check them together; the paper that introduced it describes faster sampling without any changes to the outputs. That is why Cheema calls these methods a free lunch with no loss in quality. He adds that the gain depends on the task, because it rises with how often the drafted tokens are accepted, and code, full of predictable tokens like brackets, tends to be accepted more often.
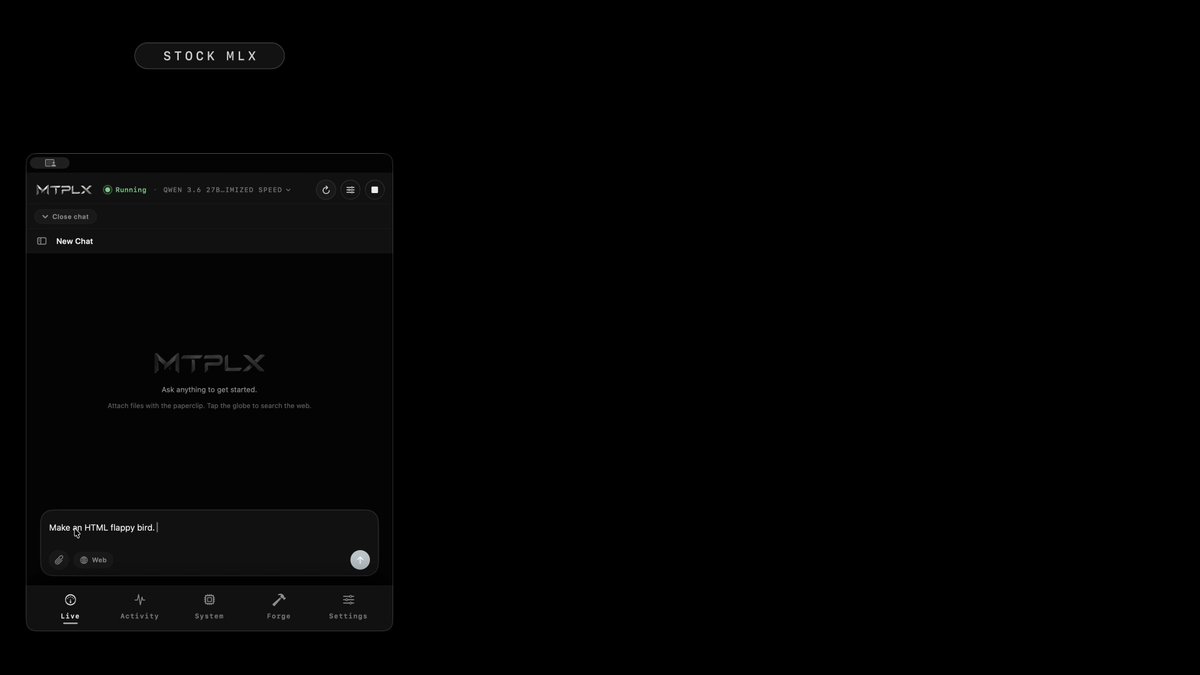
The higher figure depends on software that is not yet standard. Cheema says the MLX ecosystem for running models on Macs has been slow to adopt MTP, and points to MTPLX, a separate project that already supports it; its developer reported more than 72 tokens per second on the earlier Qwen 3.6 27B on a MacBook Pro M5 Max. Cheema says he hopes the Qwen 3.8 27B launch pushes MLX to add MTP support.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 postApple markets a four-Mac cluster for trillion-parameter local inference
 postLocal inference crosses over: the M5 Ultra and the 1,000x claim
Checking sign-in…
Loading comments…