Opus 5.5 tops Artificial Analysis index as Anthropic cuts prices
- Source
- x.com
- Date

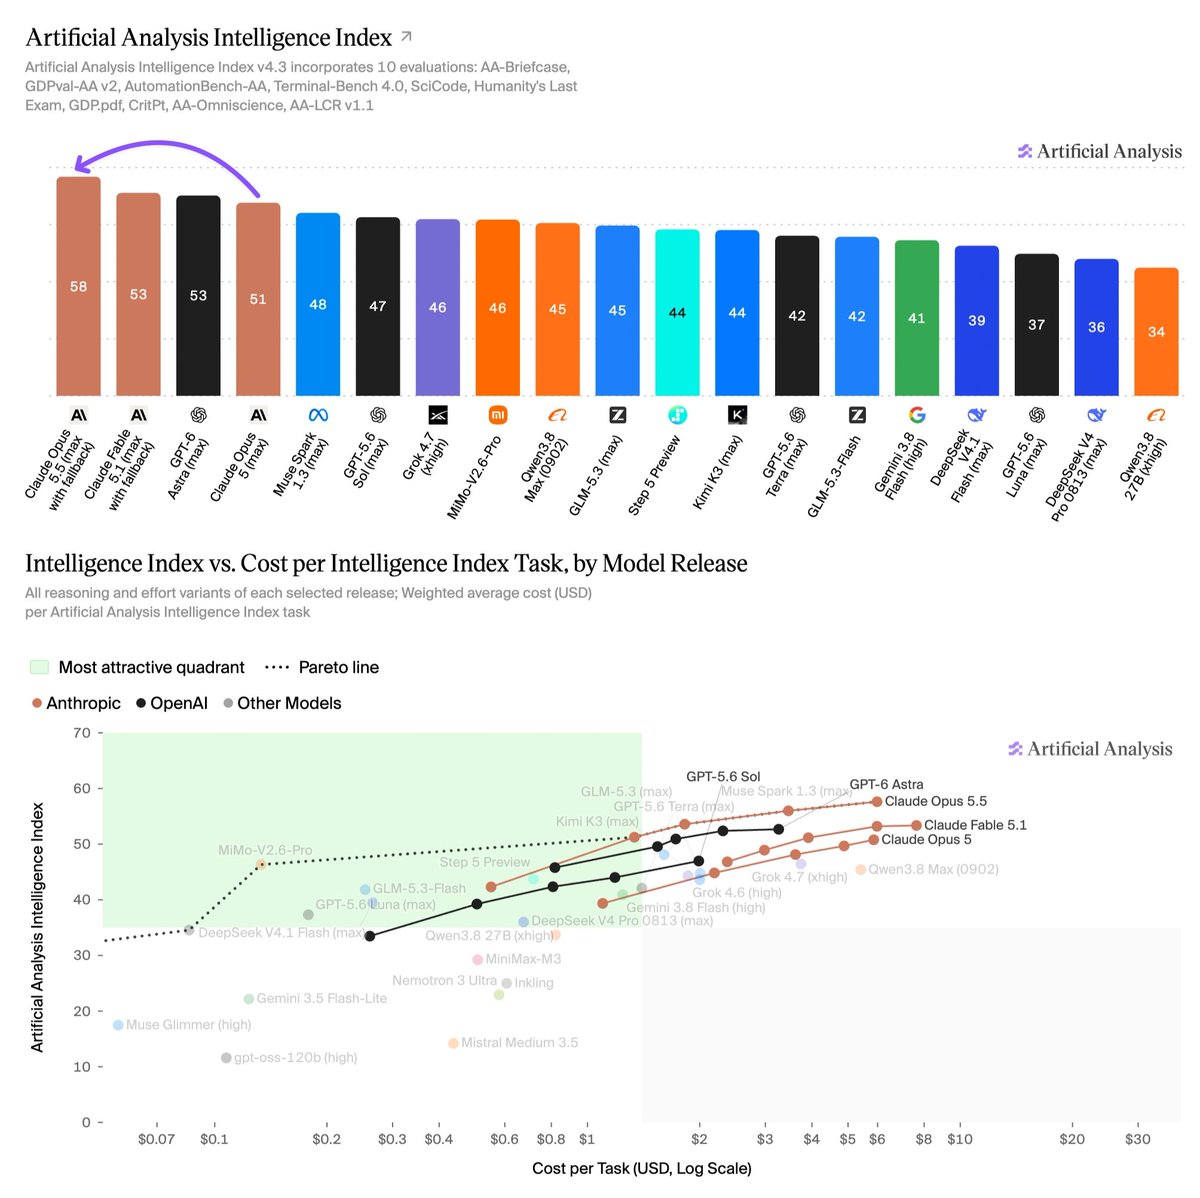
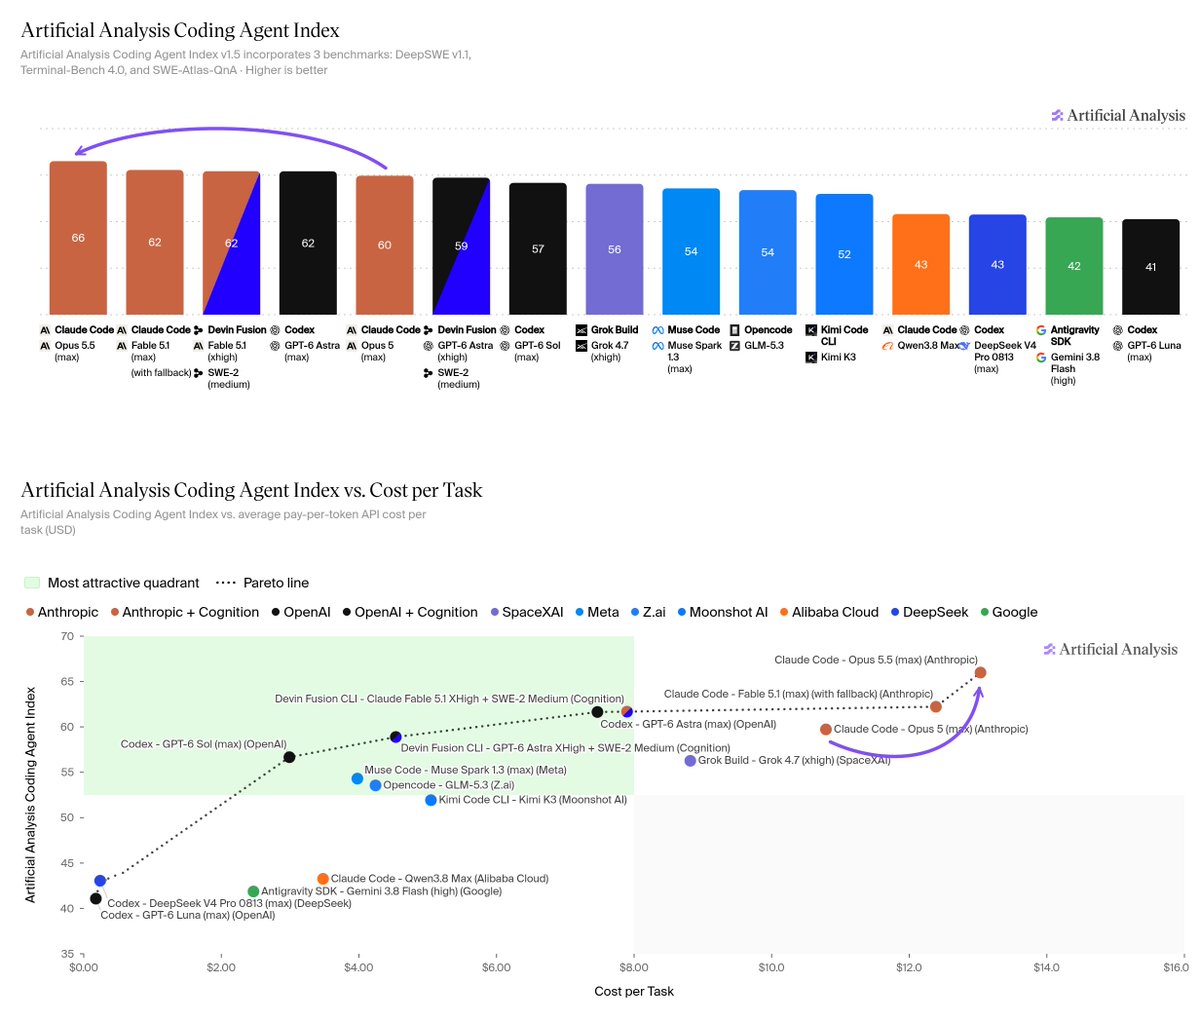
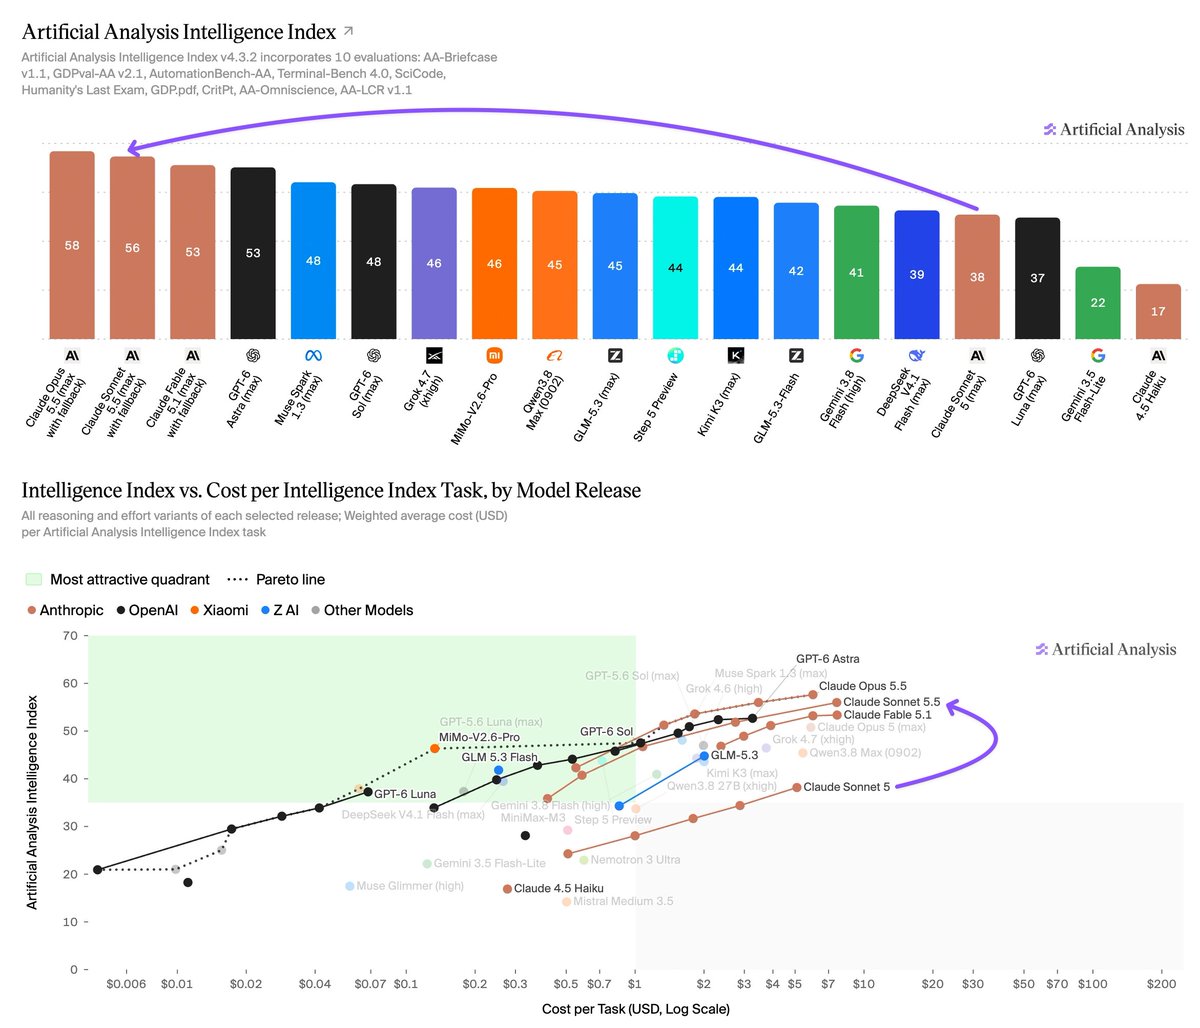
Claude Opus 5.5 takes the top spot on the Artificial Analysis Intelligence Index, along with a 20% price cut and larger cache hit discount Claude Opus 5.5 brings Anthropic to parity with GPT-6 Astra on evaluations like Terminal-Bench 4.0 and AutomationBench-AA, while extending Anthropic’s lead in agentic knowledge work. At max effort it scores 58 on the Artificial Analysis Intelligence Index, the highest score we have measured by several points. Anthropic has cut Opus pricing to $4/$20 per 1M input/output tokens (Opus 5: $5/$25) and cache reads from $0.50 to $0.20. Key takeaways: ➤ Consistent strong performance, with leading scores on six of the ten Intelligence Index evaluations: Humanity's Last Exam 61.4% (previous best 59.1%, Claude Fable 5.1), SciCode 66.9% (63.1%, Fable 5.1), GDPval-AA v2.1, AA-Briefcase v1.1, AA-Omniscience and AutomationBench-AA. On Terminal-Bench 4.0 it scores 59.6%, level with the leader GPT-6 Astra (xhigh) and +11 points over Opus 5. It remains slightly behind on CritPt, AA-LCR, and GDP.pdf ➤ Leads in agentic knowledge work: On AA-Briefcase, our private frontier knowledge work evaluation, it reaches an Elo of 1822. This is +143 over Fable 5.1, ahead…
Context
Claude Opus 5.5, the newest Opus model from Anthropic, has the highest score Artificial Analysis has recorded on its Intelligence Index, which combines ten evaluations the independent benchmarking firm runs itself (Artificial Analysis on X). At its maximum effort setting the model scores 58, which the firm says is several points above anything it has measured before. It leads on six of the ten tests, including Humanity's Last Exam at 61.4% against a previous best of 59.1% from Claude Fable 5.1. On Terminal-Bench 4.0, a test of agents working at a command line, it scores 59.6%, level with OpenAI's GPT-6 Astra and 11 points above Opus 5. It trails slightly on three tests: CritPt, AA-LCR and GDP.pdf.
The lower price per does not make each task cheaper. Anthropic cut Opus list prices 20%, to $4 per million input tokens and $20 per million output tokens from $5 and $25 for Opus 5, and cut cache reads, the price charged when a request reuses input the model has already processed, from $0.50 to $0.20 per million. But at max effort Opus 5.5 writes about 119,000 output tokens per index task, against about 73,000 for Opus 5 and about 27,000 for GPT-6 Astra. Artificial Analysis says the two effects roughly cancel, leaving cost per task level with Opus 5.
In a follow-up post, the firm broke that down: Opus 5.5 at max costs $5.98 per Intelligence Index task against $5.86 for Opus 5. At Opus 5's prices, the extra tokens alone would have pushed it to about $10.51. The 20% base cut brings that to $8.41, and the cheaper cache reads take it the rest of the way, saving slightly more than the headline cut does. Cheaper cache reads help most in long sessions, which resend the same on every step. For someone already paying for Opus, the upgrade buys the top index score at about the same cost per task rather than a lower bill.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.




Checking sign-in…
Loading comments…