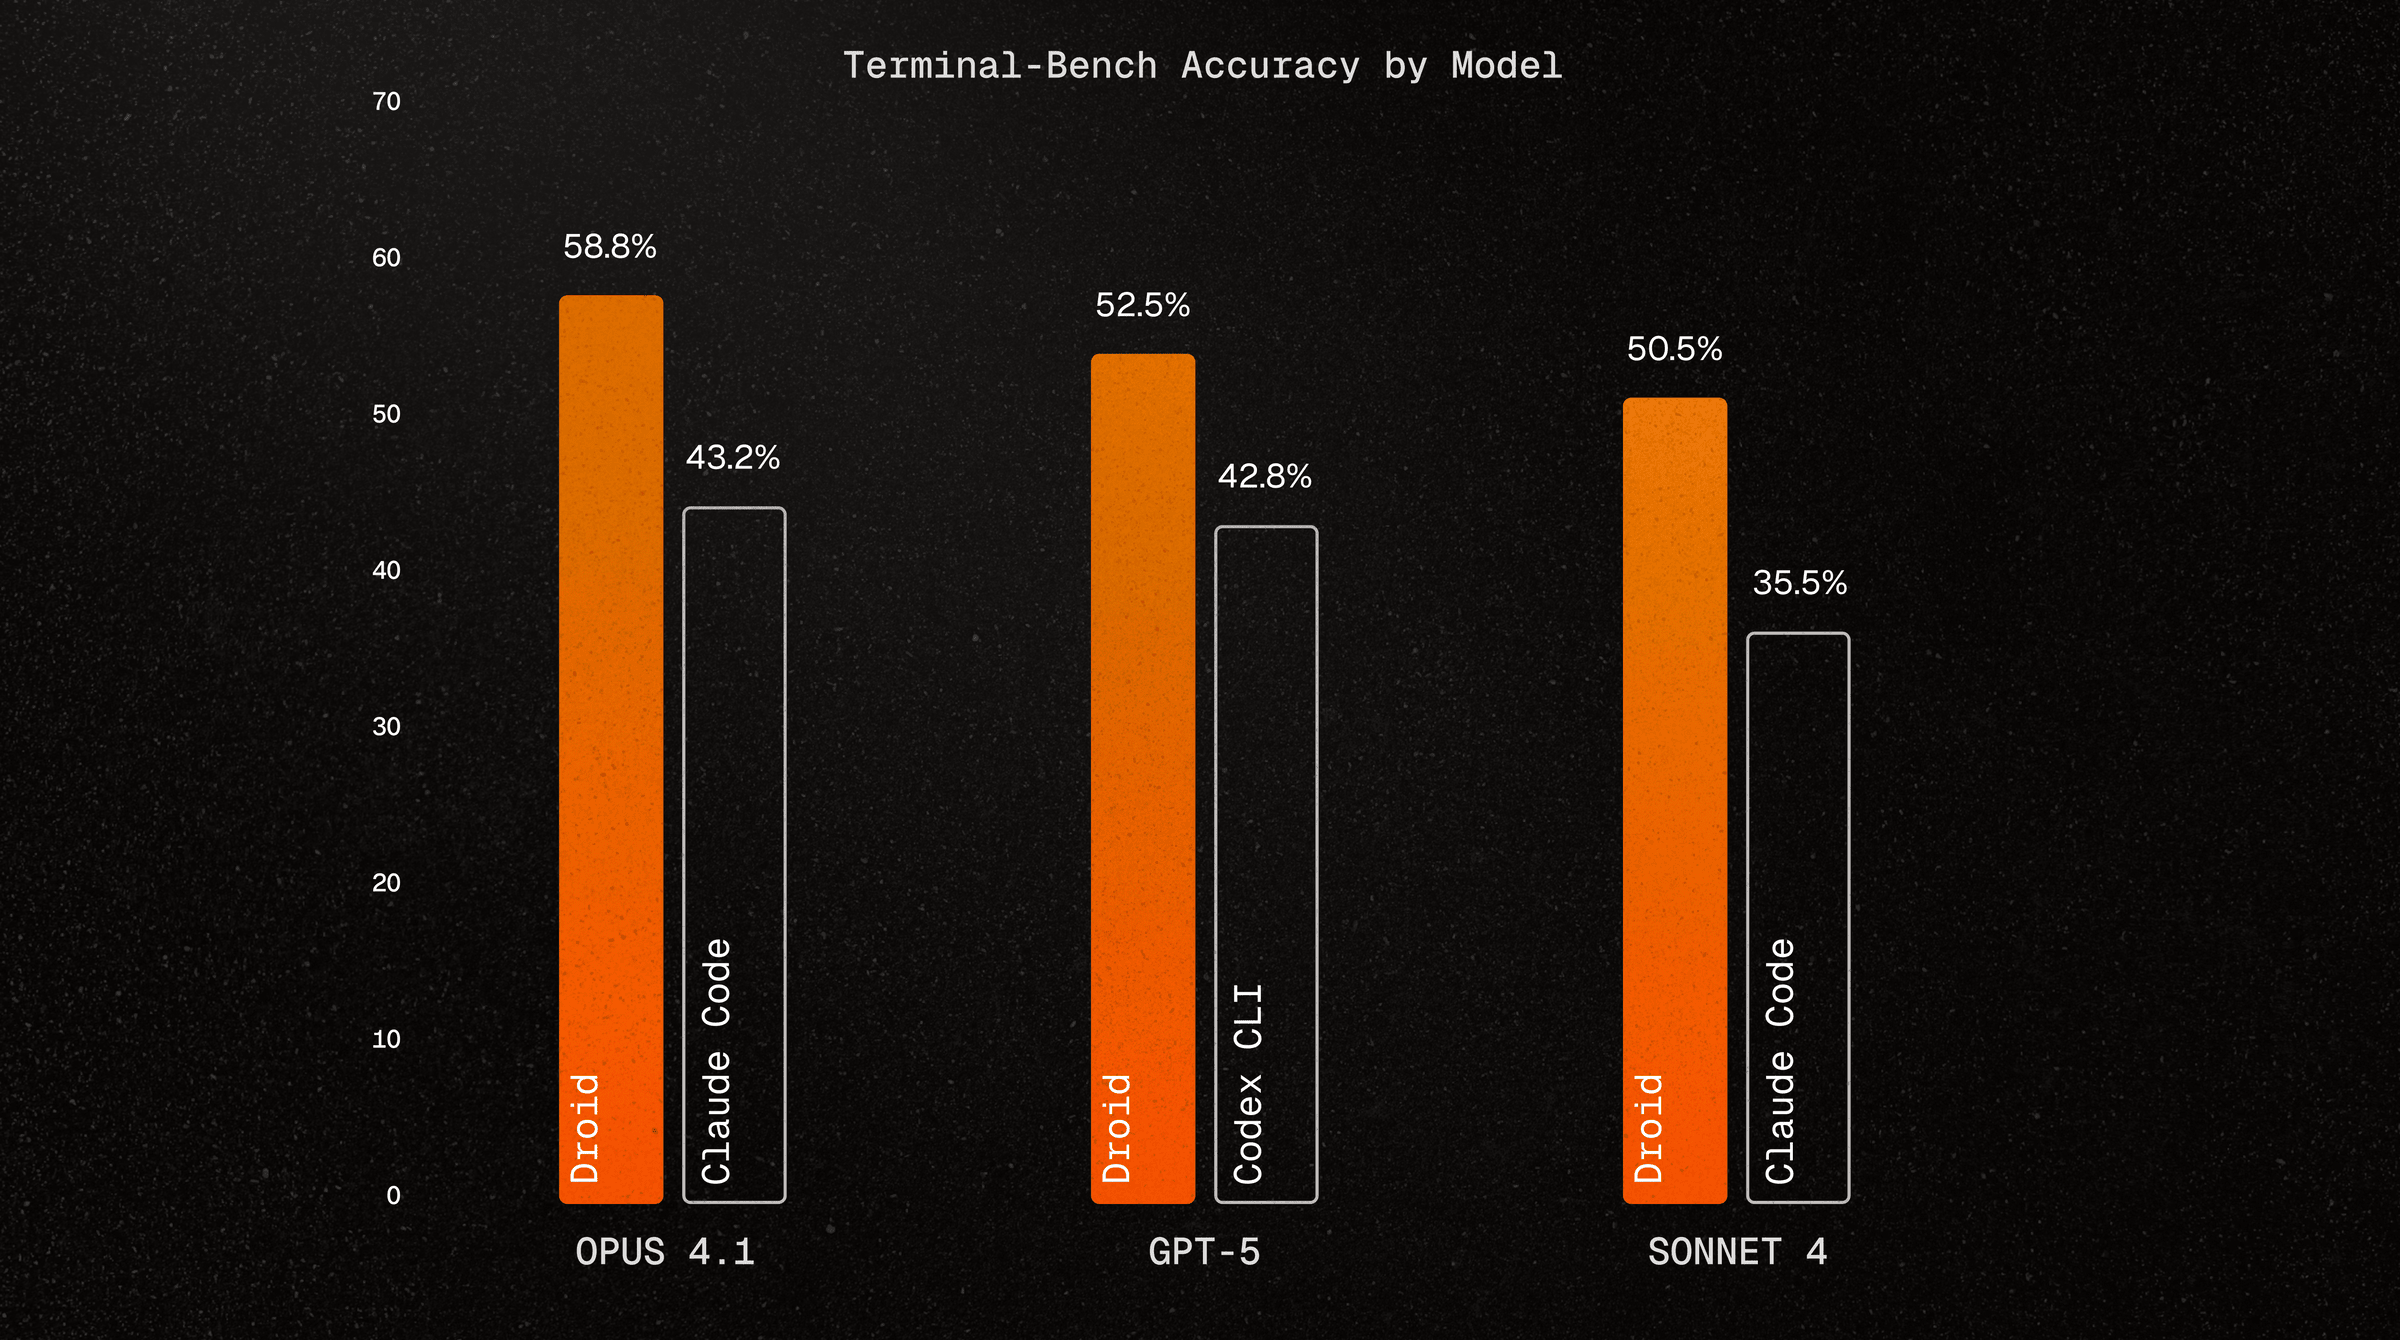
Droid: The #1 Software Development Agent on Terminal-Bench
- Source
- factory.ai
- Date
Context
Factory reported that Droid, its software development , scored 58.75% on Terminal-Bench in September 2025 when paired with Claude Opus 4.1 (no thinking) from Anthropic. That version, Terminal-Bench Core v0.1.1, contains 80 tasks performed through a terminal. A task counts as resolved only if every post-run test passes within its time limit. Factory ran the benchmark five times per model and submitted all runs. These are historical results for that version. Benchmark report.
The score evaluates the complete agent: the model, its tools and the software coordinating its work. Factory describes limiting and simplifying the tool set, adding model-specific tool scaffolding where behavior differed, and giving each session system information before work begins. Those details explain why a model's name alone does not describe the system being tested. System design.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
Checking sign-in…
Loading comments…