Terminal Bench
- Source
- factory.com
- Author
- Factory News
- Date
Context
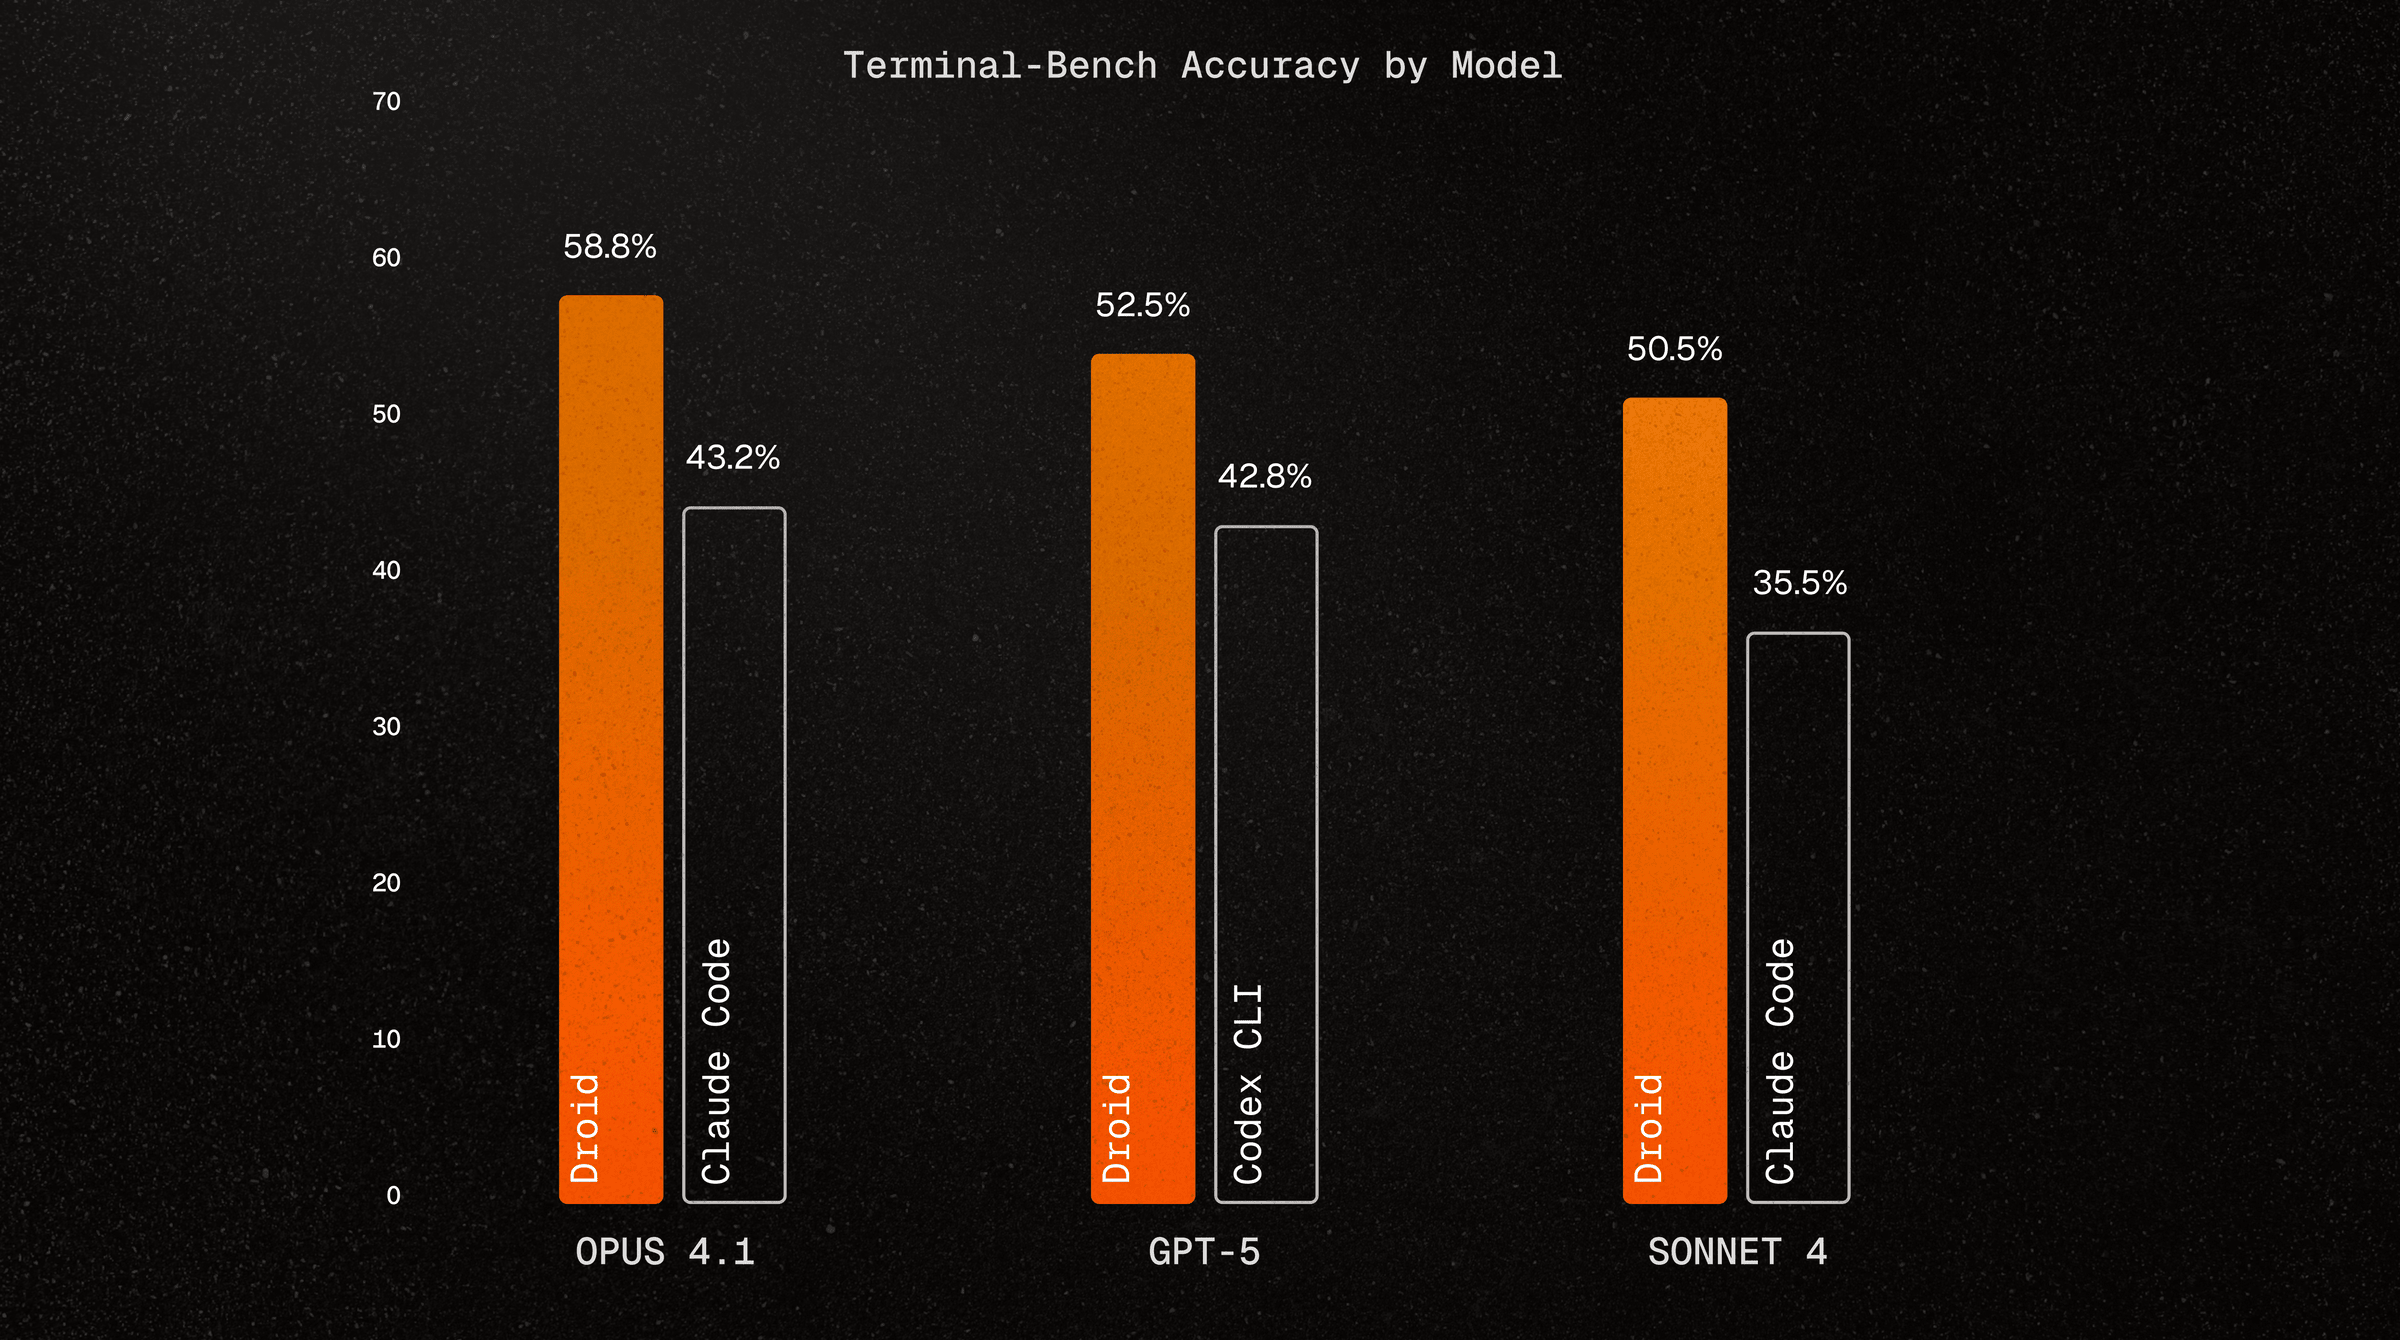
Factory reported a 58.75% task-resolution rate for its Droid coding on Terminal-Bench Core v0.1.1 using Anthropic's Opus 4.1. That contained 80 tasks performed inside isolated terminal environments, covering activities such as debugging, configuring software, and managing dependencies. A task counted as solved only when all its final checks passed within the time limit. The benchmark report therefore measures a model working through tools to finish tasks.
The accompanying design account describes model-specific editing interfaces, environment information supplied at session startup, and to command runtimes. These details make the result a measurement of the whole agent system, not a standalone model score.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
Checking sign-in…
Loading comments…