Legacy-Bench
- Source
- factory.ai
- Author
- Factory
- Date
Context
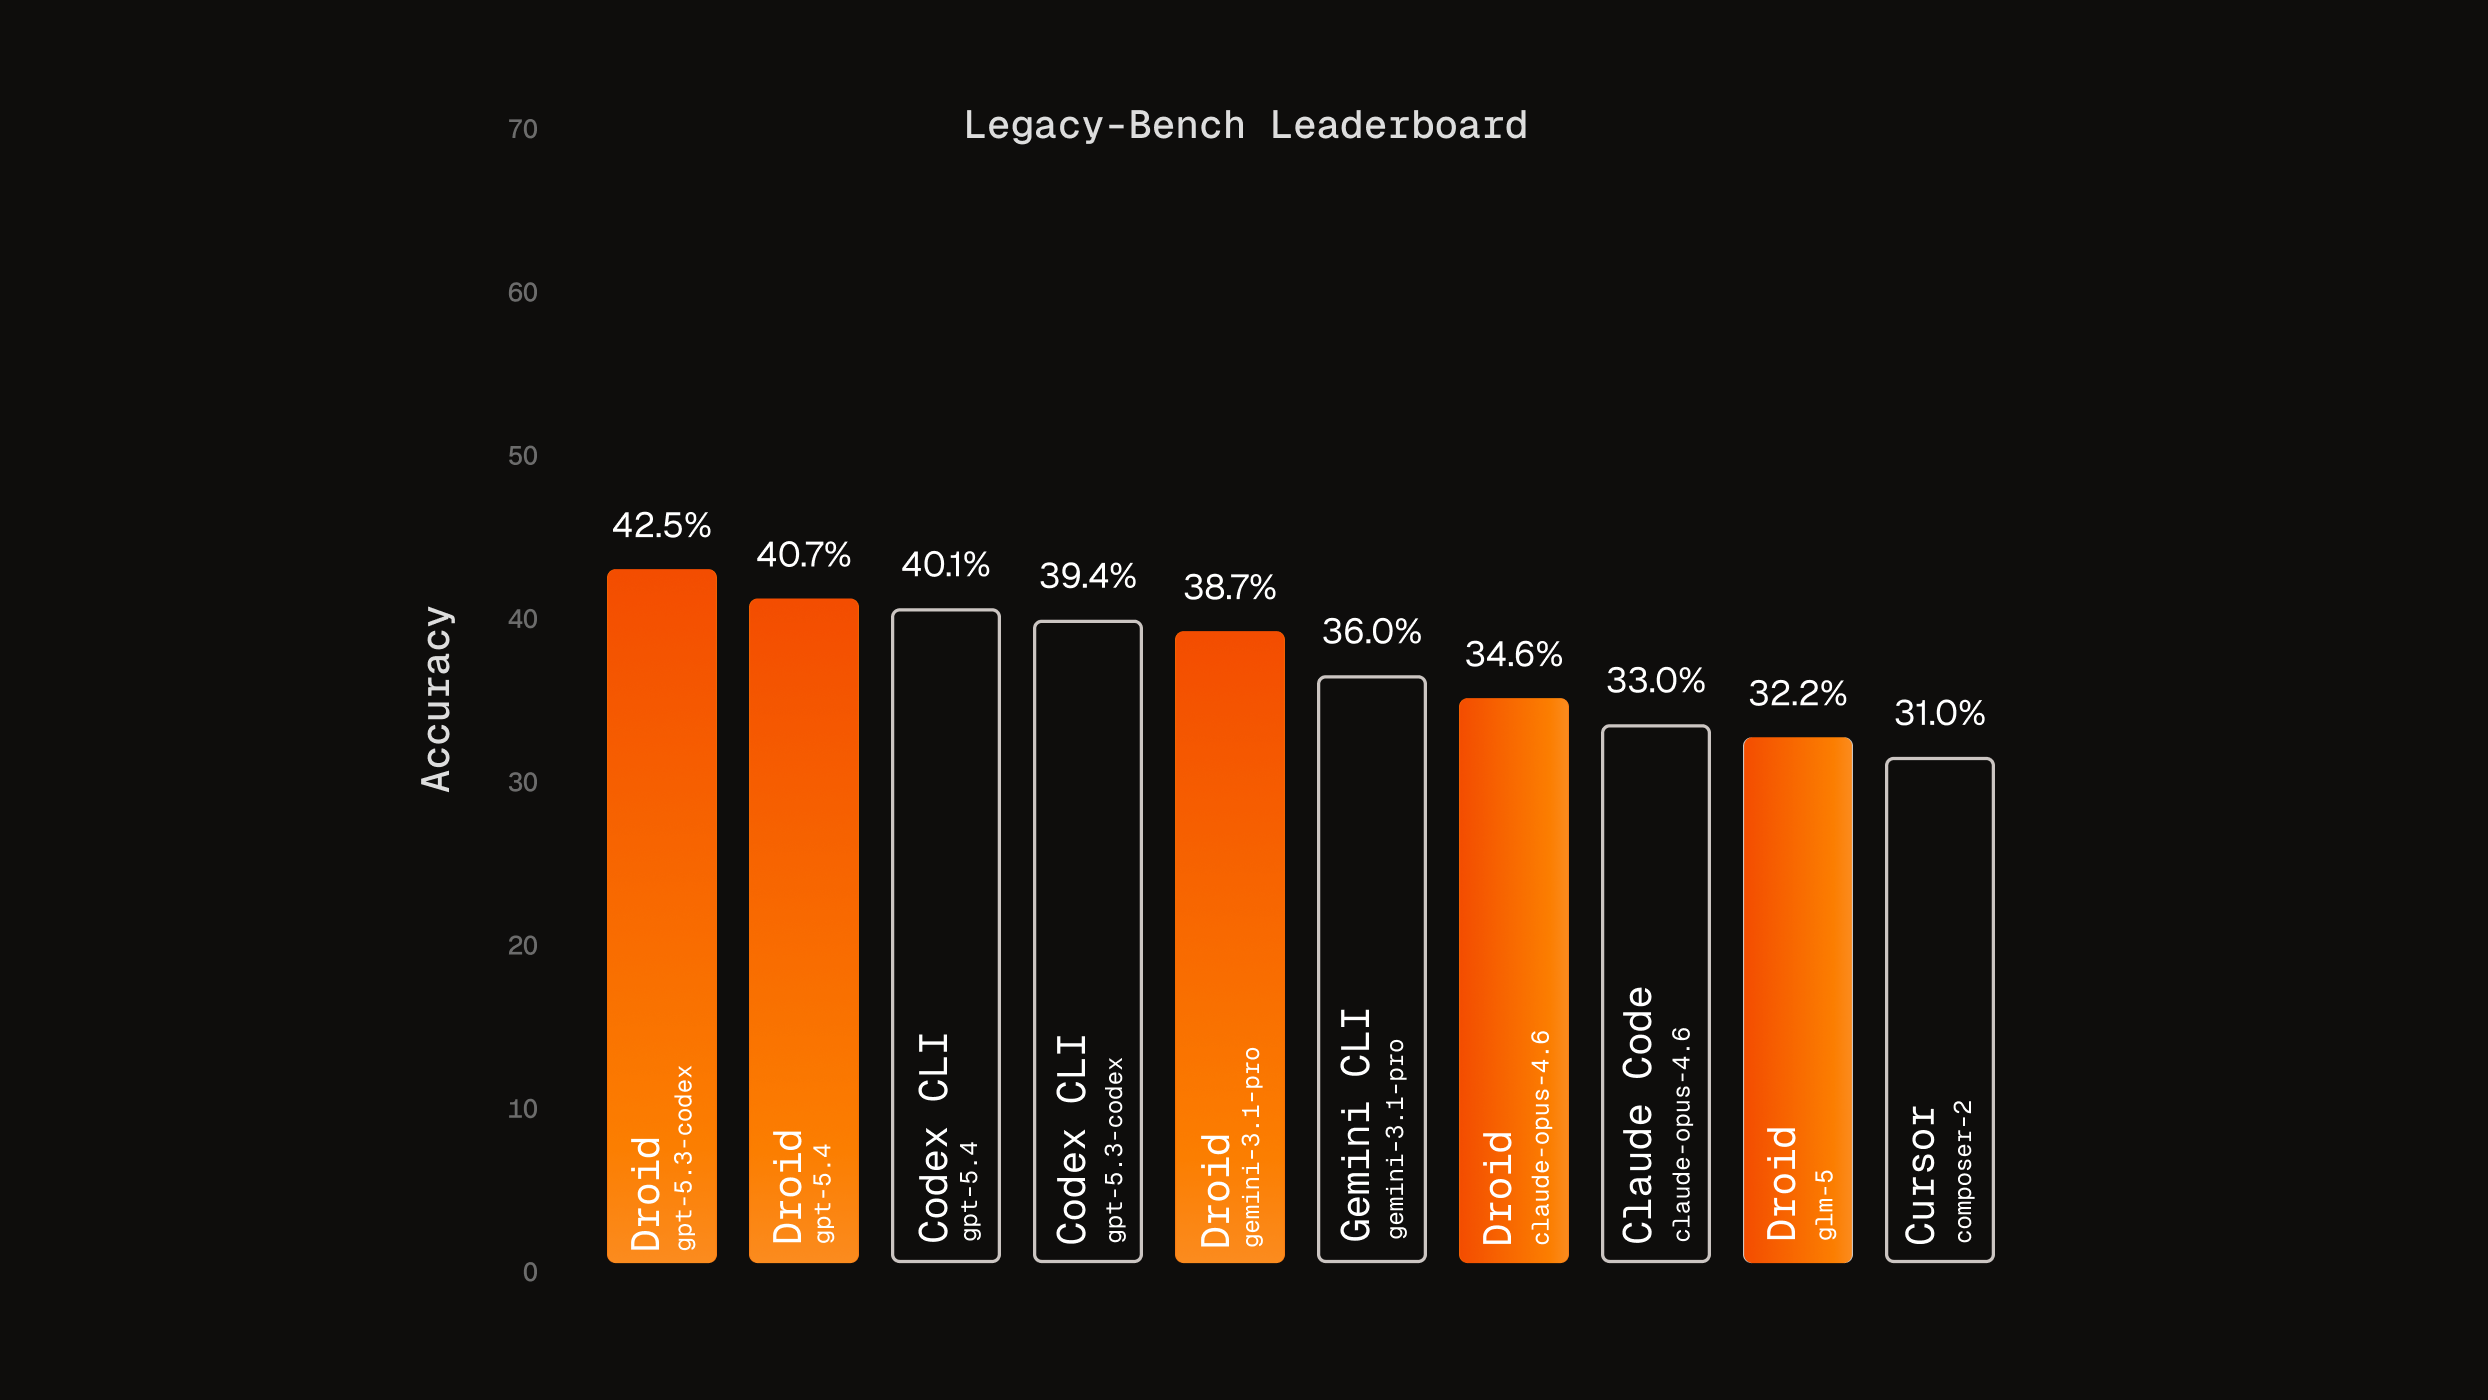
An AI coding can produce a program that runs and still calculate the wrong payment or format a record incorrectly. Factory, which develops software engineering agents, built Legacy-Bench to test such problems across older programming languages. Tasks include hidden checks of the submitted code. Its twelve tested model-agent combinations passed between 16.9% and 42.5% of tasks.
The revealing failures involved plausible output: a calculation could be wrong even when most tests passed. That makes verification of business rules and exact output formats central to evaluating these agents. The uses containerized approximations of some mainframe behavior, so its results describe that test environment rather than production mainframe performance.
Checking sign-in…
Loading comments…