Legacy Bench
- Source
- factory.com
- Author
- Factory News
- Date
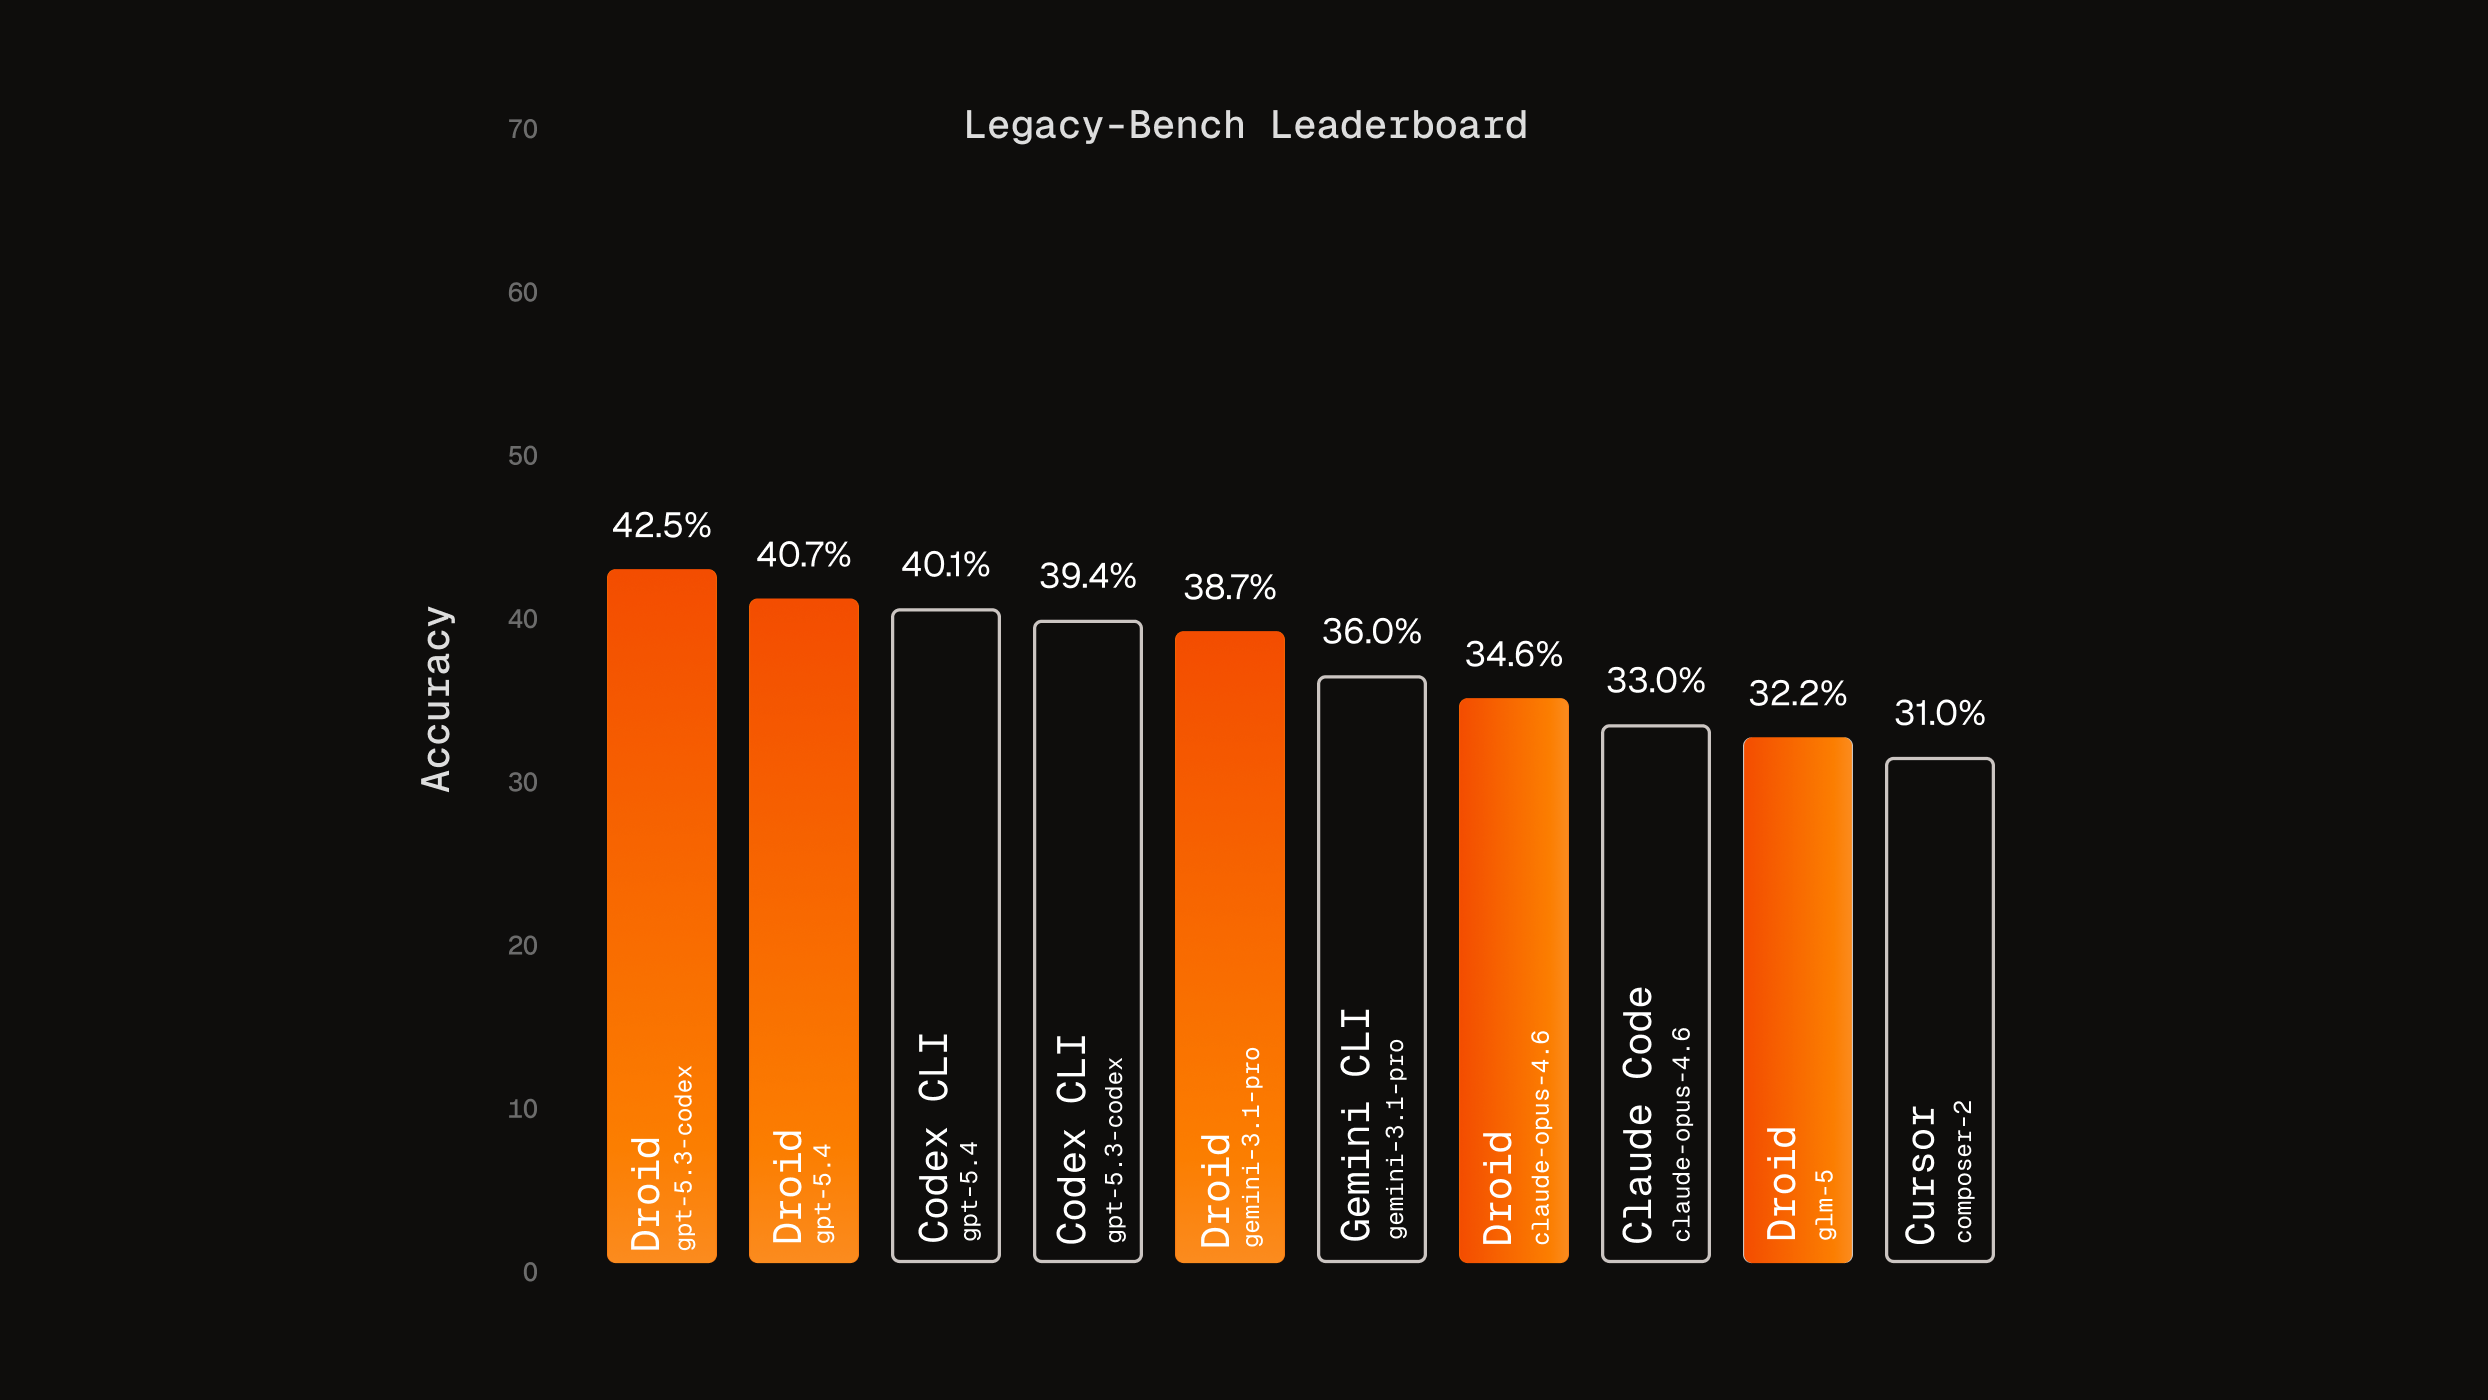
Context
Legacy-Bench, a from Factory, tests whether coding agents can preserve the exact behavior older software depends on. Its tasks include bug fixes, new functionality, and migrations in languages such as COBOL and Fortran. Agents receive working environments and instructions, but hidden tests judge their output. The benchmark report found pass rates from 16.9% to 42.5% across twelve evaluated model- combinations.
A program can compile and run while calculating the wrong amount or producing a record with incorrect field widths. Those failures explain why successful execution alone is a weak completion signal for this work. The approximates some mainframe-specific behavior, so its results apply to the supplied test environments.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
Checking sign-in…
Loading comments…