GLM-5.3-Flash's 100T daily tokens reportedly served on Chinese chips
- Source
- x.com
- Date

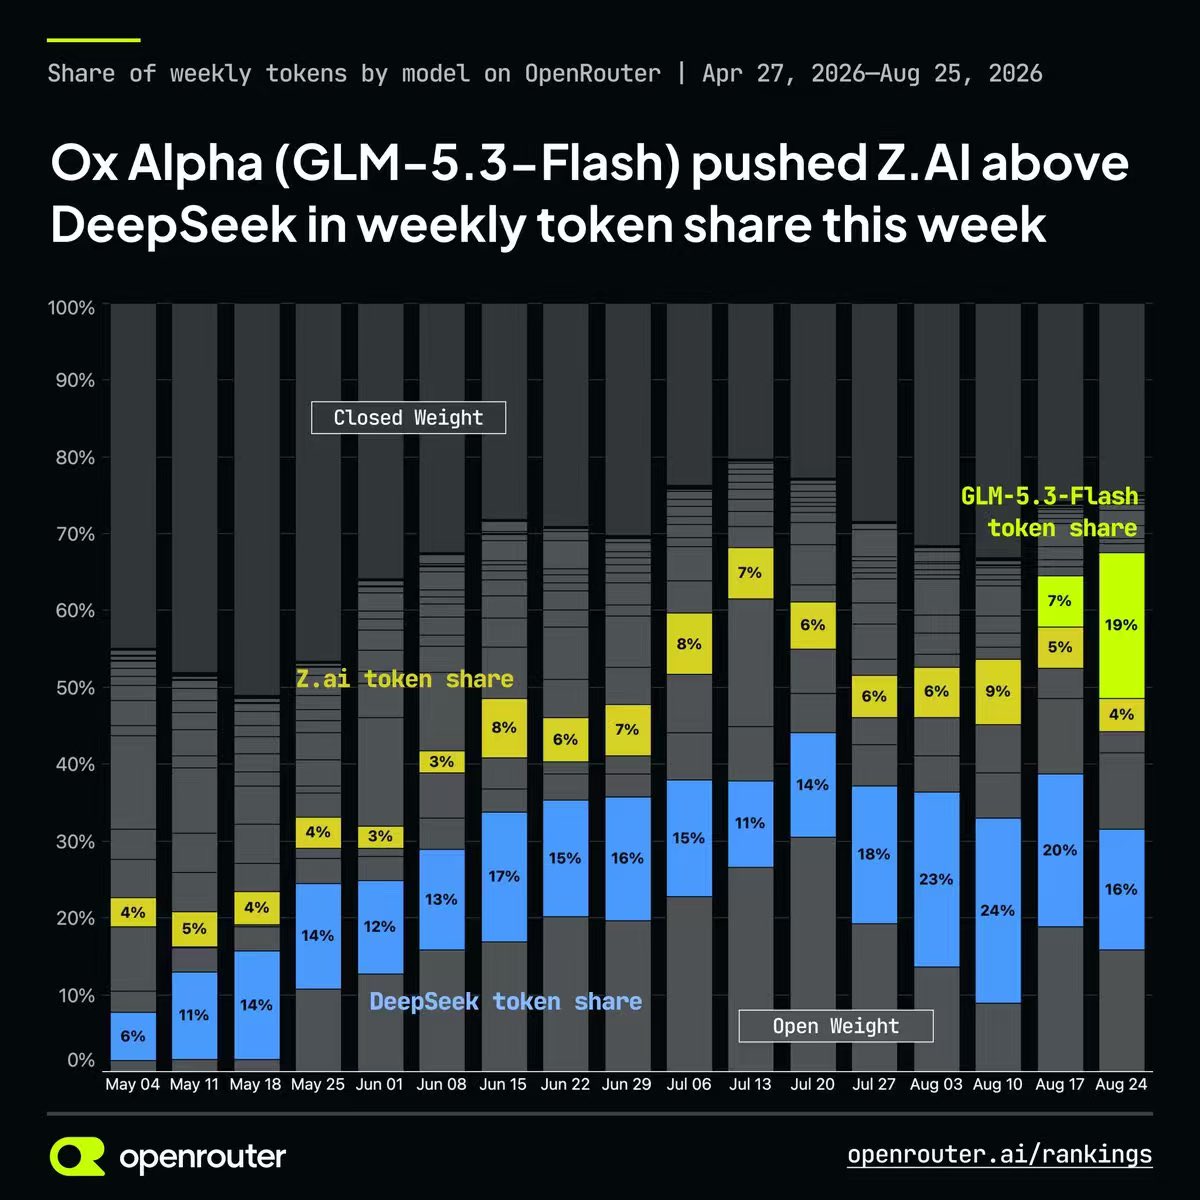
Ox Alpha has been unveiled as GLM-5.3-Flash, but what's shocking is that the 100T tokens per day is served on Chinese chip. (1/3)🧵

100T tokens per day free tokens and people were saying only frontier labs has this amount of compute. (2/3) https://t.co/7DyX5G8bpx
But ALL traffic was served on Chinese chips, attaining hardware efficiency and per-token cost comparable to Nvidia GPUs. The cuda moat is being tested once again after Jalapeño's announcement yesterday. (3/3)

Context
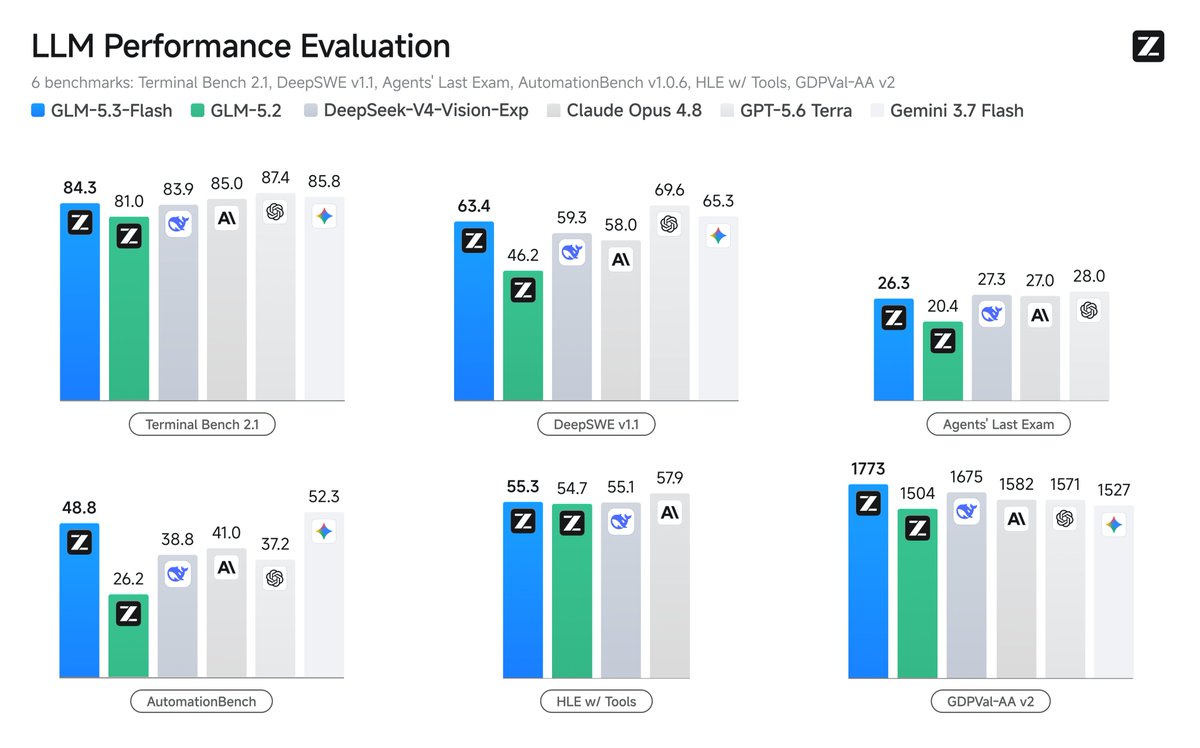
Z.ai says it served GLM-5.3-Flash, the model behind the anonymous Ox Alpha trial, on a large-scale cluster of Chinese AI chips. Its technical account describes serving software tailored to those chips: aggressive memory optimization, plus separate worker pools for encoding inputs, prefilling prompts, and generating answers. Z.ai reports a threefold end-to-end serving improvement over its initial baseline on the same hardware, and itself says efficiency and per- cost are comparable to mainstream NVIDIA GPUs.
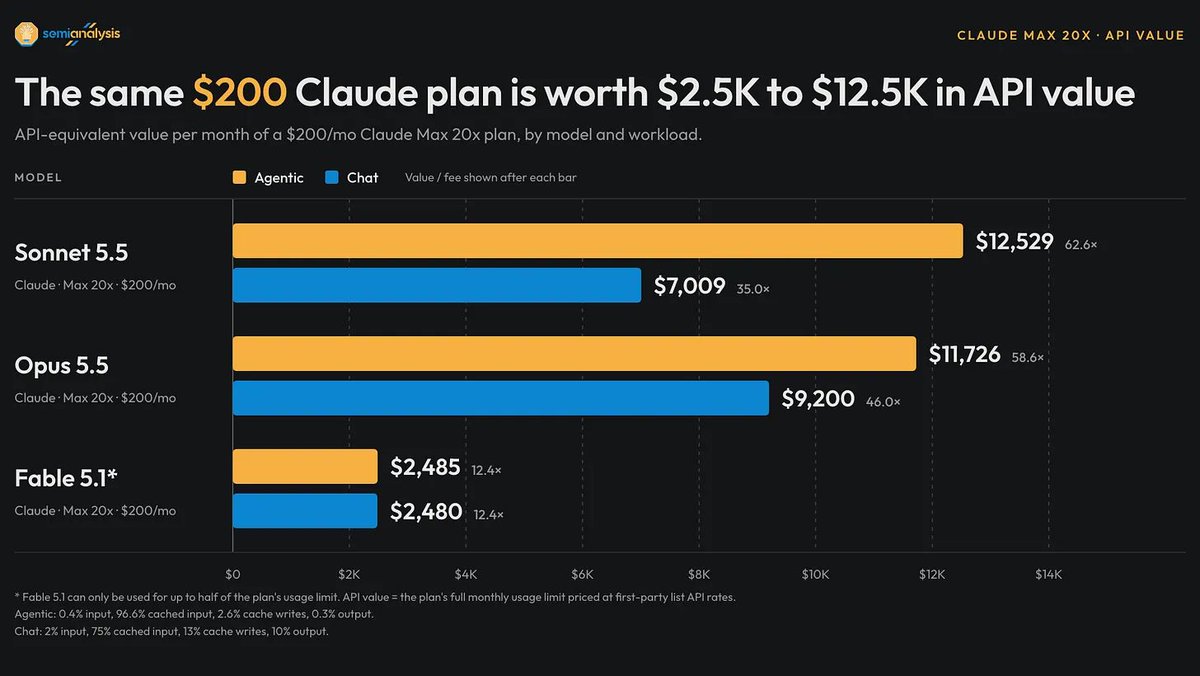
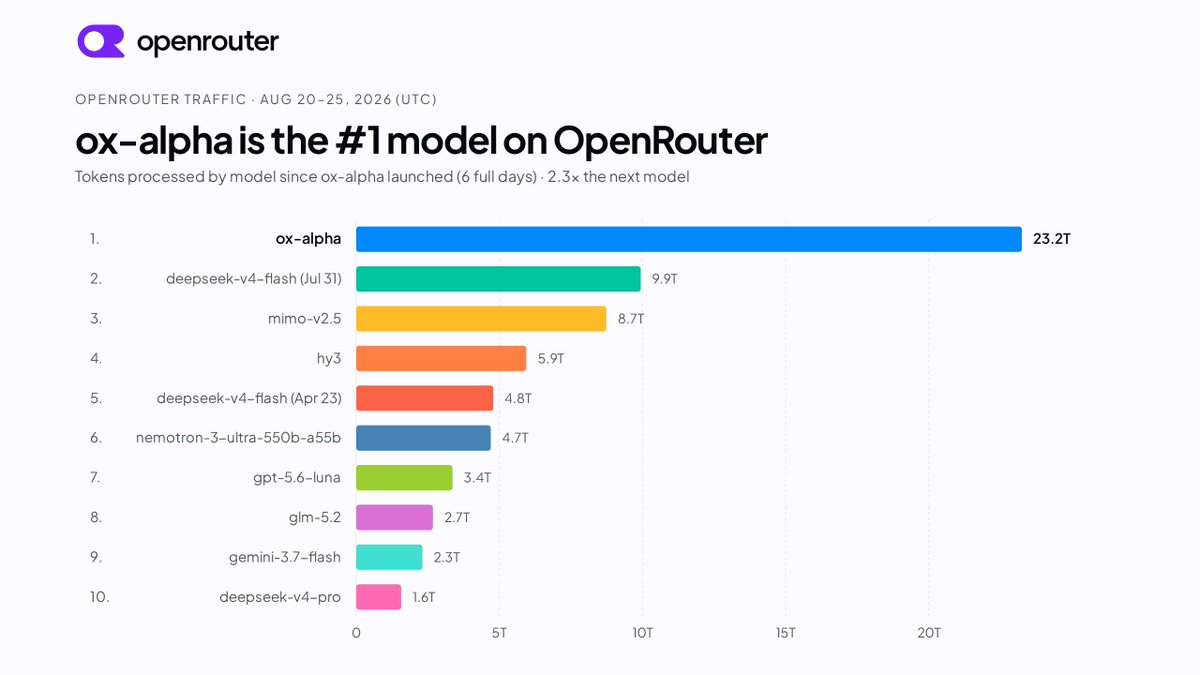
SemiAnalysis's post goes further, saying all traffic ran on Chinese chips and citing 100 trillion free tokens per day. Its attached chart, however, records 23.2 trillion tokens processed through OpenRouter across August 20–25. That chart establishes neither 100 trillion tokens delivered daily nor independently measured hardware cost parity; the parity claim is Z.ai's own.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…