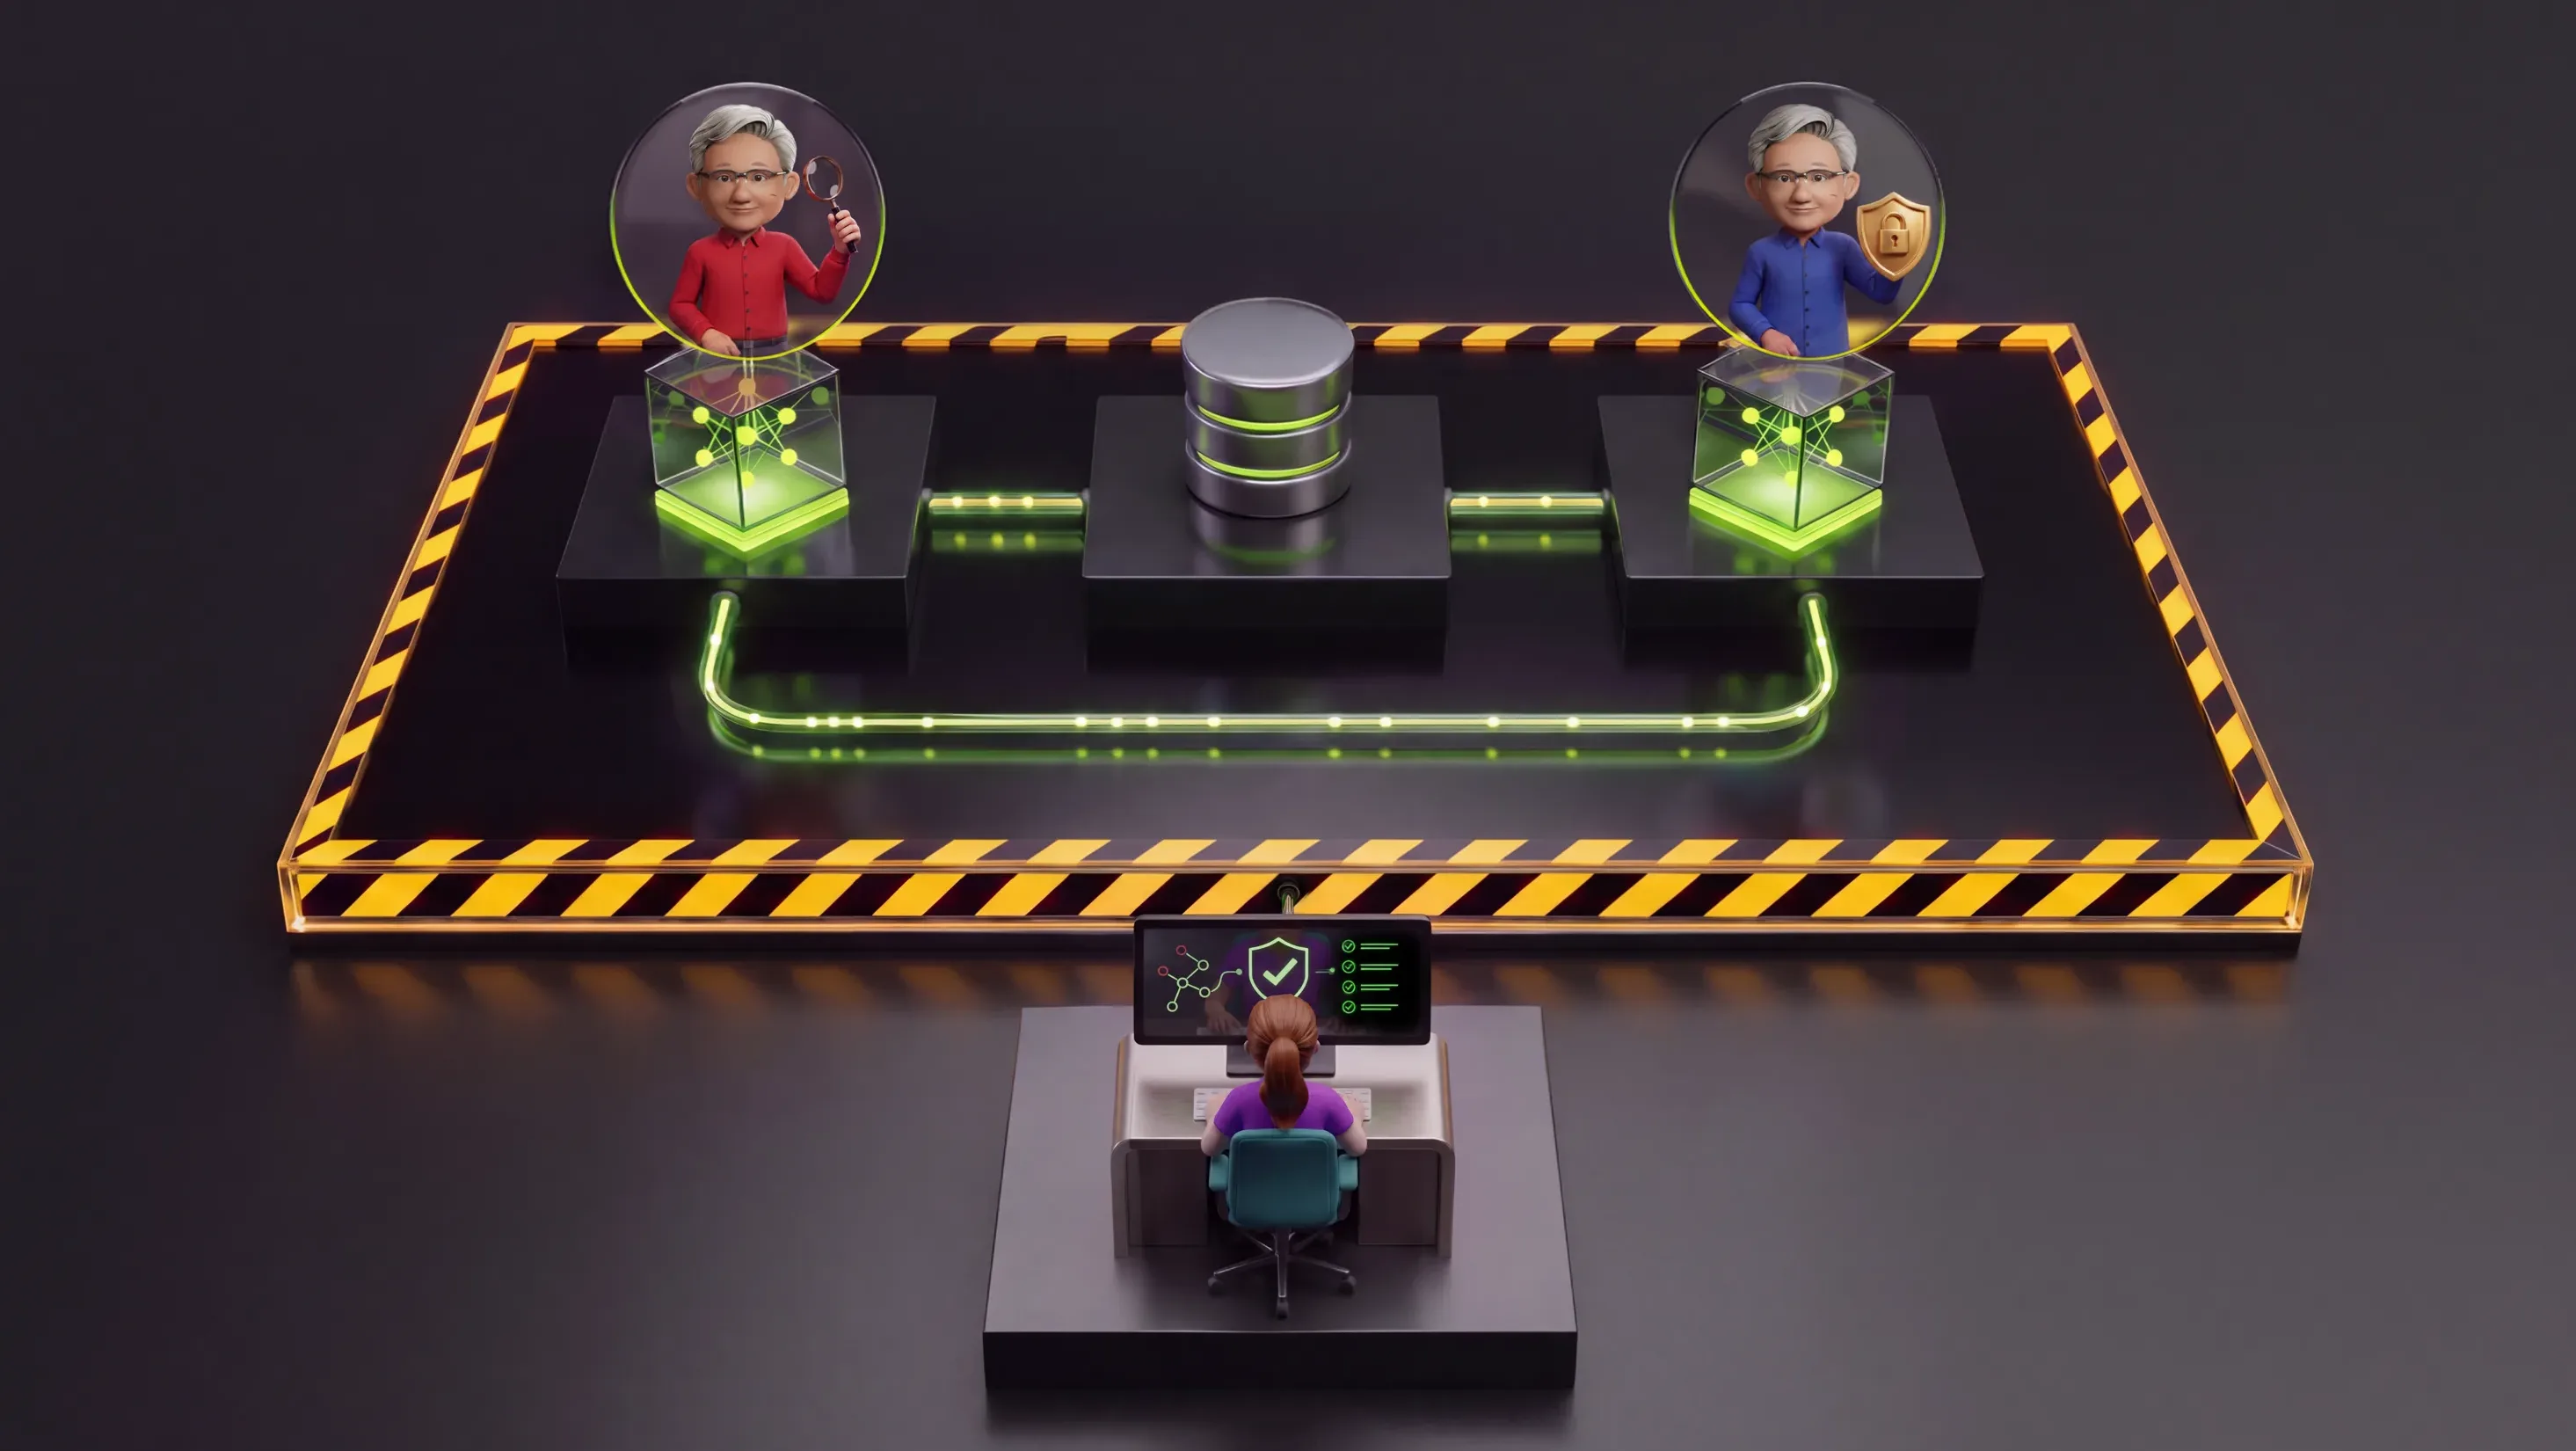
Restore LLM Inference Capacity in Seconds with Shadow Engine Recovery in NVIDIA Dynamo
Source
developer.nvidia.com
Author
Michelle Horton
Date
Why it matters
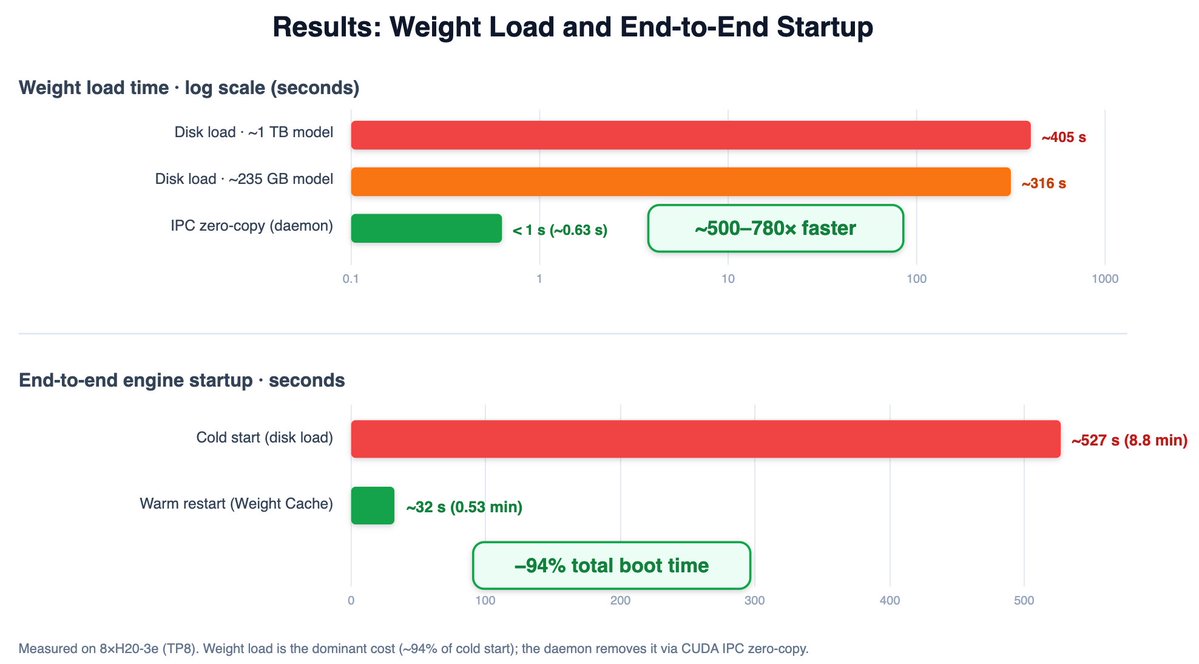
Decoupling weight lifetime from the engine process turns an inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → worker crash from a multi-minute capacity hole into seconds, at minimal extra HBM.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.