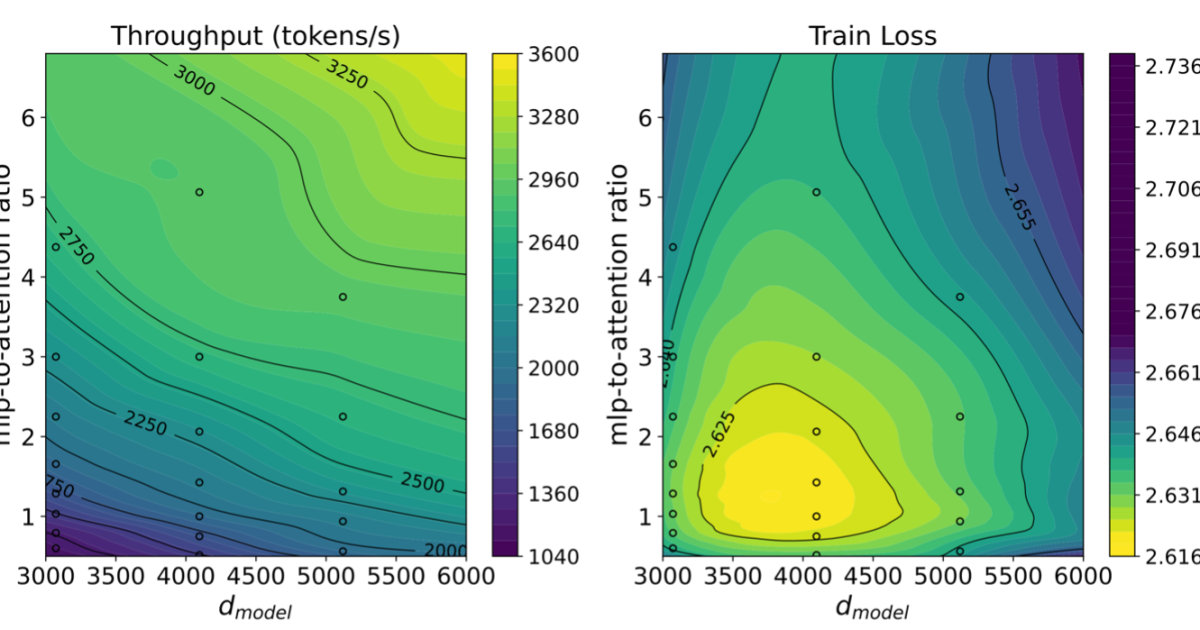
It reset how everyone spends a training budget. That a smaller model trained on far more data beats a larger undertrained one is why model sizes stopped climbing while tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → counts exploded — and why a parameter count on its own now tells you almost nothing.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.