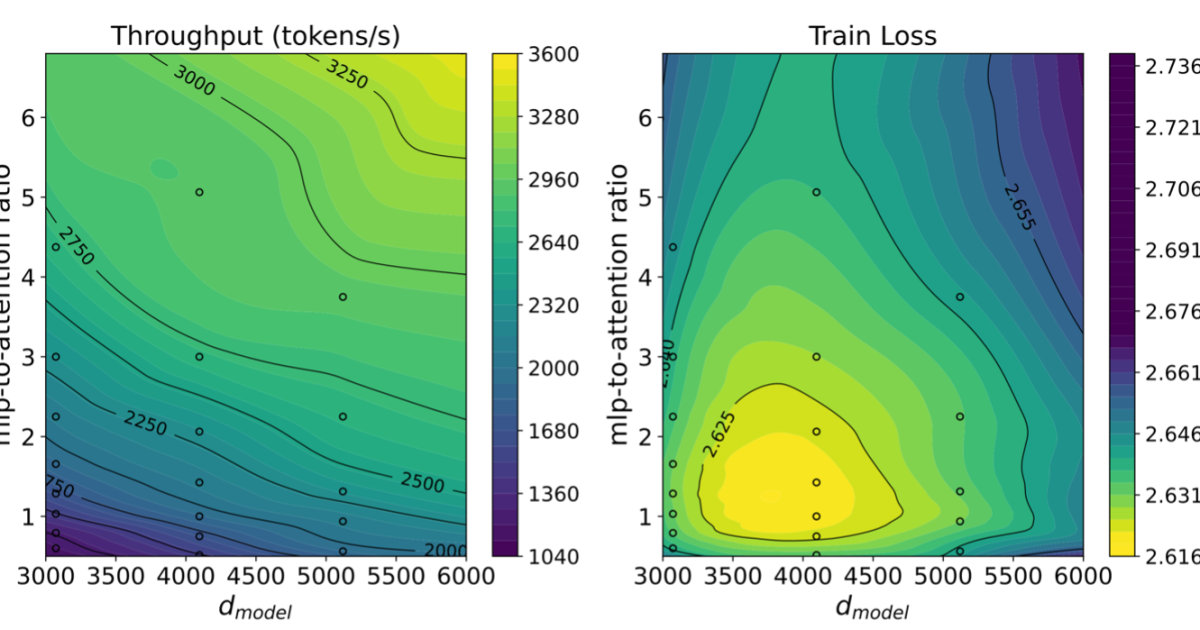
Chinchilla tells you parameters and tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → but says nothing about hidden size or how to split parameters between attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → and MLP layers — the choices that decide inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → latency. This connects scaling laws to those decisions.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.