Evaluation & Hallucination Detection for Abstractive Summaries
- Source
- eugeneyan.com
- Author
- Eugene Yan
- Date
Context
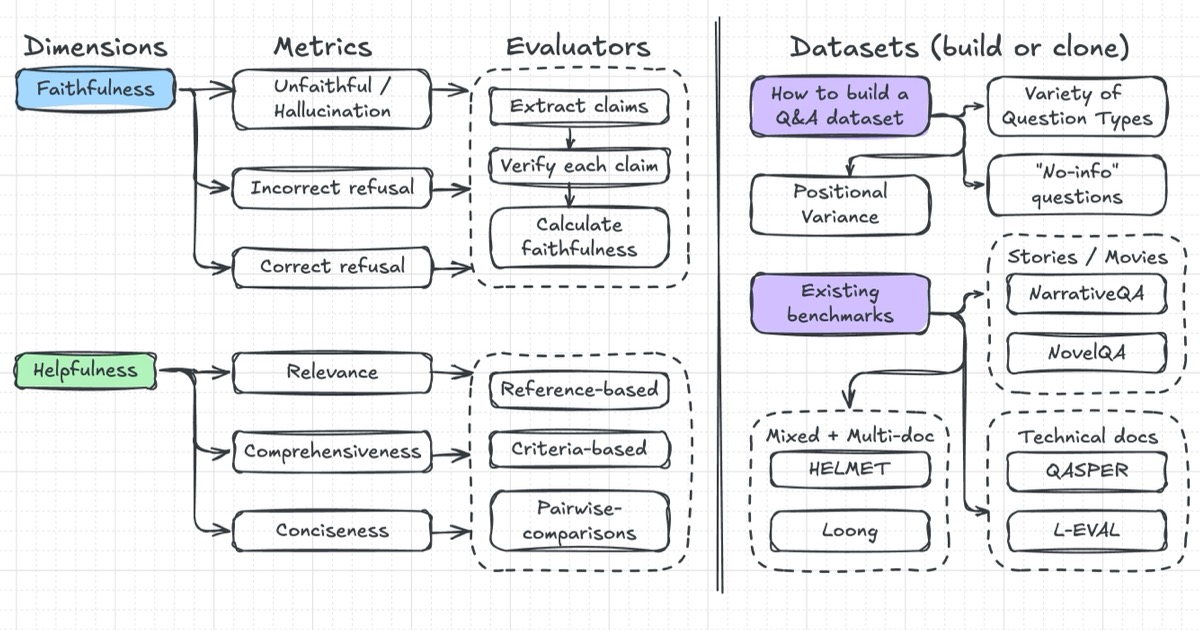
A summary can contain true information and still misrepresent its source by adding facts the source never supplied. Eugene Yan's summarization survey distinguishes that source faithfulness from factual accuracy and readable prose. Each asks a different question about whether the summary is useful.
One checking method compares claims in the summary with passages in the original and predicts whether those passages support, contradict, or leave the claims unestablished. This makes the source document the reference for support, rather than treating similar wording as sufficient evidence. The checker is itself a model, so its judgments still need validation.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
“Kryściński et al. (2020) found that hallucination affects up to 30% of summaries generated from CNN/DailyMail. More recently, Pagnoni et al. (2021) found similar errors on CNN/DailyMail, with as much as 43% faithfulness errors, and XSum having 92% faithfulness errors.”
Eugene Yan
“To be explicit, we distinguish between consistency and accuracy: A summary can be accurate but inconsistent if it adds accurate information that wasn’t in the source document.”
Eugene Yan
“For example, Fabbri et al. (2021) found that reference summaries in CNN/DailyMail scored poorly on relevance, consistency, and coherence. These references were outperformed by T5, BART, and Pegasus.”
Eugene Yan
“Nonetheless, they also found that G-Eval based on GPT-4 always gives higher scores to GPT-3.5 summaries than human-written summaries, even when human judges prefer human-written summaries.”
Eugene Yan
“In the example below, if we treat the entire document as the premise, the NLI model incorrectly predicts that the summary is entailed by the document with a probability of 0.91. But if we split the document and summary into sentences, the NLI model correctly identifies the last summary sentence as not entailed by any sentence in the document.”
Eugene Yan
 articleLongNovel: A Multi-Scale Benchmark for Hallucination Detection in Long-Context Novel SummarizationRuizhi Zhang, Jinwei Chen, Xiangju Lu, He Yan, Mo Yu, Junmin Zhu, Wei Zhang
 articleUnified Hallucination Fuzzing for Multimodal Large Language ModelsPengfei Zhou, Jiajun Song, Zhiwei Tang, Yixing Ma, Xiaopeng Peng, Donghui Si, Yuhang Xu, Huiqi Song, Yiyuan Miao, Yichen Qian, Weihua Chen, Wangbo Zhao, Bohan Zhuang, Jiasheng Tang, Yang You
 articleSONAR: Task-Aware Code Summary Evaluation for LLM Consumers Without ReferencesSimantika Bhattacharjee Dristi, Matthew B. Dwyer
Checking sign-in…
Loading comments…