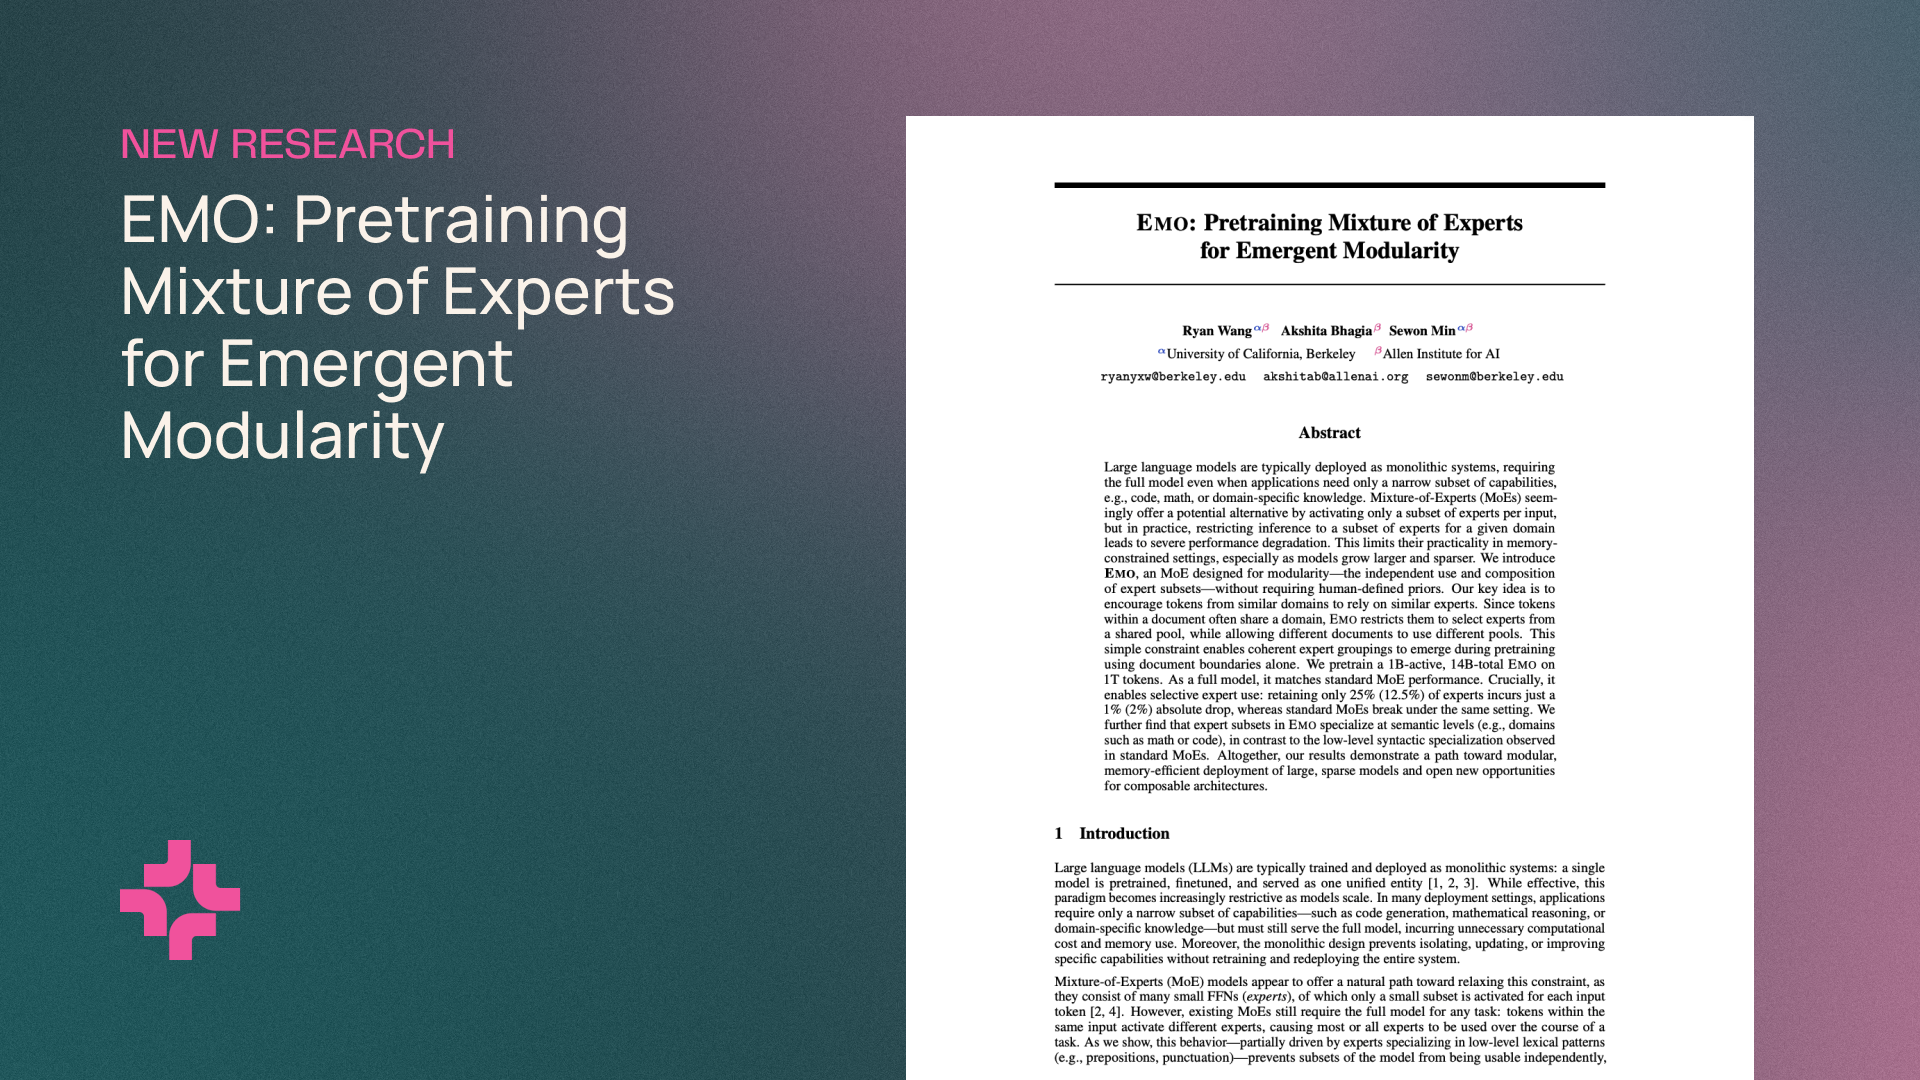
EMO: Pretraining mixture of experts for emergent modularity
- Source
- allenai.org
- Date
Context
Ai2's EMO trains a model's specialist components, called experts, to remain useful in smaller groups. During training, every text unit in a document must choose its experts from a shared pool. The model selects that pool itself, encouraging related material to use recurring groups without requiring people to label domains in advance. The release explains this training constraint.
For a particular task, researchers then retain the experts used most often on task examples. Ai2 reports that keeping one-quarter of EMO's experts reduced aggregate performance by about one percentage point. A matched conventional model deteriorated much more when reduced this way. The result supports selecting smaller task-specific models from the trained expert collection.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.

Checking sign-in…
Loading comments…