Your Experts Have Partners. There's HOPE for Keeping Them Together
- Source
- huggingface.co
- Date
Context
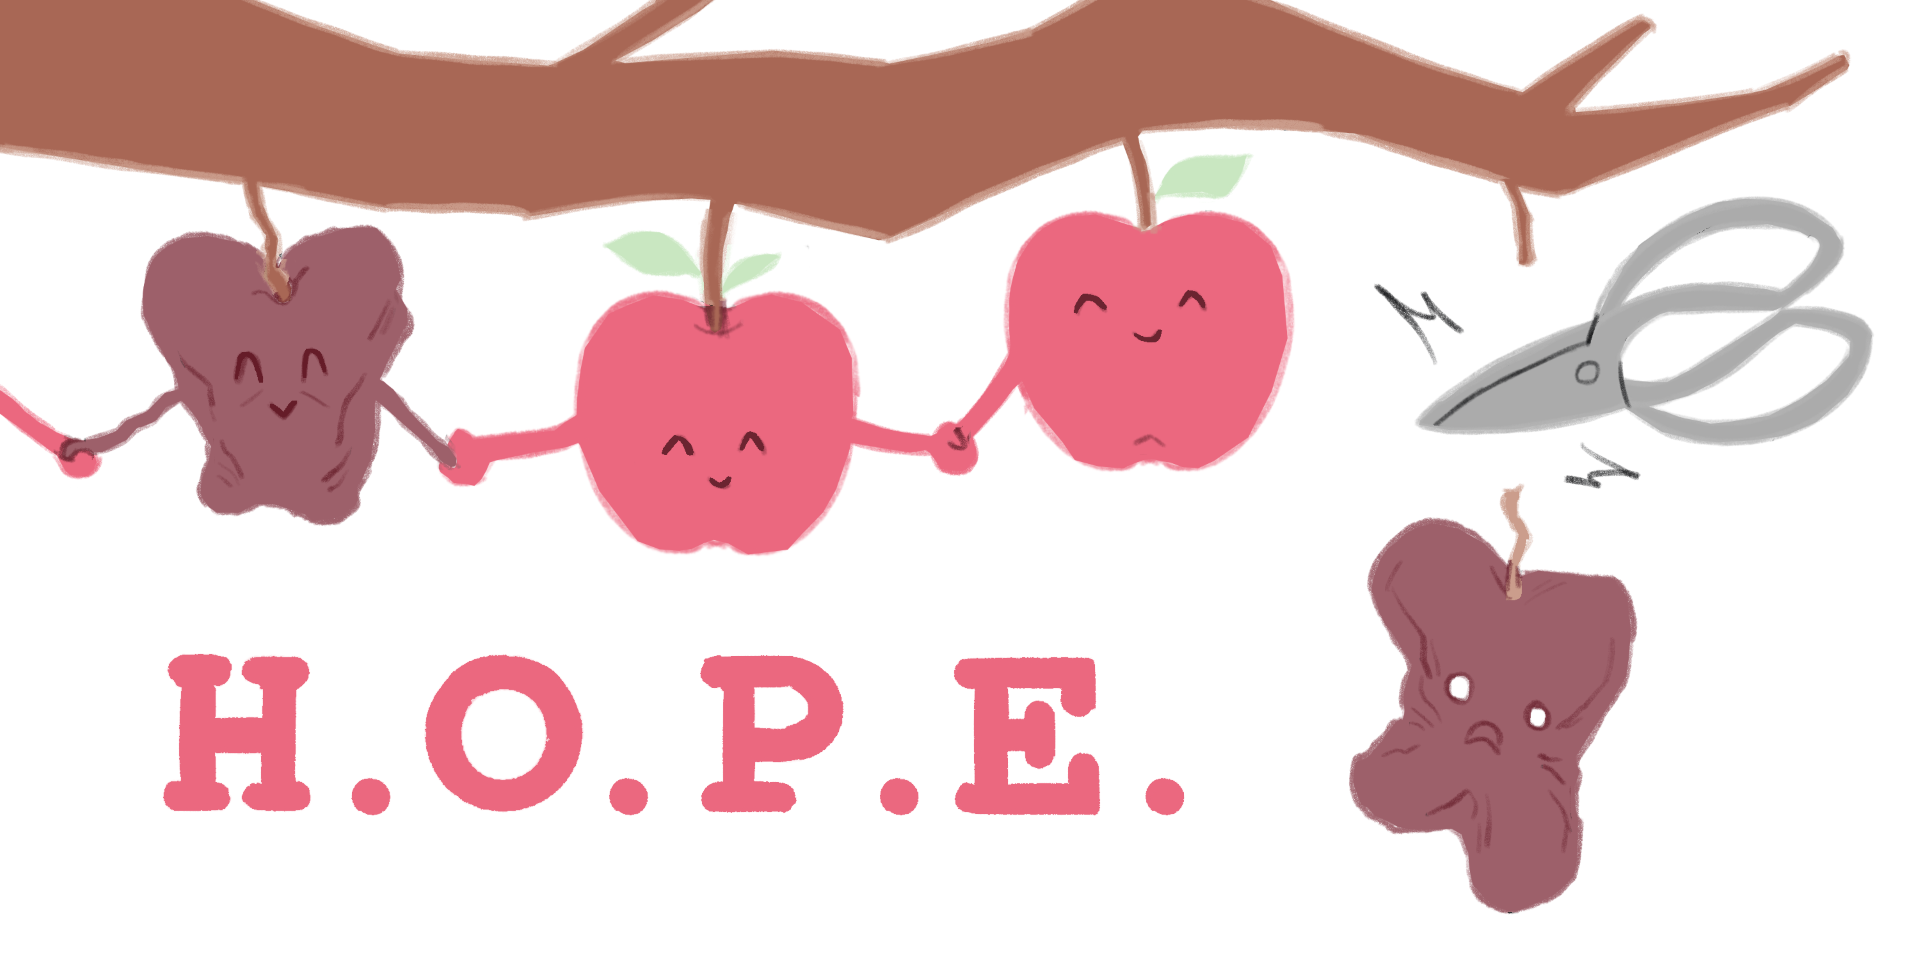
Amazon researchers have published HOPE, a method for shrinking language models by deleting parts of them, and its central idea is that the choice of what to delete should account for parts that are habitually used together. In a mixture-of-experts (MoE) model, each layer contains many small sub-networks called experts, and a router picks a few of them for each token. Only those few do any work, but every expert has to stay loaded in memory. Alex M Tseng's Hugging Face post gives Qwen3.5-122B as an example: 256 experts in each of 48 MoE layers, 8 used per token, with experts accounting for 95% of its roughly 250 GB of parameters.
Expert pruning removes experts permanently, which shrinks the model without retraining. Existing methods run a sample of text, the data, through the model, give each expert its own importance score and delete the lowest scorers in each layer. HOPE also scores each pair of experts that the router selects for the same tokens, weighted by how much each contributes to the output, and then chooses the set to delete that minimizes an upper bound on how much the layer's output changes. Solving that takes a second or two per layer on top of the usual calibration pass. In the post's example, an expert that looks unimportant on its own may be worth keeping because an important expert regularly works alongside it and relies on it, where a one-at-a-time score would drop it. The paper shows that REAP, which the authors describe as the leading earlier method, is the special case of HOPE with the pair terms left out, so any gain over REAP comes from those terms.
The authors tested HOPE on Qwen3.5-122B, Qwen3.5-35B and GLM-4.5-Air, removing between 10% and 50% of experts and comparing it with four methods that score experts one at a time. Ranked across all those conditions, HOPE placed best on average, 2.07 among 5 methods, and its lead widened at 50% pruning, an average rank of 1.58 against 2.42 for REAP. The clearest example is Pro, a test in which a model works through real GitHub issues on its own. With half its experts removed, the HOPE-pruned Qwen3.5-35B-A3B scored 42.3, against 41.8 for the unpruned model and 36.2 for the version pruned with REAP. At 10% to 20% pruning, the authors say methods like REAP are sometimes competitive.
These are the authors' own experiments, calibrated on coding data, and the post notes that pruned models from any method occasionally match or beat the original, so one score at or above the unpruned model does not by itself show that nothing was lost. HOPE handles each layer separately and considers only pairs of experts, not larger groups or links between layers. According to the post, the code produces standard Hugging Face checkpoints that are smaller on disk and in memory, and it has been tested on Qwen3, Qwen3-Next, Qwen3.5 and GLM-4.5 models, but the post gives no measured sizes or speeds.
- Existing expert-pruning methods score each MoE expert on its own, but experts form stable groups that are routed together. HOPE, from Amazon researchers, adds pairwise interaction terms so removing one expert is weighed against the partners that rely on it.
- HOPE frames pruning as a quadratic program over an expert-interaction matrix collected in the same single calibration pass other methods use. The authors report the solve takes about 1-2 seconds per layer, so calibration still dominates the cost.
- On Qwen3.5-35B-A3B with half its experts removed, the authors report HOPE scored 42.3 on SWE-Bench Pro against 41.8 for the unpruned model, while the first-order REAP method fell to 36.2.
- HOPE's edge is largest at 40-50% pruning; at 10-20%, the authors say first-order methods such as REAP and MAN are sometimes competitive. Like most expert pruners, it also prunes each layer independently and ignores cross-layer interactions.
- The released hope package runs calibrate, solve and prune steps and writes a standard Hugging Face checkpoint, so the pruned model needs no changes to vLLM or SGLang model definitions. It has been tested on Qwen3, Qwen3-Next, Qwen3.5 and GLM-4.5.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- calibration — How well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…