benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Why it matters
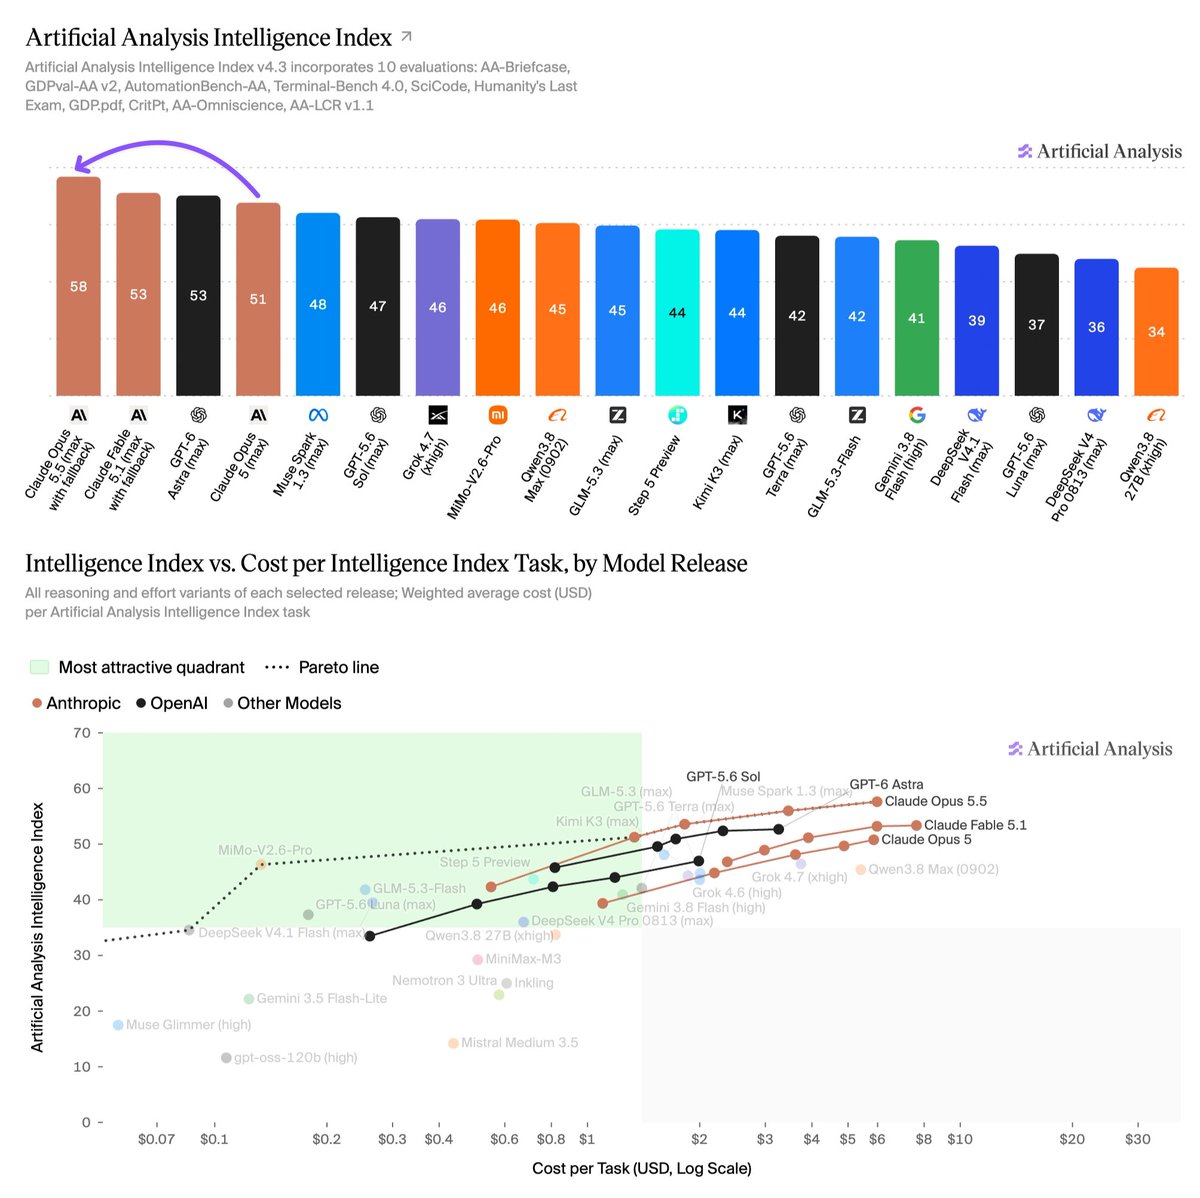
Opus 5.5 scores 62% on Terminal-Bench-Science at xhigh effort and falls to 59% at max, so choosing the effort level matters for AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → runs. The digest also compares GPT-6 variants and other new models.