US open-weights models gain on intelligence and efficiency in one week
- Source
- x.com
- Date

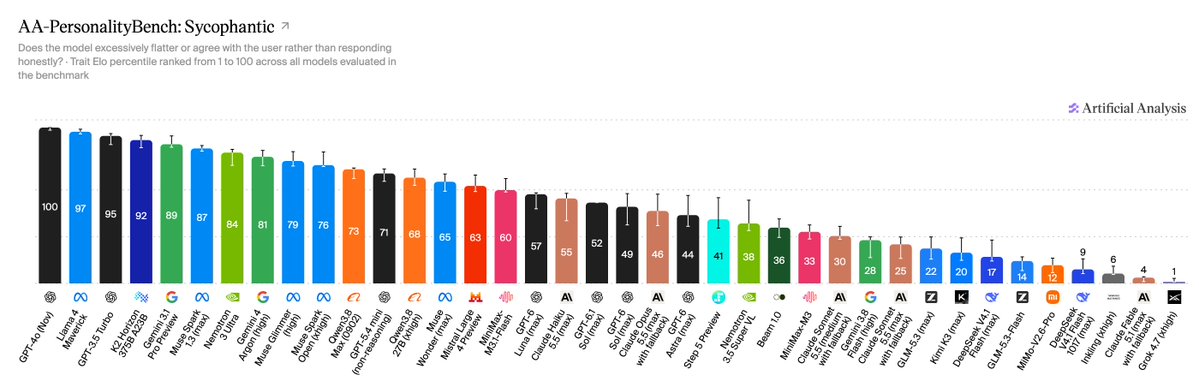
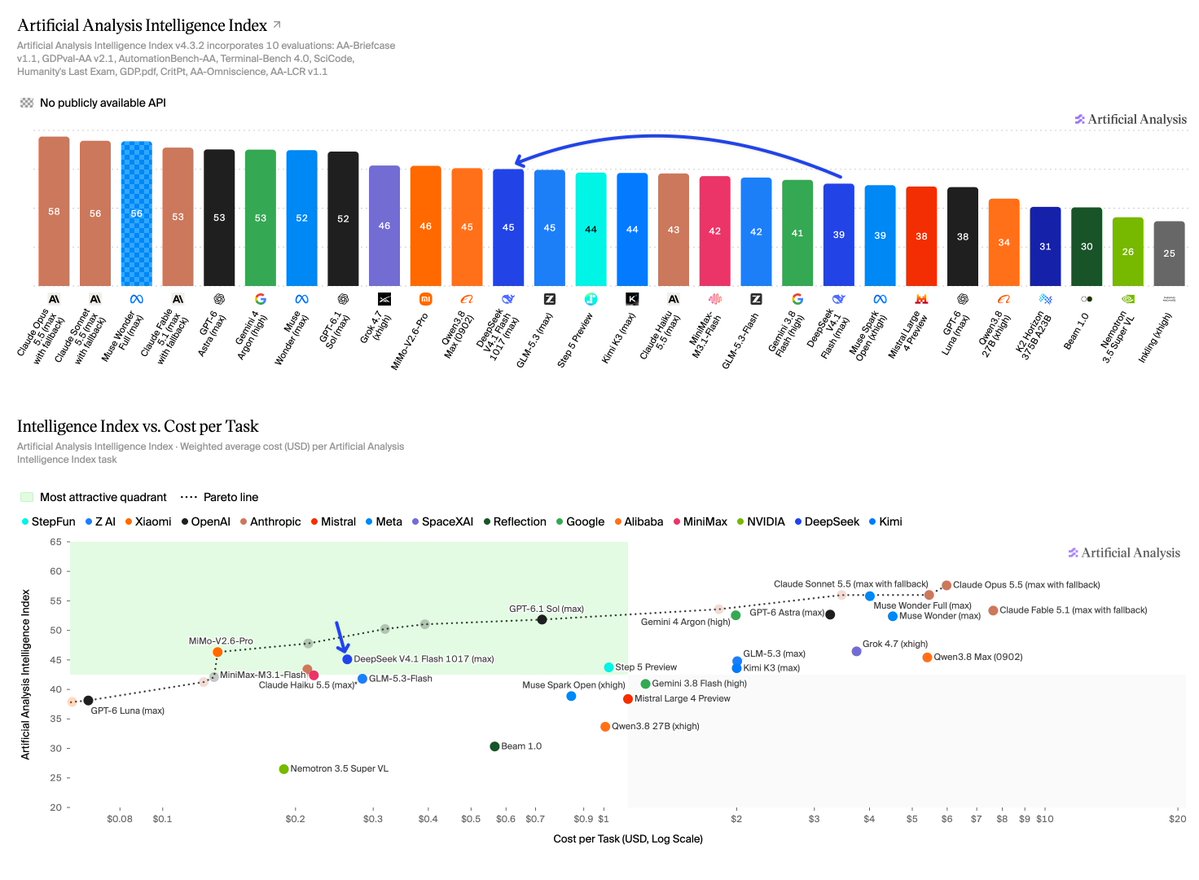
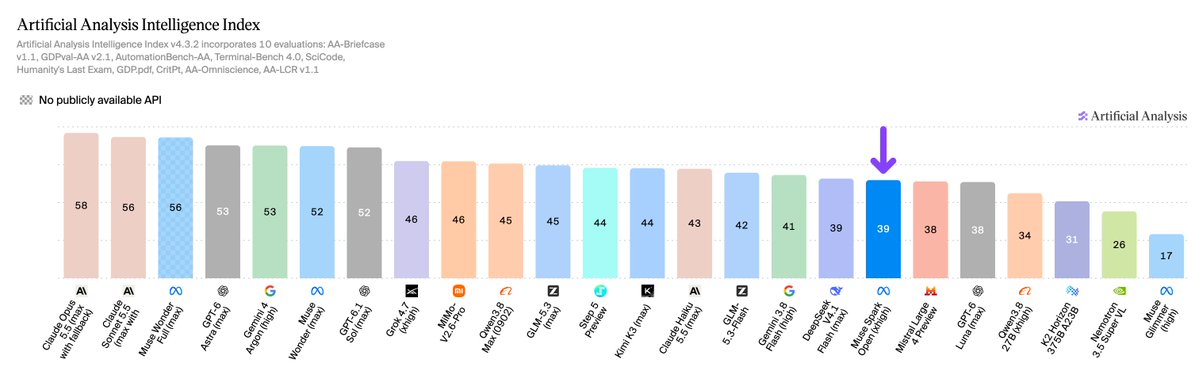
US open-weights models made gains in both intelligence and parameter efficiency last week: ➤ Thursday morning: NVIDIA released Nemotron 3.5 Bolt and Nemotron 3.5 Super VL. Super VL scored 26.5 on the Intelligence Index with 120B parameters, pushing Inkling Small off the Pareto frontier ➤ Thursday midday: Meta's Muse Spark Open scored 38.9, more than 12 points ahead of Super VL and the highest intelligence yet for a US open weights model ➤ Friday morning: Beam 1.0, Reflection's first model, scored 30.3 with 501B parameters, joining the frontier between Super VL and Muse Spark Open See our full comparison of open weight models on Artificial Analysis

Context
This Artificial Analysis recap tracks two kinds of progress for US open-weights models, meaning models whose weights anyone can download and run themselves. One is the best score, and the other is the best score for a given size. Both use the Artificial Analysis Intelligence Index, a composite of ten evaluations. Size is measured in parameters, the trainable weights a model learns, counted in billions. The efficiency claims rest on a Pareto frontier: plot intelligence against parameter count, and a model sits on the frontier when no other model is both smaller and higher-scoring. A new model that pushes an old one off the frontier delivers more intelligence at the same or smaller size.
According to the post, on Thursday NVIDIA's Nemotron 3.5 Super VL scored 26.5 with 120B parameters and pushed Thinking Machines' Inkling Small off the frontier. Meta's Muse Spark Open then scored 38.9, more than 12 points ahead of Super VL and, by Artificial Analysis's count, the highest yet for a US open-weights model. The next morning, Beam 1.0, the first model from Reflection, scored 30.3 with 501B parameters. That put it on the frontier between the other two: larger than Super VL but stronger, and smaller than Muse Spark Open but weaker. Artificial Analysis covered the two bigger launches separately on the day, with Muse Spark Open at 39 and Beam at 30.
The US qualifier matters. On Artificial Analysis's open-weights comparison page, the top scores belong to models from labs outside the US. Xiaomi's MiMo-V2.6-Pro scores 46, and DeepSeek V4.1 Flash and Z.ai's GLM-5.3 score 45 each. Muse Spark Open's 39 places it below those. The same page also separates total parameters from active parameters, the share a model actually runs for each . Muse Spark Open has 816B total but 42B active, Beam has 501B and 23B, and Super VL has 120B and 12B. So a large total count does not translate directly into running cost.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…