Why Methods Like Qlora Fall Short In Domain Knowledge Injection 2
- Source
- arcee.ai
- Author
- Arcee AI
- Date
Context
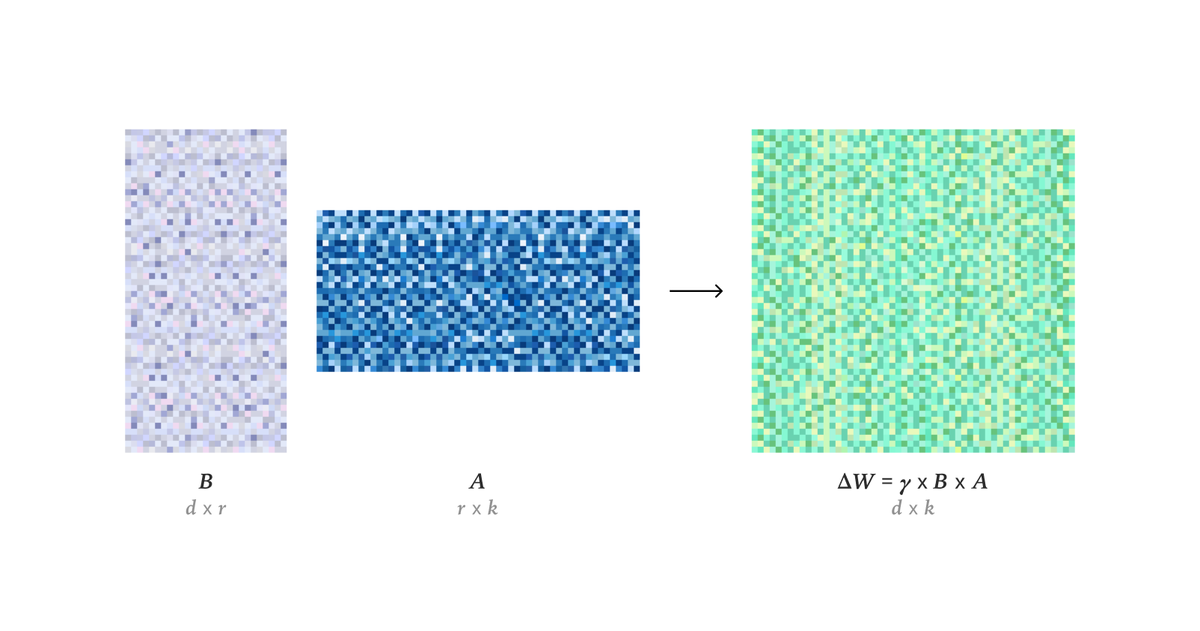
Arcee AI found that standard continued training outperformed QLoRA in one experiment using financial filings. The original QLoRA method saves memory by leaving a compressed base model unchanged while training smaller added components, as its paper explains.
Arcee trained Mistral AI's Mistral-7B-Instruct-v0.2 for one pass over the dataset. Its reported perplexity scores were 2.7156 for standard training, 3.2977 for QLoRA and 3.9648 for the starting model. Perplexity measures prediction of test text, with lower values better. Both approaches improved that measure, while standard training improved it more. This supports a task-specific comparison, not the article's sweeping claim that QLoRA cannot incorporate new knowledge.
- pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…