Which Prompts Make The Difference Data Prioritization For Efficient Human Llm Evaluation 2023 10 22
- Source
- cohere.com
- Author
- Cohere
- Date
Context
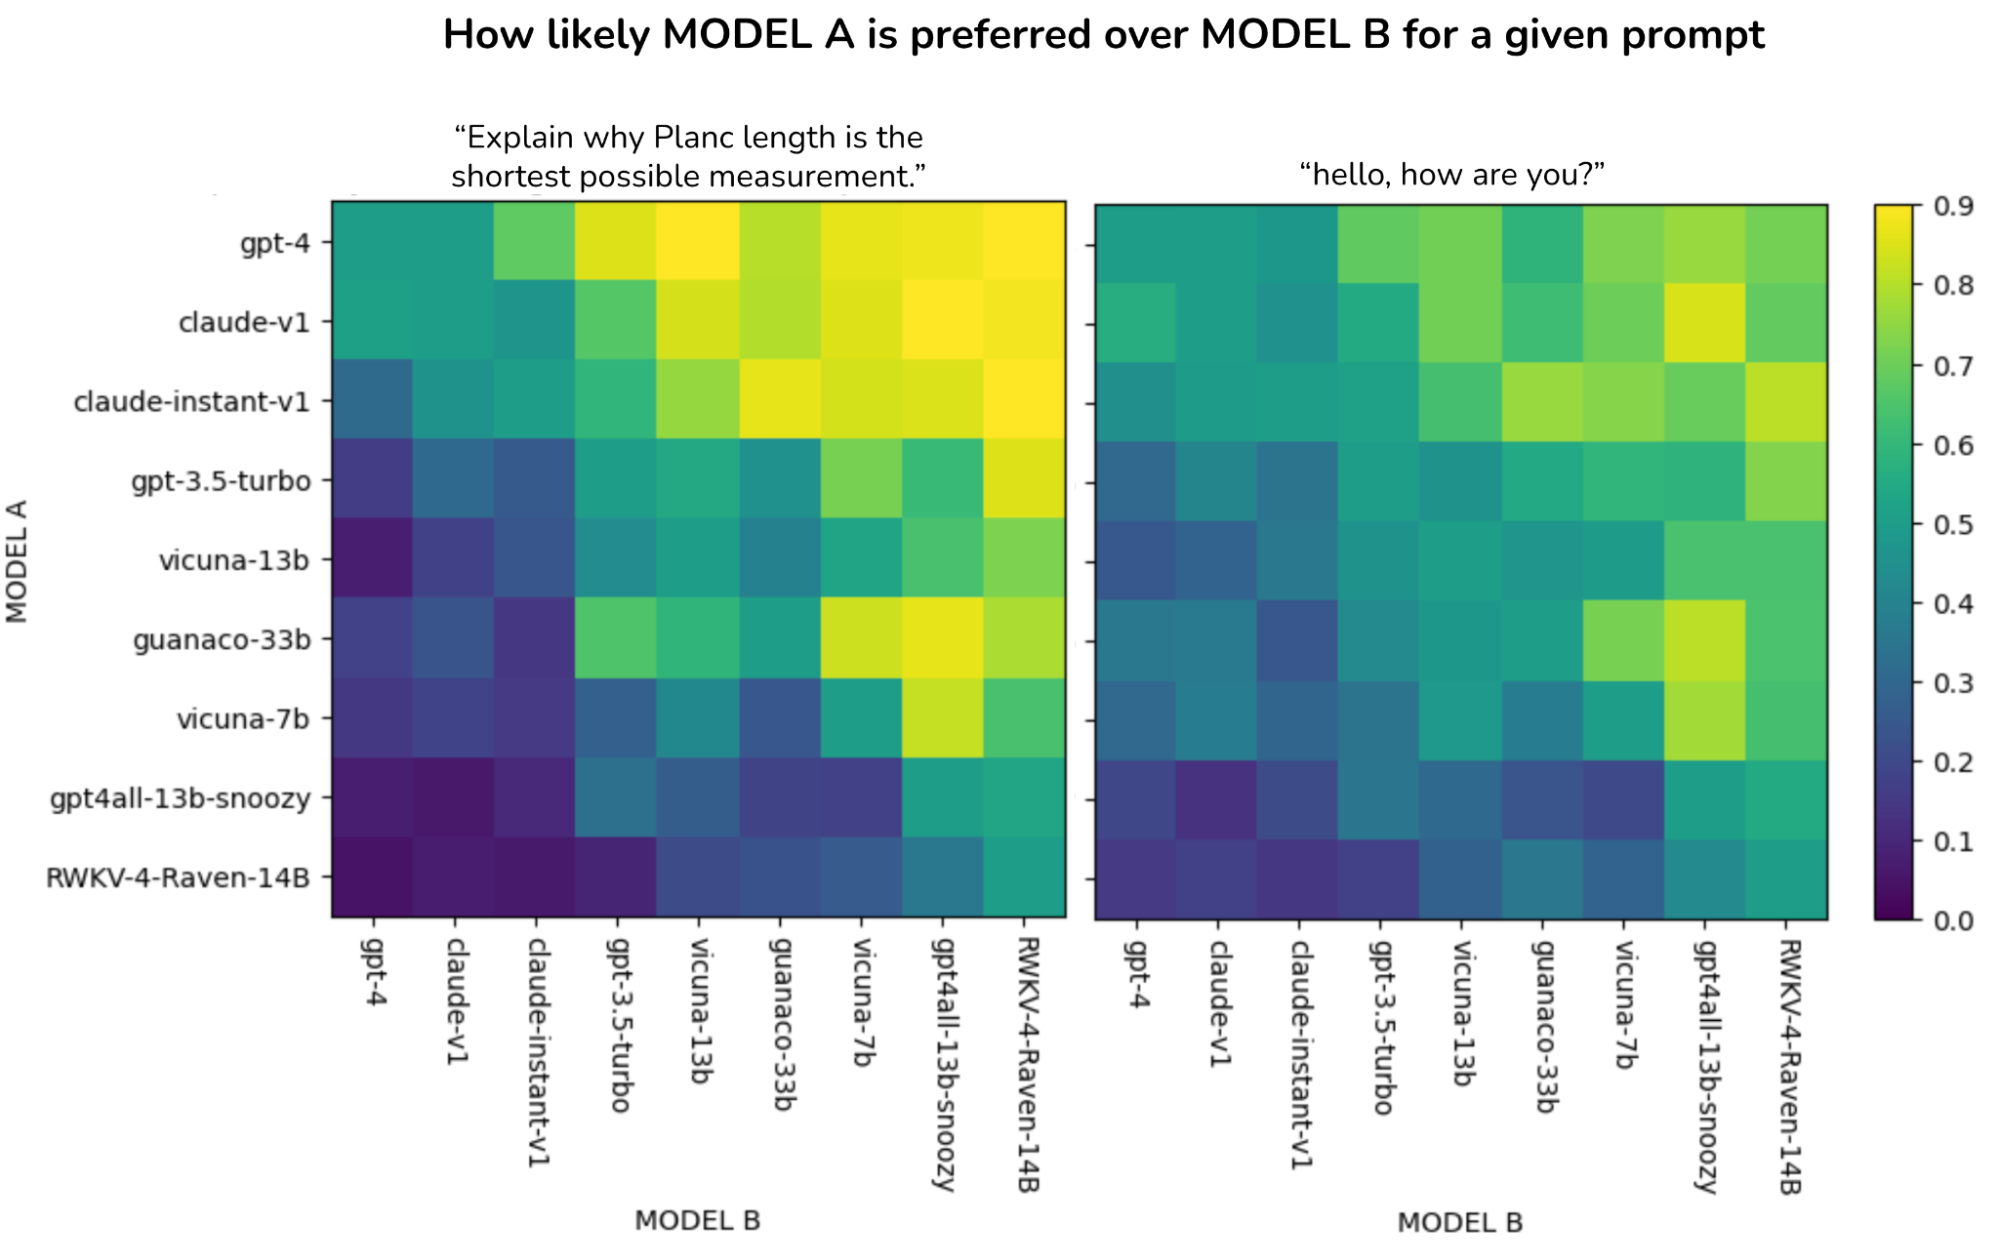
Cohere researchers investigated whether people comparing two language models could save effort by reviewing first the prompts where the models are most likely to give different answers. Their paper ranks prompts by how far the two models' probability distributions diverge (using KL divergence or cross-entropy), then sends the most divergent prompts to human reviewers first.
The abstract's headline result is that focusing on the top 20% of ranked prompts reduced indecisive tie outcomes by up to 54% compared with a random sample. The full paper shows the effect varied by model pair: about 54.6% for Flan-T5 xxl versus xl using KL divergence, about 22% for Dolly-v2 12b versus 7b, and little or none for a comparison across model families. It is a reduction in ties, not a demonstrated 54% cut in total cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
 postCohere releases open-weights translation model North Small Translate
- postIntroducing the next evolution in LLM text generation: the first fully-fledged…
- postHow is AI really affecting your job? @Cohere_Labs released the Agentic Task…
 articleThe Data Provenance Initiative A Large Scale Audit Of Dataset Licensing And Attribution In Ai 2023 10 25
Checking sign-in…
Loading comments…