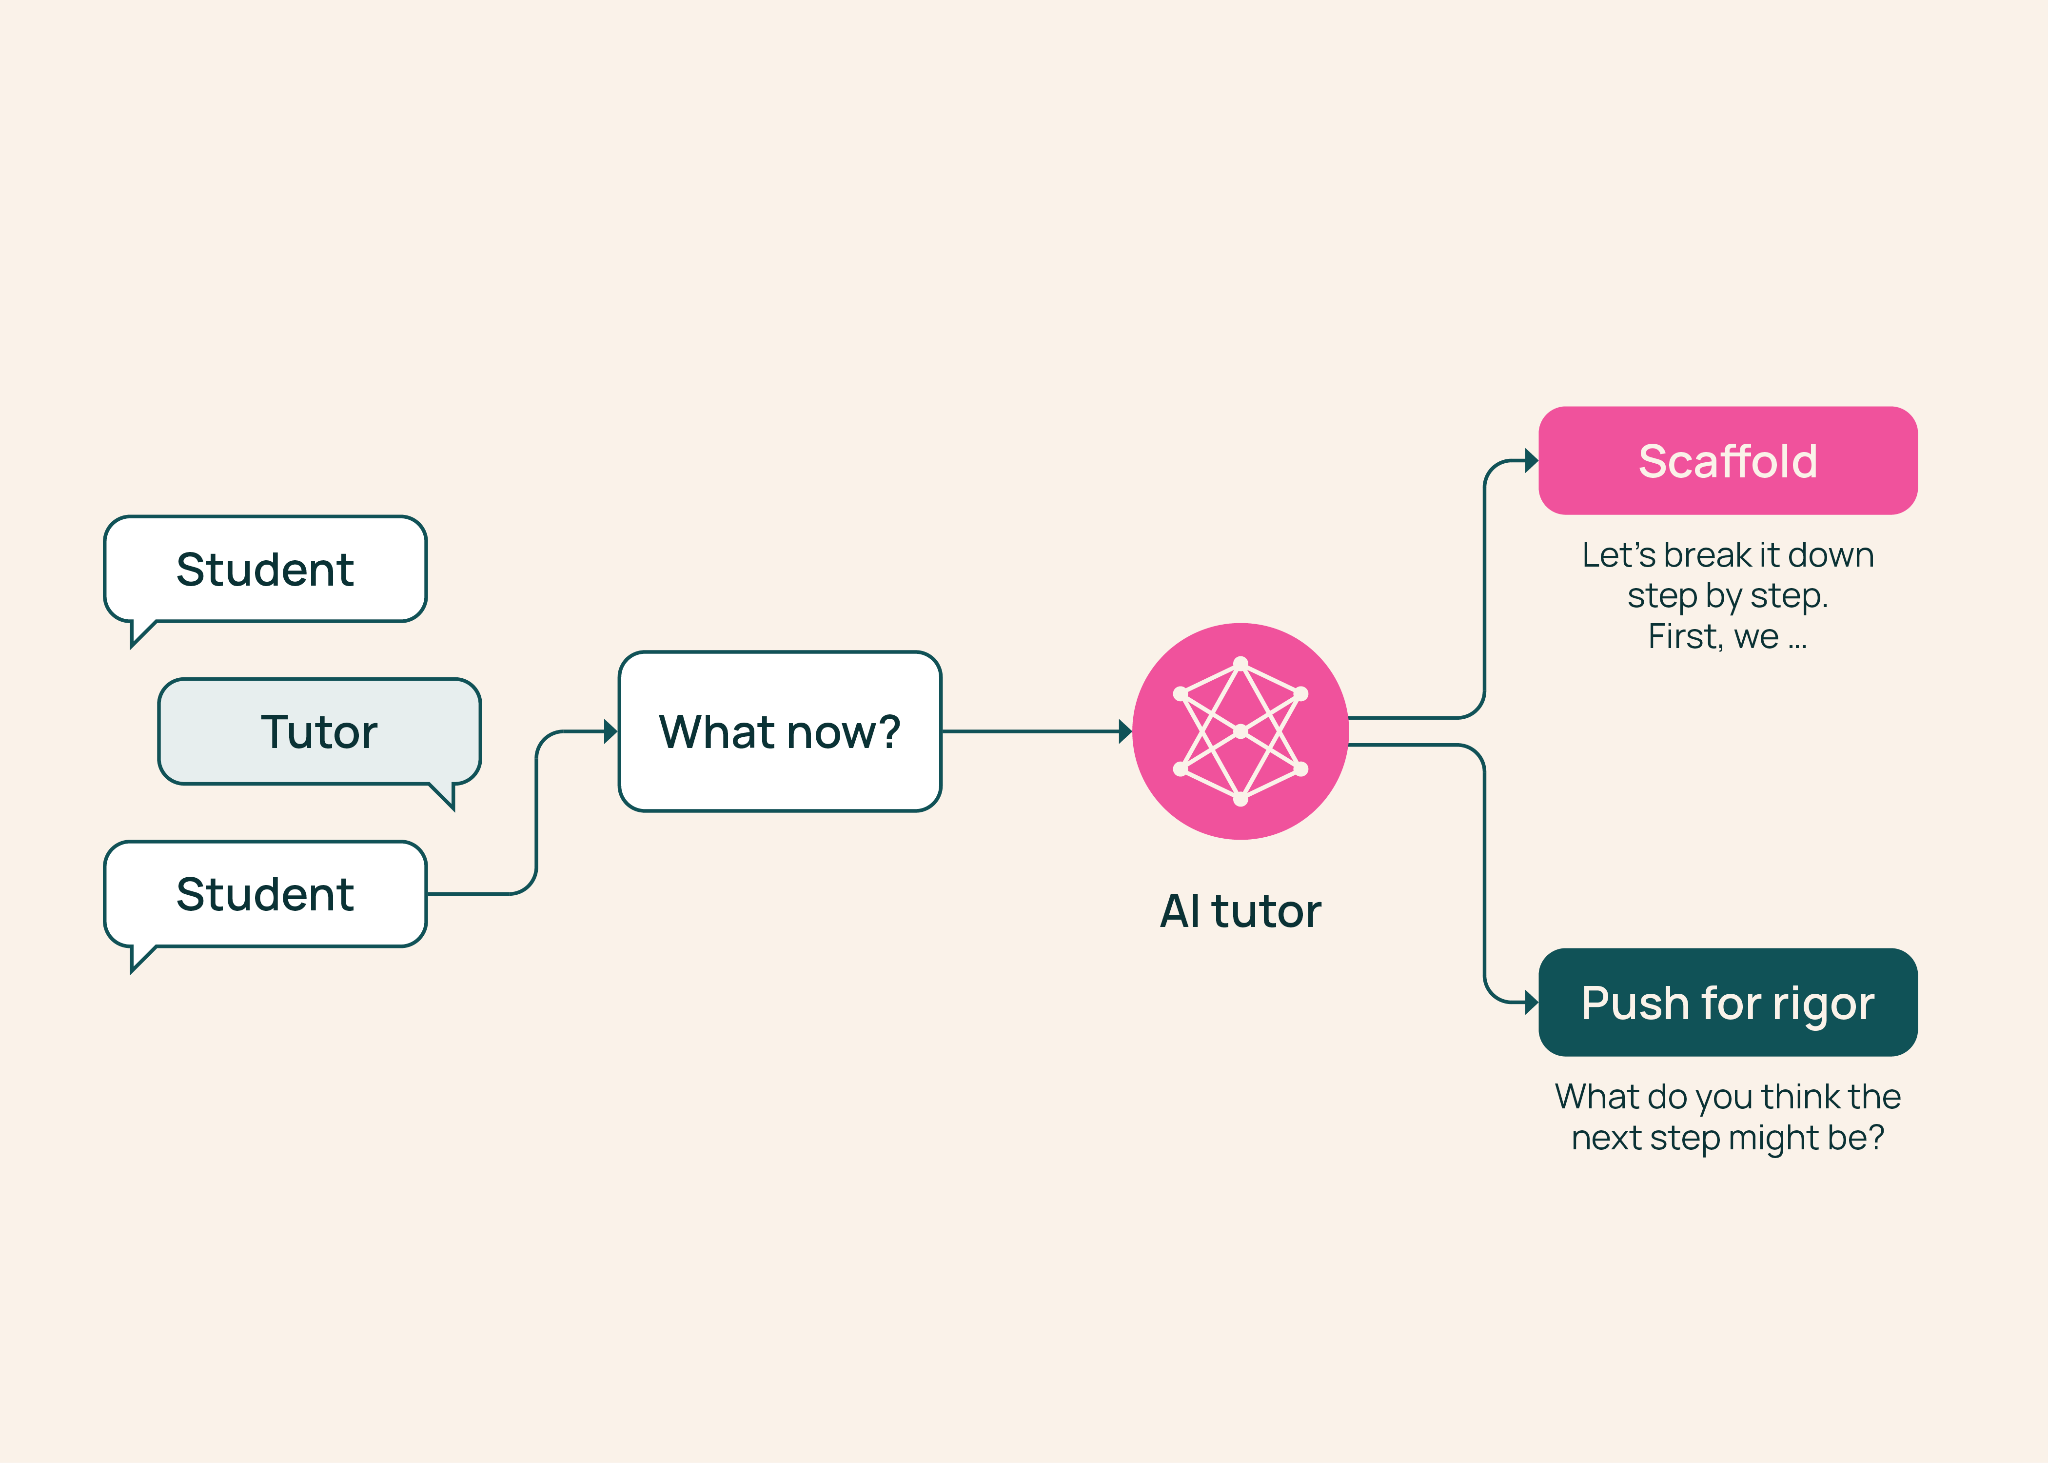
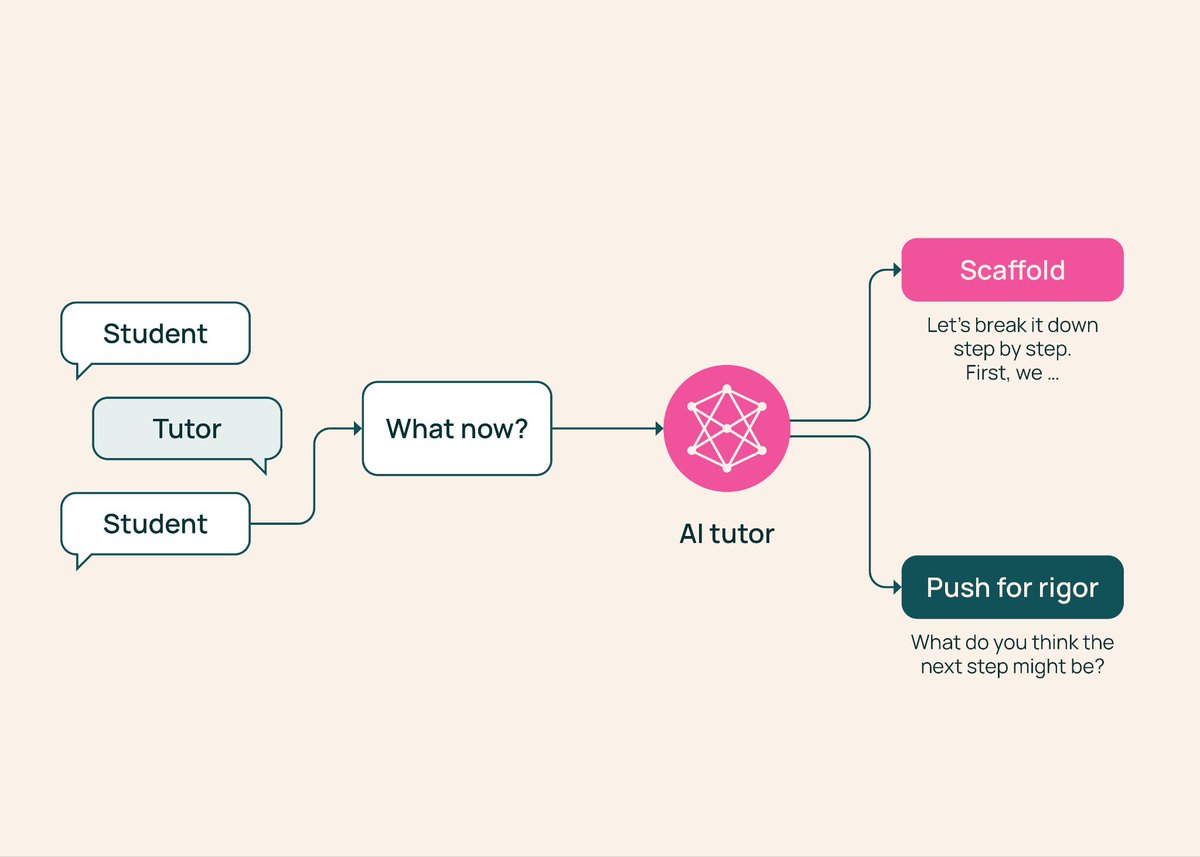
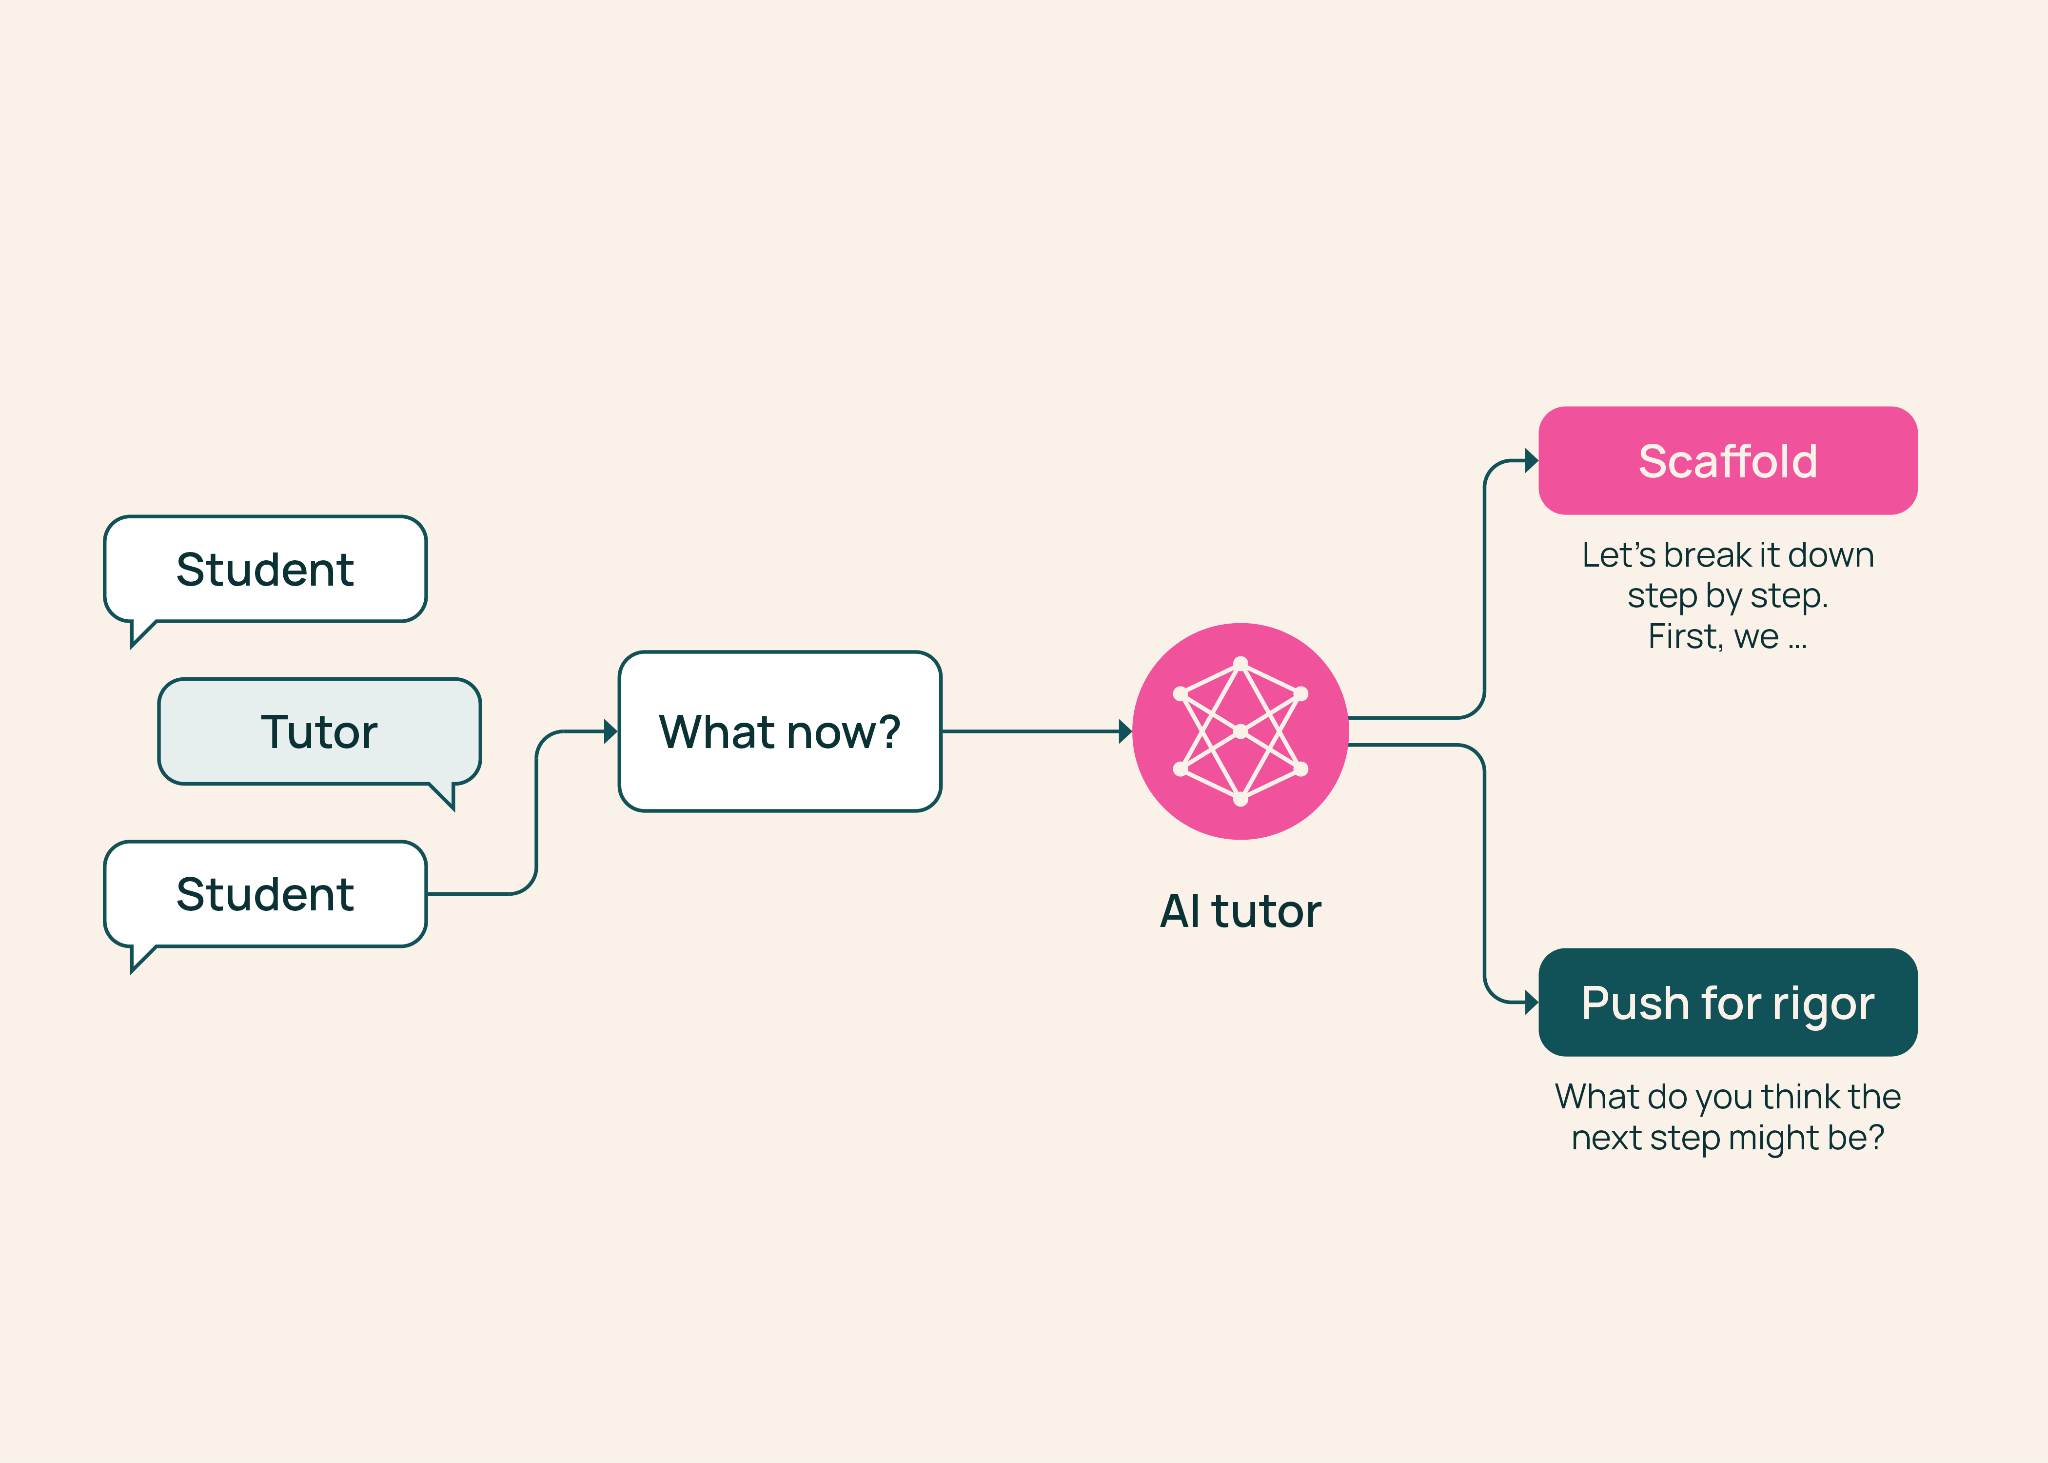
We tested frontier models including Astra & Opus 5.5 on TutorMoments, our eval for whether LLMs help students solve problems themselves or do too much for them.
In general, models scored better with detailed prompts than when told only to “tutor well.”
https://t.co/eA3uQpem6p
Ai2's evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → shows frontier models behave better as tutors with detailed instructions than with a generic 'tutor well' prompt. If you build educational agents, specify pedagogy explicitly and evaluate against helping versus doing the work.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.