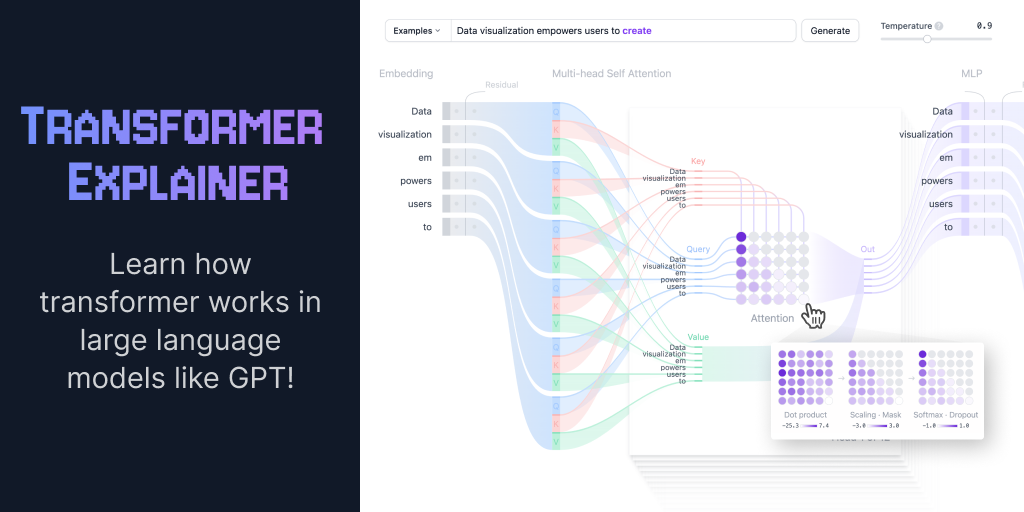
transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
Why it matters
A closed-form recipe lets teams write facts directly into a transformerThe neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.Full definition →'s MLP layers without any training run, offering a training-free way to update a model's knowledge.