A local alternative to Jev – 94% on Banking77
- Source
- gist.github.com
- Author
- nico
- Date
Context
A small local classifier can sort banking questions without generating an answer. This published script first converts each question into a numerical representation using an unchanged text encoder, then trains logistic regression to select among 77 support categories. Its author reports 94.25% accuracy on 3,080 test questions using the larger encoder.
The headline size and training time cover only part of the system. The classifier and scaler occupy about 642 KB, but that configuration also needs an approximately 1.2 GB encoder. Likewise, the reported three seconds measure classifier training, excluding text encoding. The result supports a compact trained decision layer for a fixed classification task; it does not measure a general conversational assistant.
- A Show HN author reports 94.25% accuracy on all 3,080 Banking77 test examples using frozen bge-large-en-v1.5 plus a trained logistic-regression classifier, close to the 94.86% cited for the state-of-the-art IntenDD.
- Only the classifier is trained: it and its scaler total 642 KB and train in about 3 seconds on a CPU. With the much smaller all-MiniLM-L6-v2 encoder (about 91 MB), accuracy is still 93.28%, per the author.
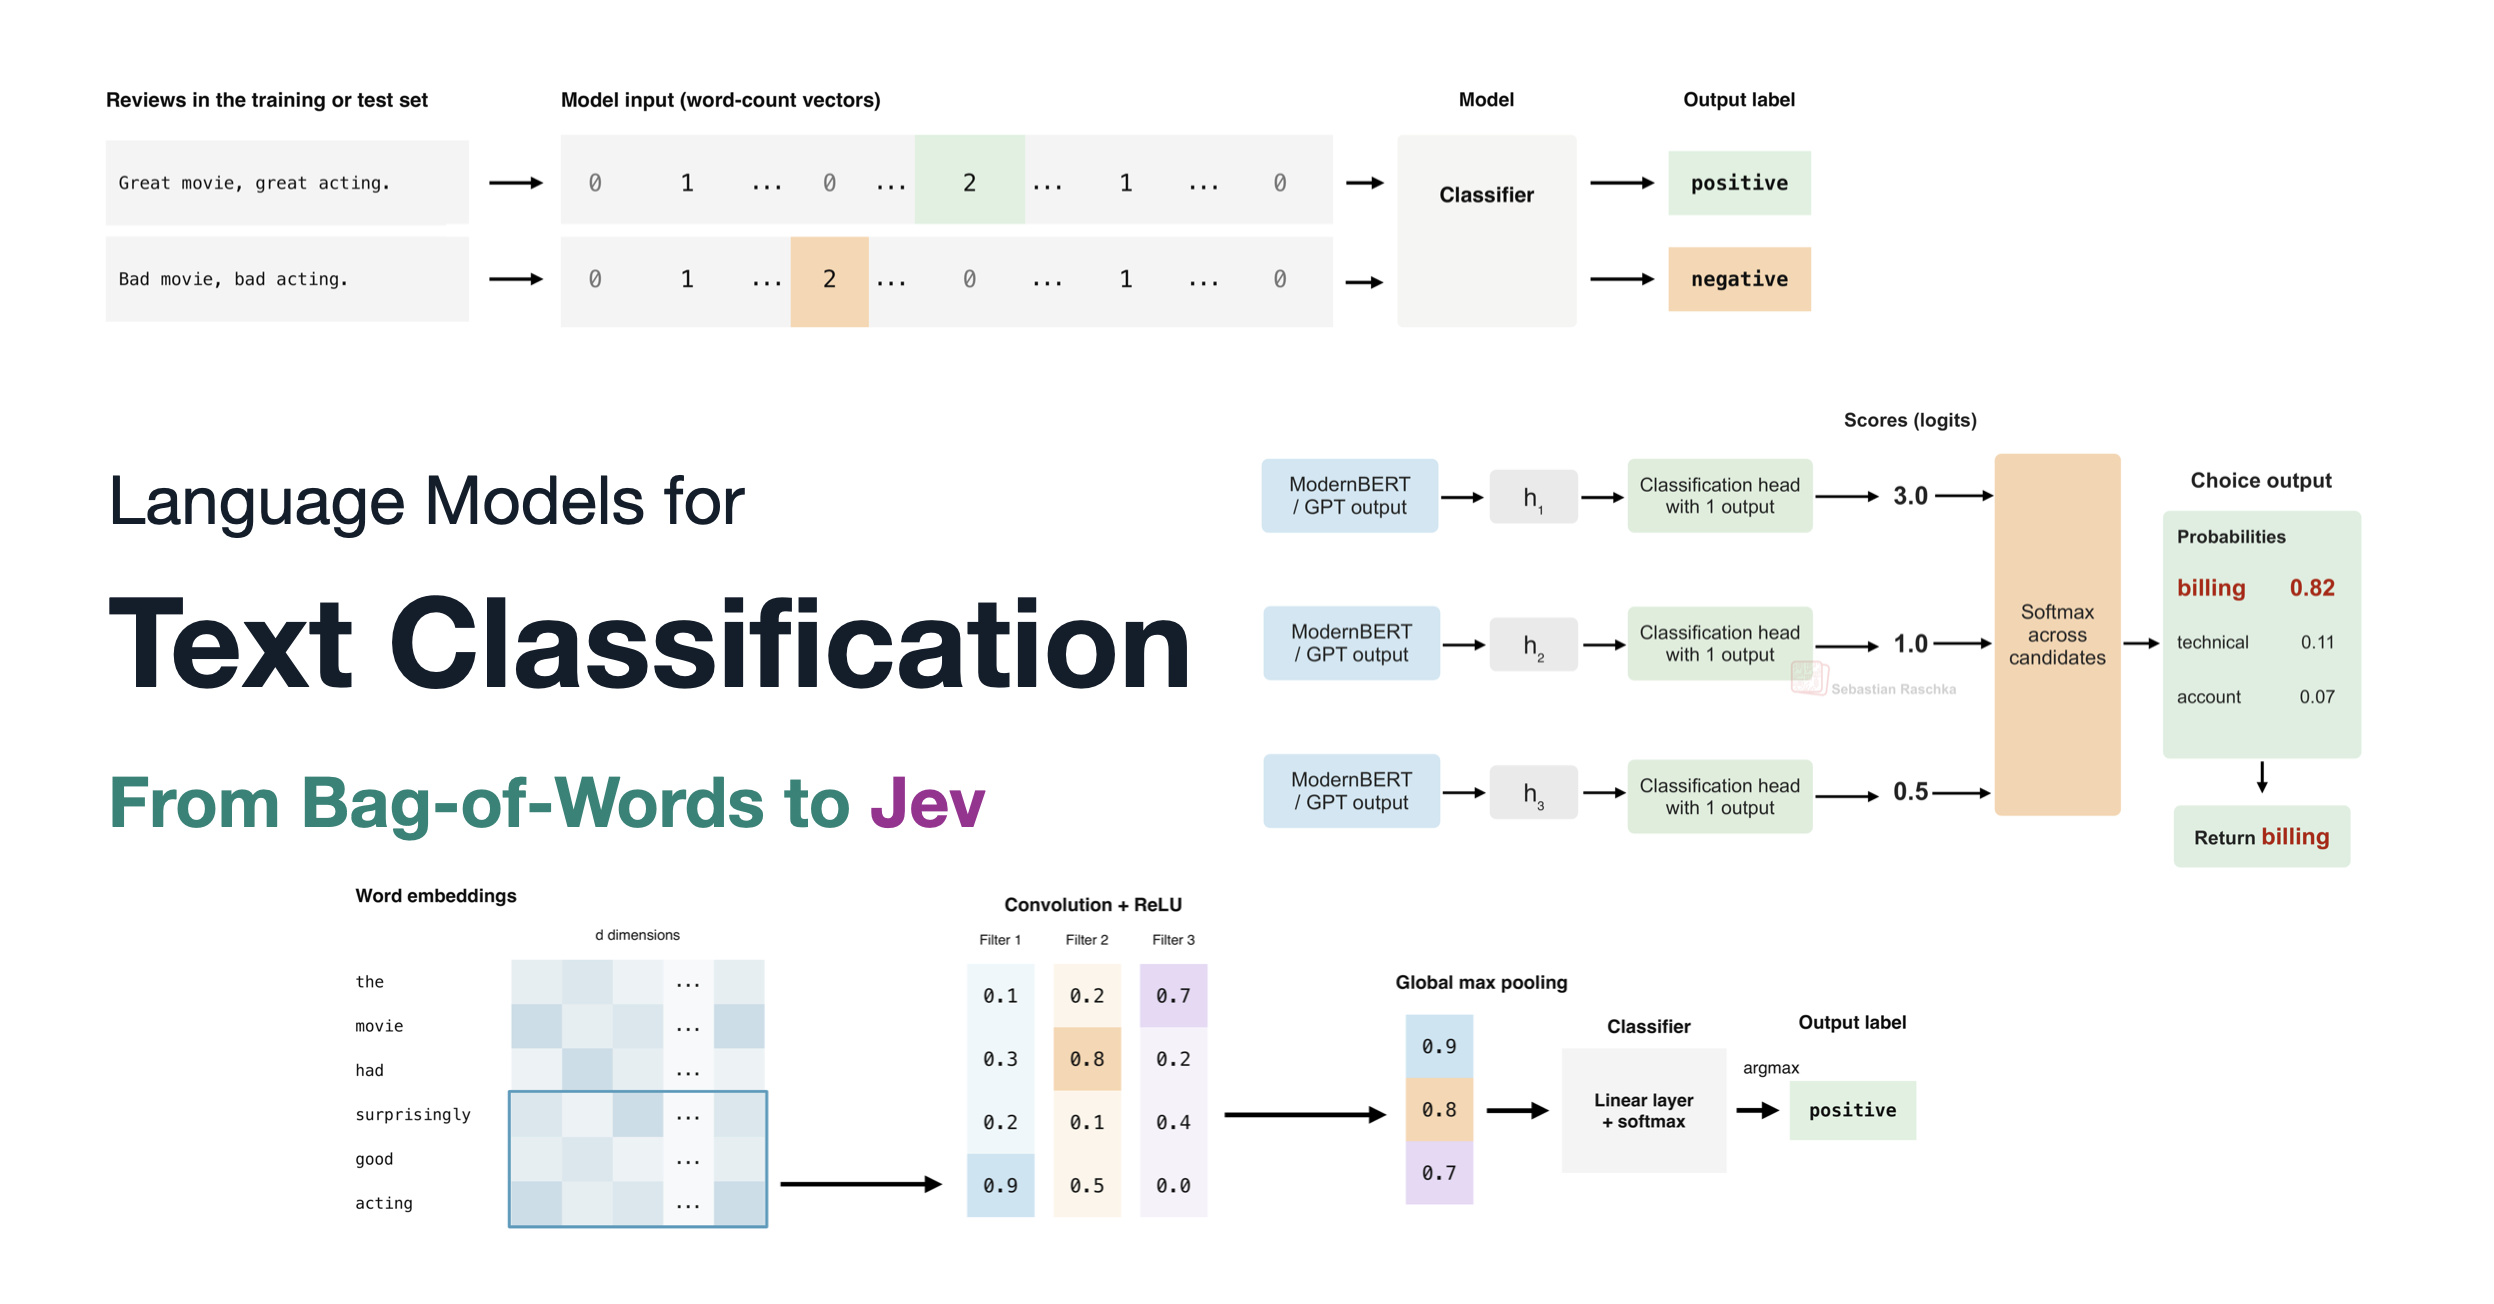
- In the author's comparison, the approach edges out fine-tuned ModernBERT (93.99%) and BERT (92.76%), which need GPU , and Jev's zero-shot 87.0% through a closed API.
- The author calls it a proof of concept and is now exploring a hybrid: local classifiers handle familiar decisions, an is consulted when needed, and its answers are used to improve the classifiers automatically.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
Checking sign-in…
Loading comments…