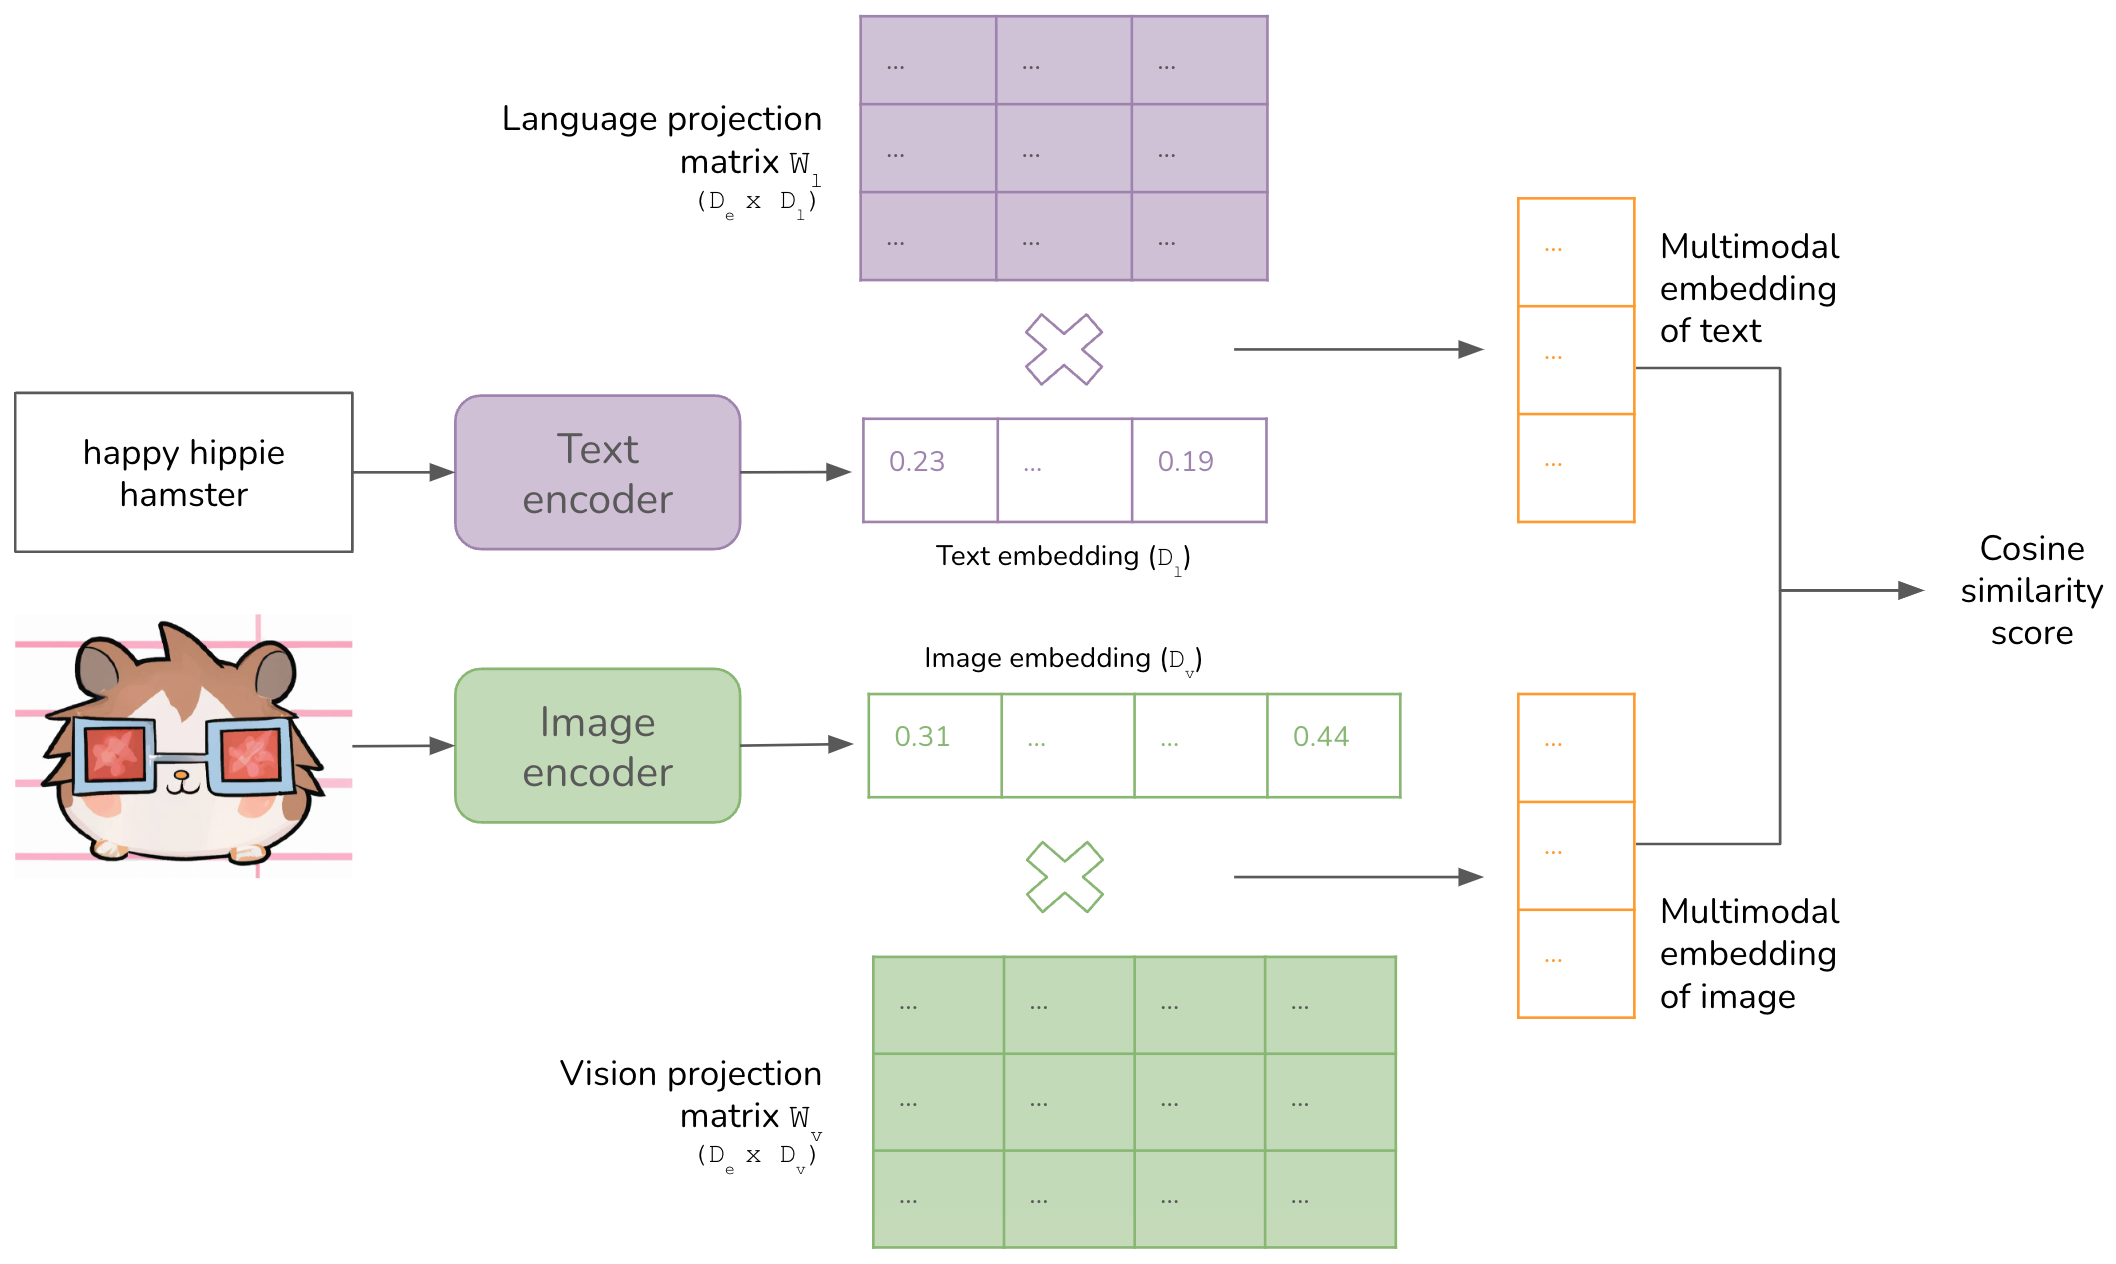
Modern multimodal models aren't a single decode loop anymore; they're composite. M* is one runtime that serves them all, and it matches or beats every specialized system: up to 2.7× on omni TTS, 12.5× on world-model rollouts. Learn more here: https://t.co/uWGIcXiB3X
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
Why it matters
A single runtime that handles composite multimodalA model that works with more than text — reading images, audio, or video, and sometimes generating them too.Full definition → pipelines efficiently could simplify serving infrastructure for teams building multimodal agents.