No coding agent exceeds 50% across investigation, test writing and refactoring, and success on one try is two to three times likelier than success on three. Expect to verify agent output and plan for inconsistency.
Key takeaways · AI-distilled
Scale's completed SWE Atlas spans 284 tasks across Codebase QnA, Test Writing and Refactoring. Top systems cluster in the 40s with none above 50%, while the same models score in the high 50s on SWE-benchThe standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.Full definition → Pro issue resolution.
Scale reports that models are two to three times more likely to solve a task on one of three attempts than on all three, so headline pass rates overstate how consistently a coding AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → finishes the work.
In Test Writing the main failure was weak assertions that pass equally on broken code. Higher test counts correlated with higher mutation failure rates, and the leading model under a common scaffold wrote the fewest tests on average.
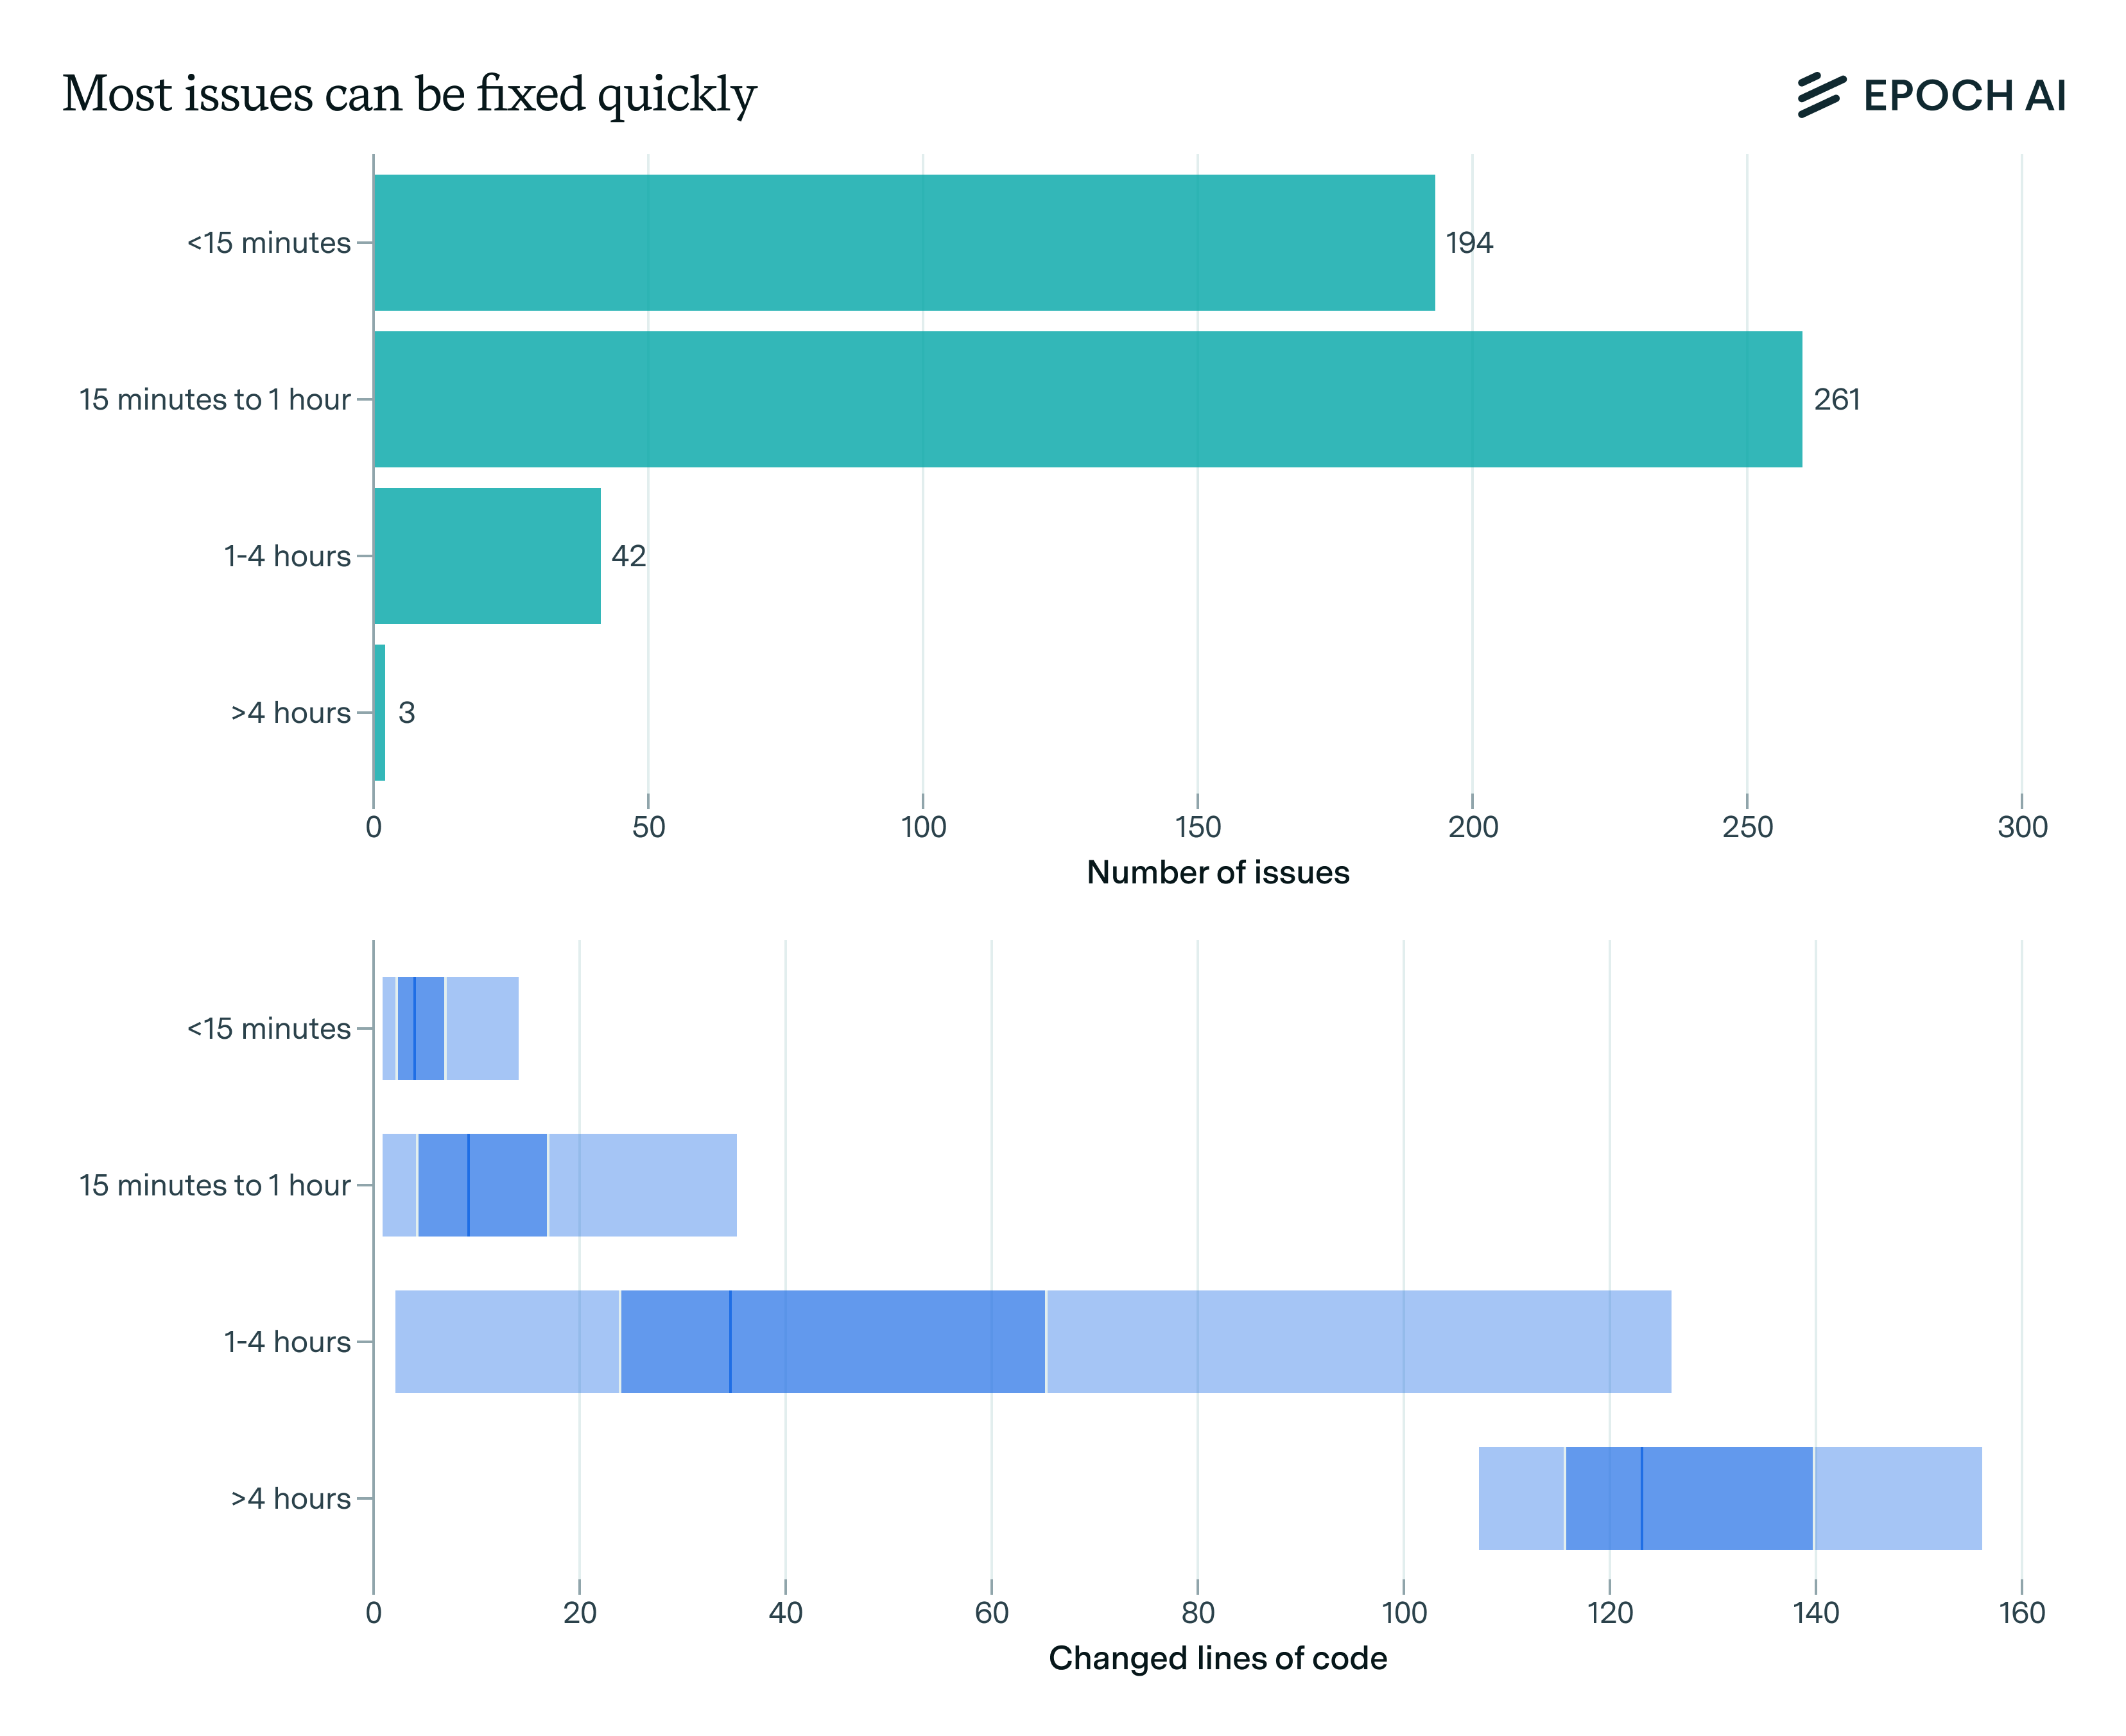
Refactoring failures were mostly incomplete changes: missed call sites, leftover dead code and broken edge cases, even when existing tests passed. Reference solutions change about twice the lines of a SWE-Bench Pro task.
Per Scale, models in their native scaffolds (Claude Code, Codex CLI) explored, searched and executed 1.5x to 2x more than on a generic agent harnessThe scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.Full definition → and scored noticeably higher, so the harness is part of measured capability.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.