Claude Opus 5 Debugging Benchmark: Does More Reasoning Actually Fix More Bugs?
Source
AlphaSignalAI
Author
AlphaSignalAI
Date
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Why it matters
If you're tuning reasoning-effort settings for coding agents, this benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → shows Medium effort captures nearly all the resolve-rate gains at a fraction of the cost of XHigh, and that Opus 5 at max effort is beaten on every metric by Grok 4.5, GPT-5.6 Sol, and Fable 5.
Key quotes
“A 260-attempt benchmark of Claude Opus 5 across four effort levels found that moving from Low (93.8% resolve rate) to XHigh (98.5%) improved reliability by only 4.7 percentage points while increasing cost per successful fix by 477% and token usage by 635%.”
AlphaSignalAI
“Medium effort emerged as the practical sweet spot, matching High's 63/65 resolve rate at 57% fewer tokens, 38% lower latency, and less than half the cost per fix.”
AlphaSignalAI
“Higher effort levels also changed patch behavior, with XHigh producing an average of 21.9 changed lines versus 11.3 at Low, and generating more over-edit attempts that exceeded expected edit scope.”
AlphaSignalAI
“In cross-model comparison, Opus 5 at XHigh (64/65) was outperformed on reliability, cost, and latency simultaneously by Grok 4.5, GPT-5.6 Sol, and Fable 5, all of which achieved 65/65.”
AlphaSignalAI
“Opus 5 at XHigh produced a more precise set of actionable comments than its production baseline, but caught fewer known issues and generated roughly four times as many nitpicks.”
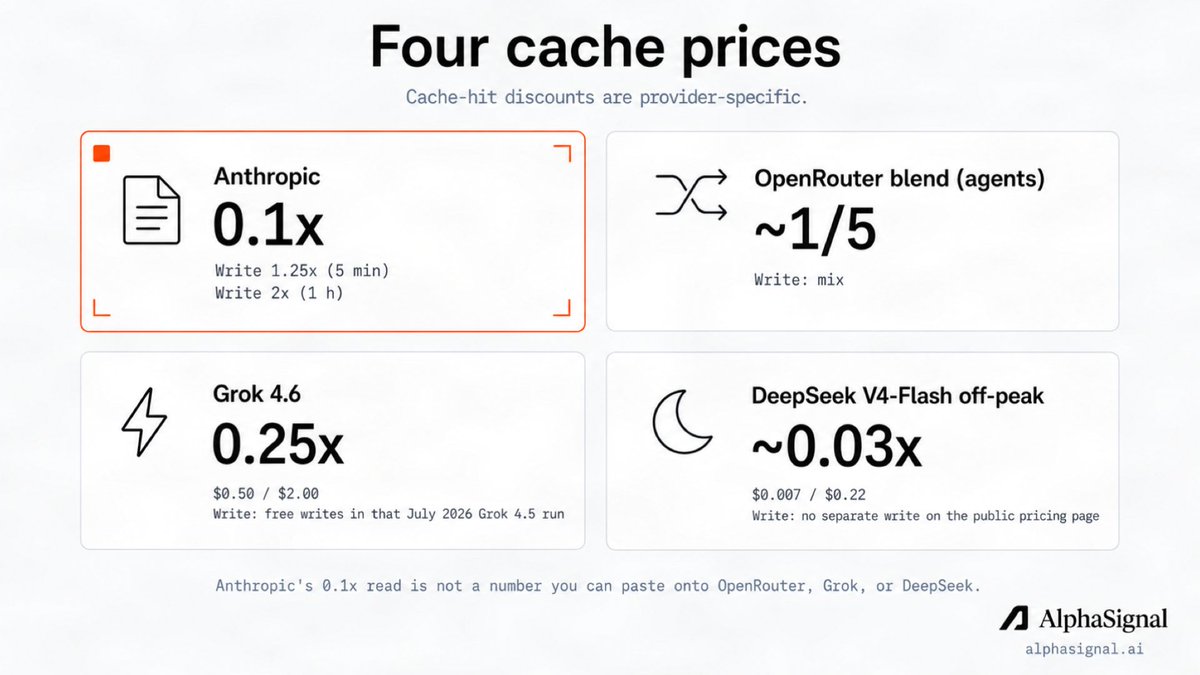 postPrompt cache TTL is the hidden line item in long coding-agent sessions
 articleFull breakdown: Claude-only apps often wait until the host speaks the new revisi
 articleDo not ask whether the agent follows the rule. Ask what stops it when it does no
 articleFull Breakdown: When can a change ship unread? When something cheap and hard to