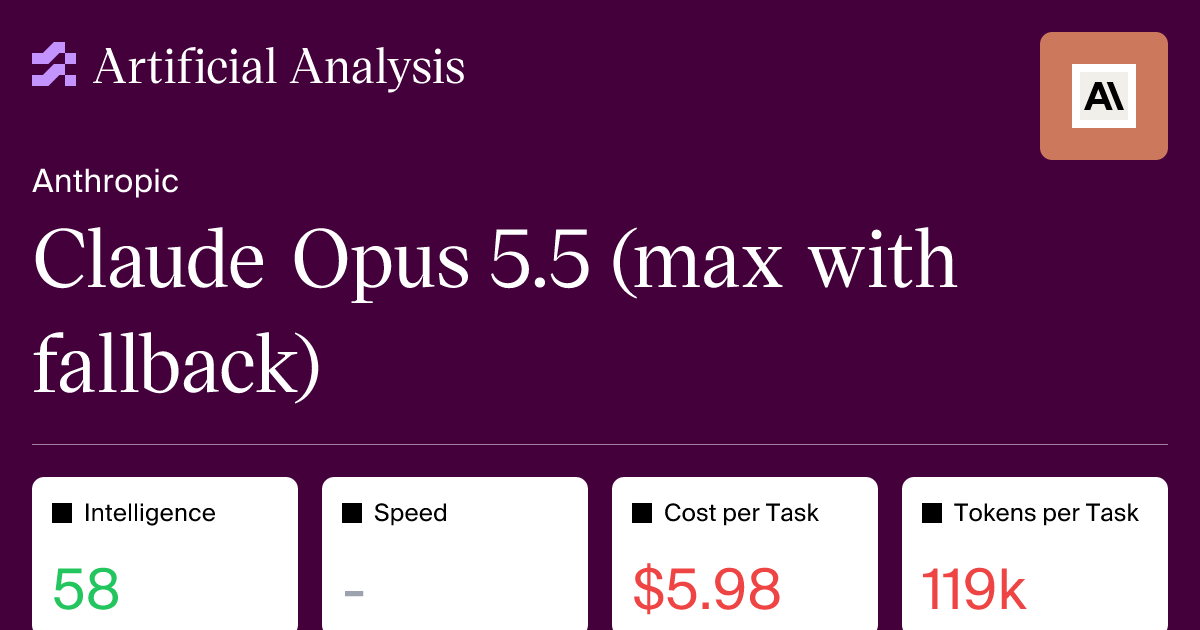
Claude Opus 5.5 Intelligence, Performance and Price Analysis (Max)
Source
theanonymousone
Author
theanonymousone
Date
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
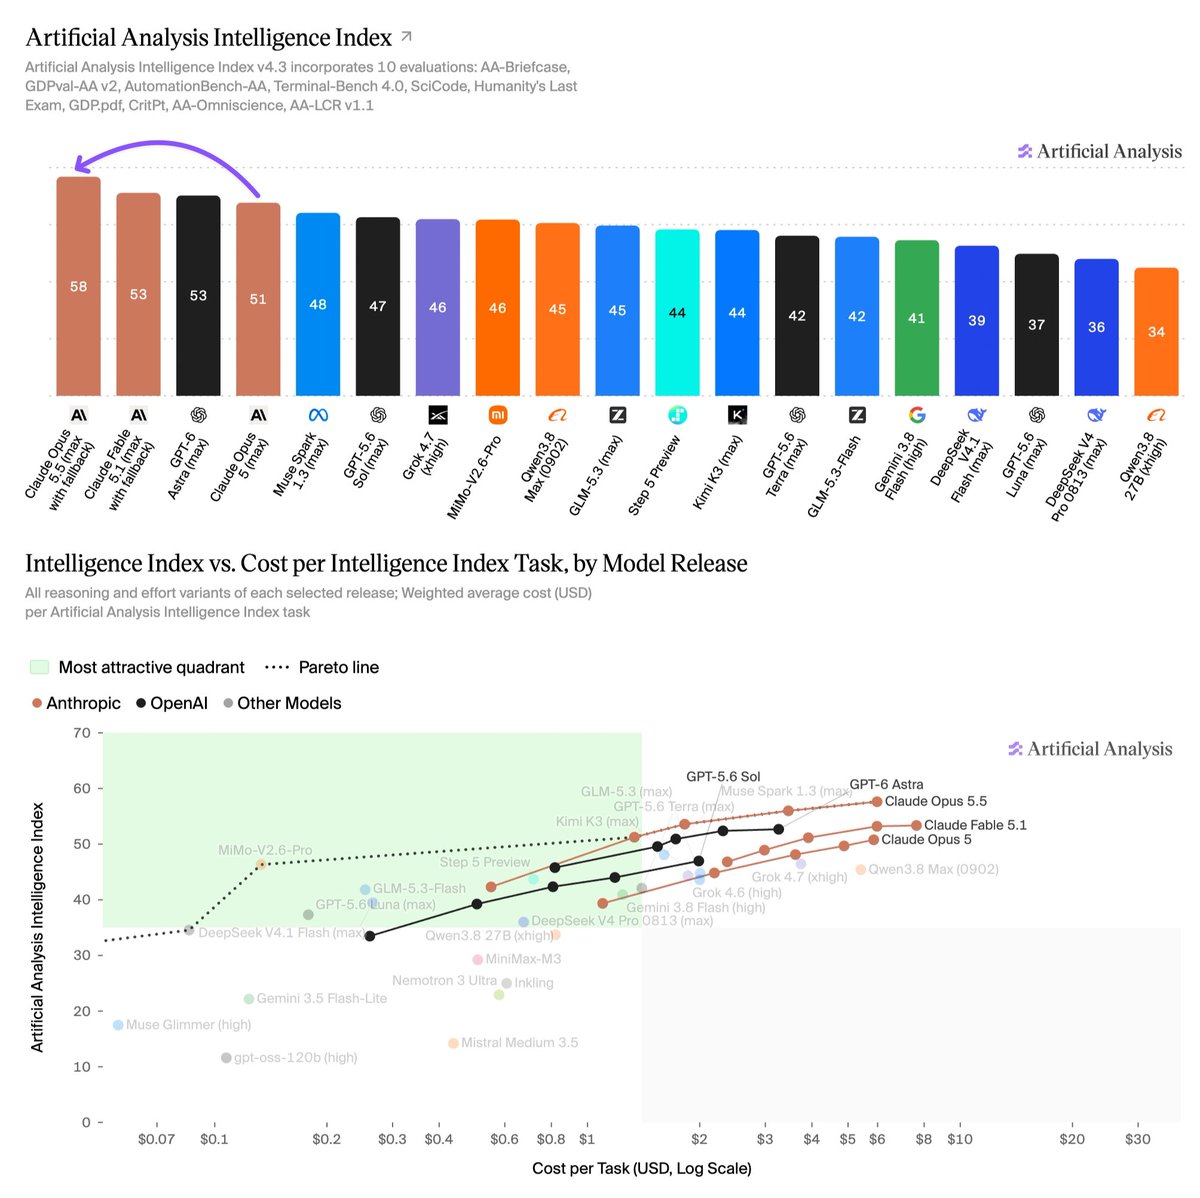
Why it matters
Gives hard numbers on Claude Opus 5.5's benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → score (58, near top of 212 models), cost per task ($5.98), and verbosity, helping engineers weigh its capability against its price for agentic workloads.