NVIDIA DGX Spark 64GB Gives Developers More Ways to Build and Scale Local AI
Source
blogs.nvidia.com
Author
Allen Bourgoyne
Date
Why it matters
A cheaper 64GB DGX Spark SKU widens access to running capable agents and open models locally, and two units cluster without extra setup when workloads outgrow one.
Key takeaways · AI-distilled
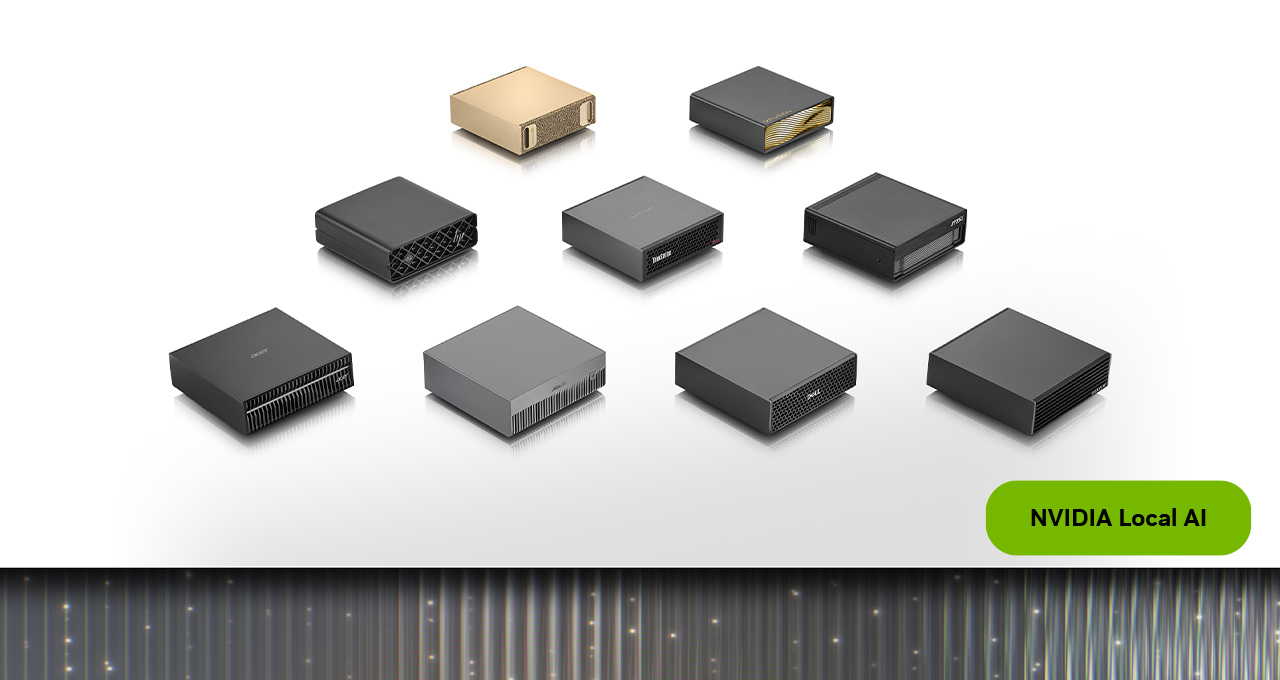
The DGX Spark 64GB keeps the GB10 Grace Blackwell Superchip, DGX OS and software stack of the 128GB model, and NVIDIA says it runs models up to 100 billion parameters on device. Partner units go on sale Oct. 23 starting at $4,999.
Two units link directly through their ConnectX-7 ports with a QSFP cable, pooling memory to 128GB for models up to 200 billion parameters. In NVIDIA's Qwen 3.8 27B test the pair delivered up to 1.7x the performance of one system.
NVIDIA Sync Cluster Assistant detects connected units, validates their configuration and sets up the ConnectX-7 network. A Sync Model Launcher due at month end will deploy Qwen3.8 27B on one unit or a cluster and configure OpenCode to use it.
NVIDIA says Ollama, vLLM, PyTorch with CUDA, its AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → Toolkit and Nemotron models work out of the box, and pitches the box for always-on coding or research agents and for serving model inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → to everyday laptops.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.