NVIDIA DGX Spark Developer Kit Turns a Desk Into a Supercomputing Lab
Source
blogs.nvidia.com
Author
Allen Bourgoyne
Date
Why it matters
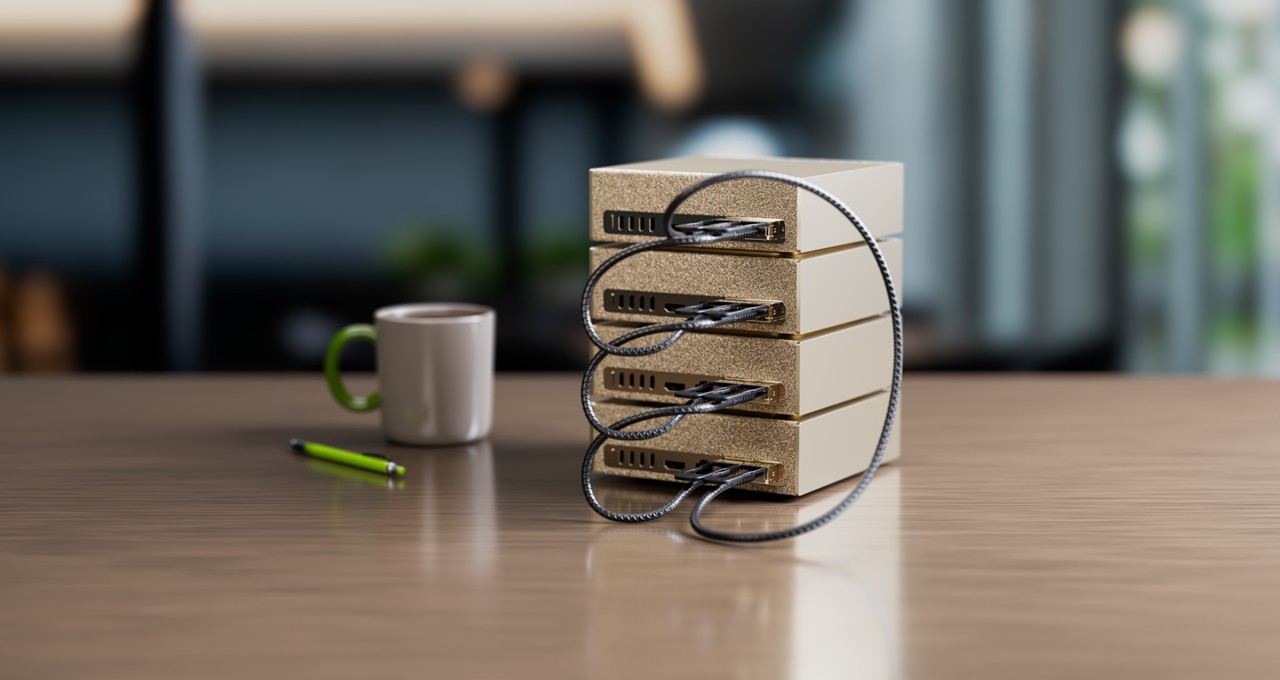
A four-node DGX Spark ring gives 512GB of memory without a switch, enough to run models up to about 700B parameters locally in NVFP4. Teams can develop and keep proprietary data on-premises instead of queueing for shared GPUs.
Key takeaways · AI-distilled
The DGX Spark HPC Developer Kit links four GB10 systems in a ring over ConnectX-7, each wired directly to its two neighbors, so the four-node cluster needs no network switch.
NVIDIA says four nodes provide 512GB of combined memory and 20TB of NVMe storage, and with NVFP4 can deploy models of up to 700B parameters locally, naming DeepSeek V4.1 as an example.
UC Berkeley's Hartwig Group reports LoRAA cheap way to fine-tune a model by training a small add-on layer instead of changing all of the model's weights.Full definition →fine-tuningTaking a trained model and training it a bit more on your own examples so it gets better at one specific job.Full definition → Nemotron 3 Super 120B-A12B on a single DGX Spark with NVFP4, running 8 to 24 hour training fits back to back instead of waiting through multi-day cluster queues.
NVIDIA cites Berkeley's Rubin Lab getting genome-trait results 15x sooner by avoiding 11-hour cluster queues, and Kvantify reporting tensor-network simulations of circuits with up to 70 qubits and 975 gates on one DGX Spark.
The HPC SDK installation playbook, which brings GPU-accelerated C, C++ and Fortran compilers and MPI tools to the cluster, was not yet available at announcement; NVIDIA says it is coming soon.
Terms in this piece · Glossary
LoRA — A cheap way to fine-tune a model by training a small add-on layer instead of changing all of the model's weights.
fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.