Dual-Flow Transformers: Decoupling the Primary Prefill Path from Additional Decode Computation
- Source
- arxiv.org
- Author
- Liming Liu, Mingze Wang, Tuo Zhao
- Date
Context
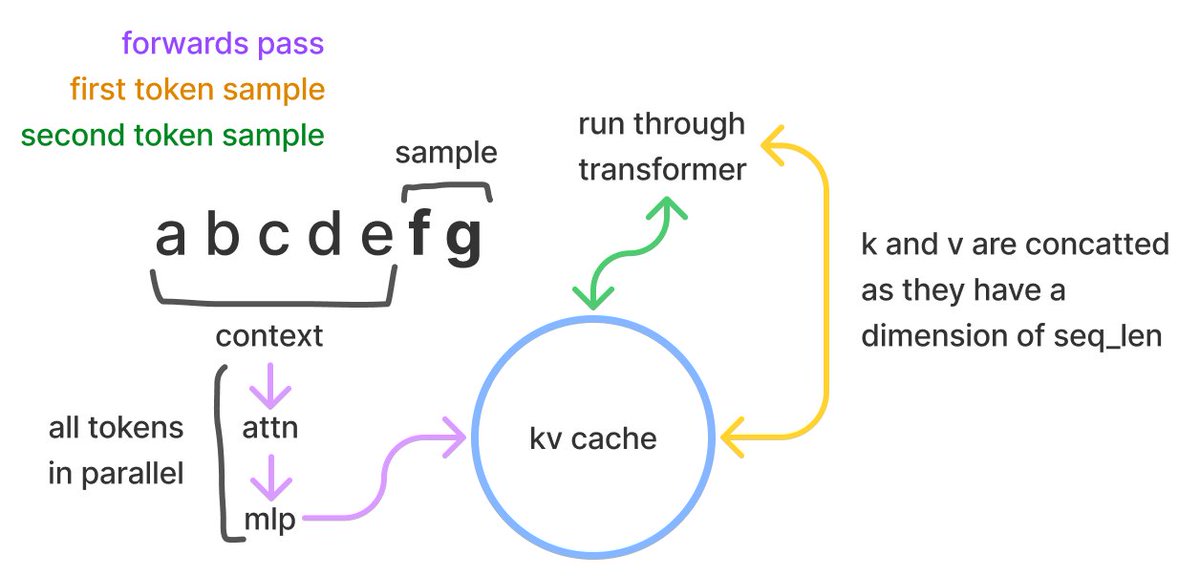
Dual-Flow Transformers investigate whether a can spend extra computation generating an answer without adding that work across the entire prompt. The main processing path reads the prompt and stores information for subsequent generation. A second path joins at the final prompt position, sharing major model weights and using the main path's stored information without writing its own persistent state. Paper abstract
The authors report better prediction scores on held-out text when comparing models trained on matched amounts of text. This supports a way to adjust prompt-processing and answer-generation computation separately. Matching training text does not establish equal computation or faster execution, so the reported result should not be read as a measured serving-cost reduction.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
“As large language models serve more requests, cumulative inference cost is becoming increasingly important relative to one-time training cost.”
Liming Liu, Mingze Wang, Tuo Zhao
“The two inference phases stress hardware differently: prompt prefill is parallel and typically compute-bound, whereas autoregressive decode is sequential and often memory-bandwidth-bound.”
Liming Liu, Mingze Wang, Tuo Zhao
“Its primary flow is a complete causal language model that processes the prompt and writes the KV cache. The auxiliary flow is omitted during prompt processing and activated only from the final prompt position onward, adding continuation-prediction computation without writing persistent state or influencing the primary flow.”
Liming Liu, Mingze Wang, Tuo Zhao
“In MoE models, the separation makes primary and auxiliary expert fan-outs independent controls over prompt cost, continuation cost, and predictive quality.”
Liming Liu, Mingze Wang, Tuo Zhao
Checking sign-in…
Loading comments…