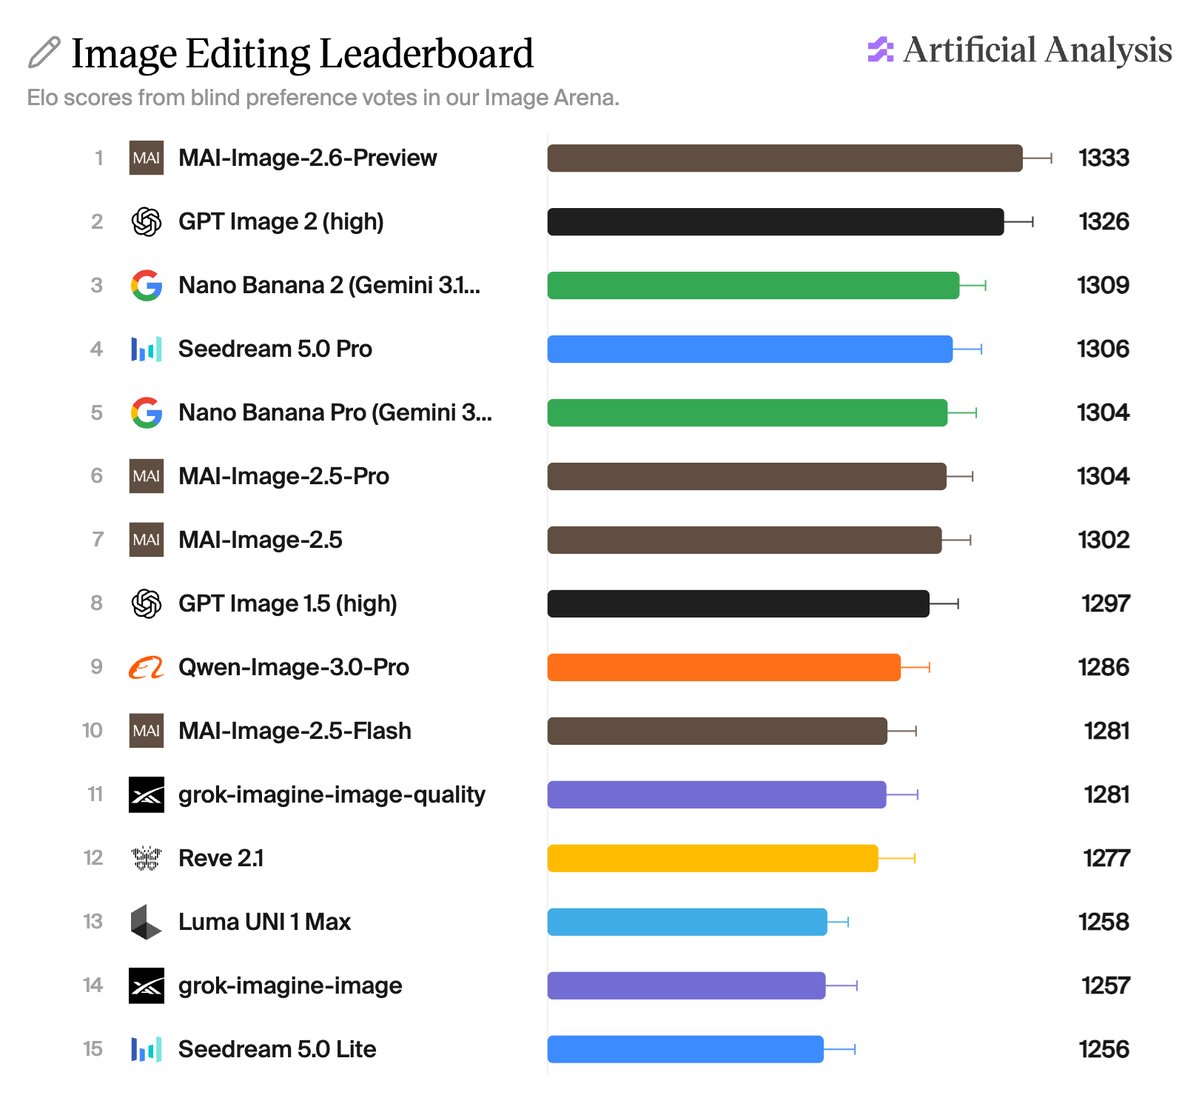
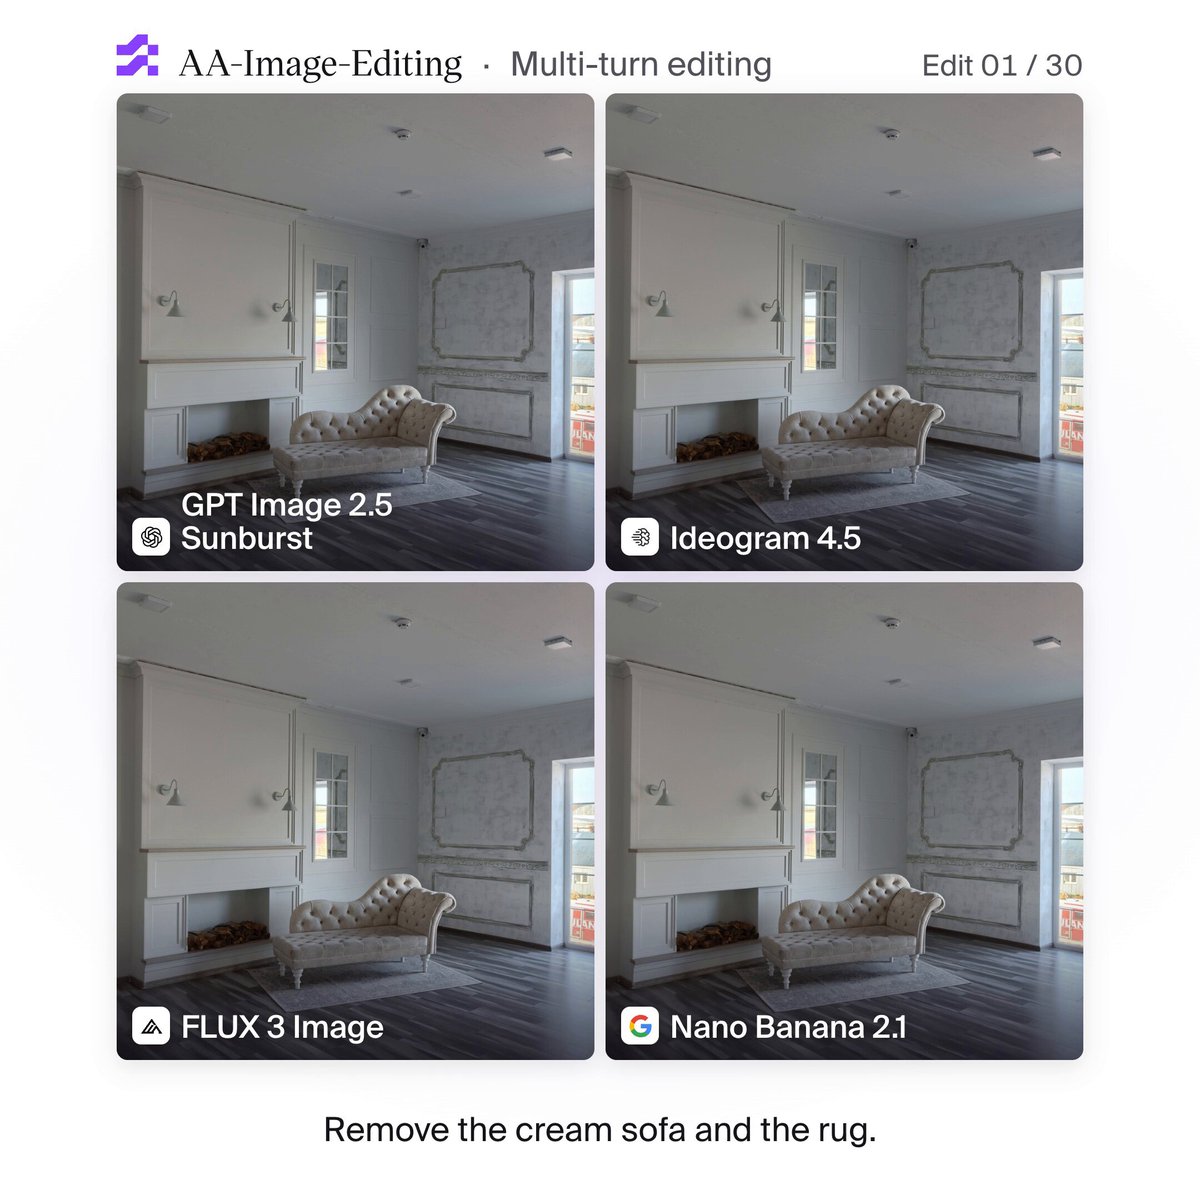
Sourceful's Hype-Edit-1 benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → asks whether an image editor can repeat a precise change while preserving everything else. Its evaluation description uses 100 tasks with ten generated attempts per task. Five human judges assess each attempt without seeing the model's identity, and a majority decides whether it passes. Comparing routine success with the chance of finding one successful result among repeated attempts helps expose the difference between a dependable tool and a model that occasionally produces an excellent edit. For production image work, that difference affects how much generation and inspection must happen before an acceptable result is found.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.