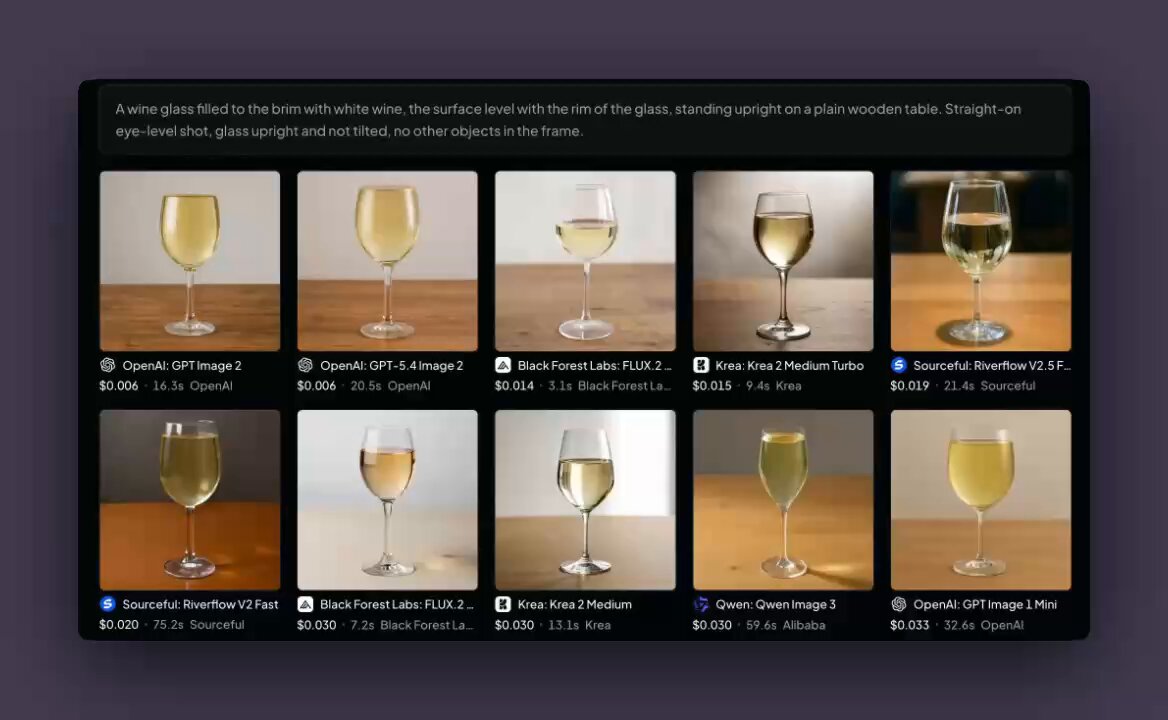
OpenRouter's visual image benchmarks let people compare whether models follow particular instructions. The announcement describes a grid of outputs generated from shared challenging prompts, sortable by price and generation time. Prompts probe concrete requirements such as object counts, exact written text, spatial relationships and preserving subjects during edits. A reader can inspect the outputs for the capability their own task needs, then weigh that result against cost and waiting time. The page supplies examples for human judgment, rather than a single score that settles which model is best for every image.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.