GPT-6.1 Terra costs $1/$5 per million tokens and scores 48 on the new Coding Agent Index v2.0. Its hallucinationWhen a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.Full definition → rate on AA-Omniscience fell from 88% to 38%, which changes cost-quality choices for agent workloads.
Key takeaways · AI-distilled
Artificial Analysis reports GPT-6.1 Terra costs $1/$5 per million input/output tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → versus $2/$12 for GPT-5.6 Terra, with cached input down from $0.20 to $0.05 and cache writes halved to $1.25.
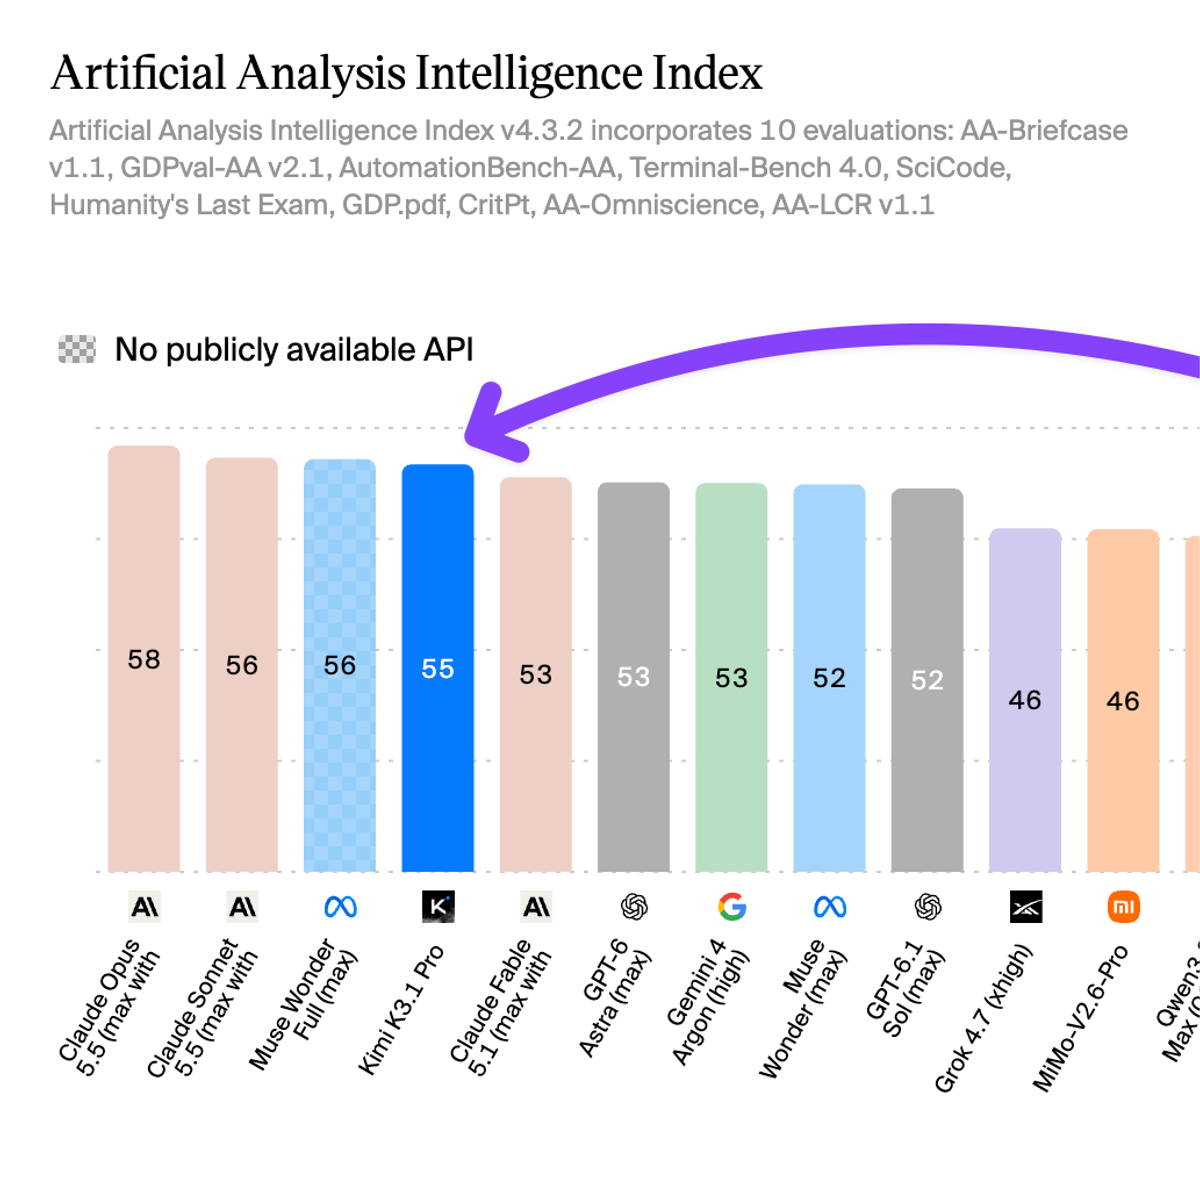
At max effort, GPT-6.1 Terra gained 6 Intelligence Index points over GPT-5.6 Terra at $0.40 per task versus $1.40. Lower effort settings gained 7 to 13 points, and only low and medium effort sit on the cost-efficiency frontier.
On AA-Omniscience, GPT-6.1 Terra guessed on 38% of questions it could not answer, down from 88% for GPT-5.6 Terra, while accuracy rose 2 points, meaning it also answered more questions correctly.
GPT-6.1 Terra scored 48 on the new Coding AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → Index v2.0, between GPT-6.1 Sol (54) and GPT-6 Luna (31), and gained about 20 points on Terminal-Bench 4.0, rivaling Sol at max effort. Most other evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → moved less, such as 5 points on GDP.pdf.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.