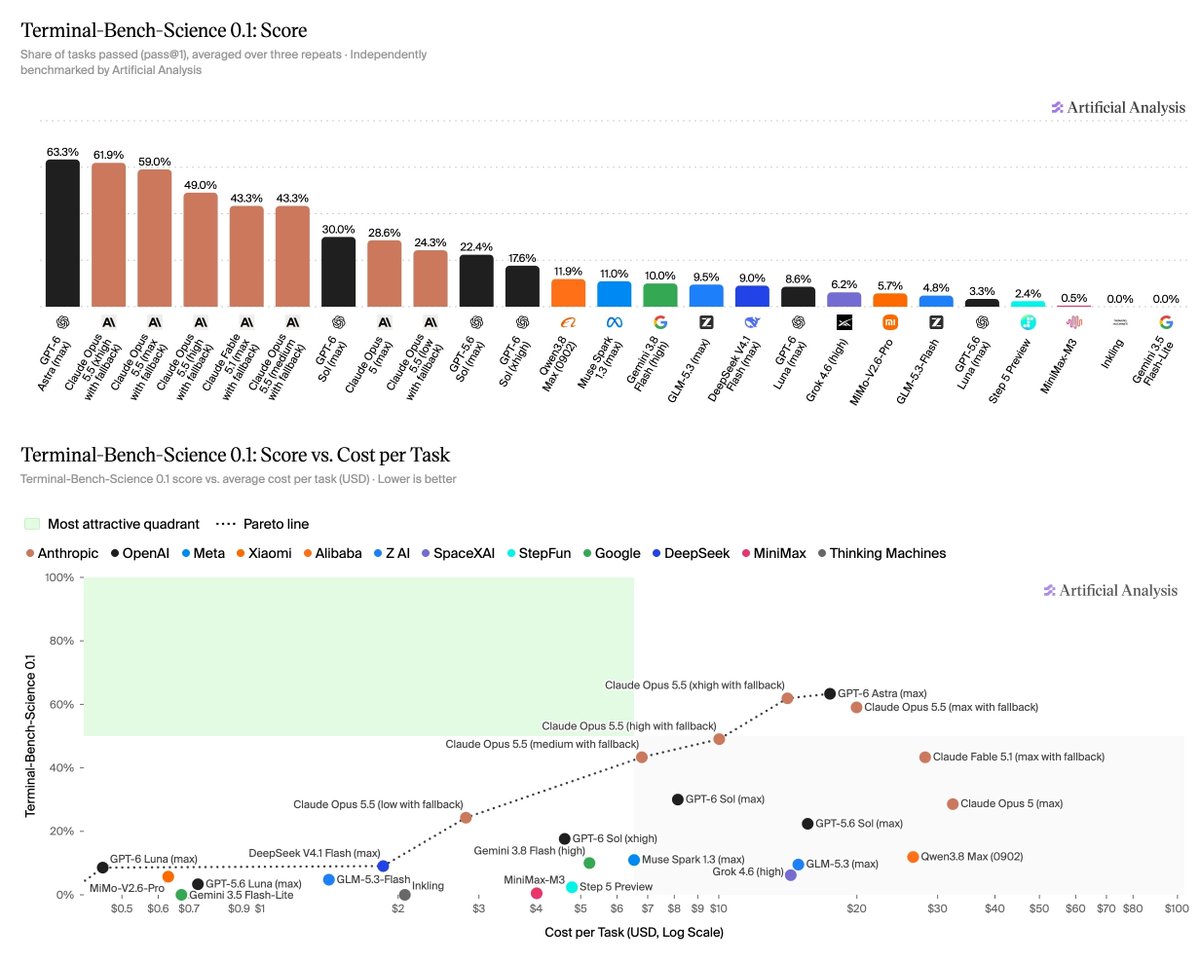
Gives scores and per-task cost for frontier models on physician-rubric health conversations. For example, the cheapest GPT-6 Luna scores 4 points below the top model at under 2% of the cost. Length adjustment reshuffles rankings.
Key takeaways · AI-distilled
On HealthBench Professional, Claude Opus 5.5 has the highest raw score (71.4%) but falls to sixth (59.9%) after length adjustment, because its answers average about 5,900 characters, nearly 3x the 2,000-character threshold, per Artificial Analysis.
The length adjustment OpenAI uses lowers scores for replies over 2,000 characters and raises shorter ones. GPT-6 Sol (max), averaging about 1,600 characters, is the only model whose HealthBench Professional score rises after adjustment.
Short answers trade completeness for clarity on HealthBench: GPT-6 Sol (max) writes about 1,000-character replies and has the top raw Communication Quality score (81%) but the lowest Completeness score (34%), while Claude Sonnet 5.5 leads Completeness at 63%.
HealthBench Professional is a 525-conversation set made entirely of clinician conversations, including adversarial ones, while HealthBench covers 5,000 conversations with everyday users and health workers; both grade replies against physician-written rubrics.
On standard HealthBench, DeepSeek V4.1 Flash (max) scores 60.9% at $0.005 per task, about one point behind leader Claude Sonnet 5.5 (62.1%), which costs roughly 16x more at $0.08 per task, according to Artificial Analysis.