Muse Spark Open inference benchmarks: ~150M tokens/s per MW on B300
- Source
- x.com
- Date

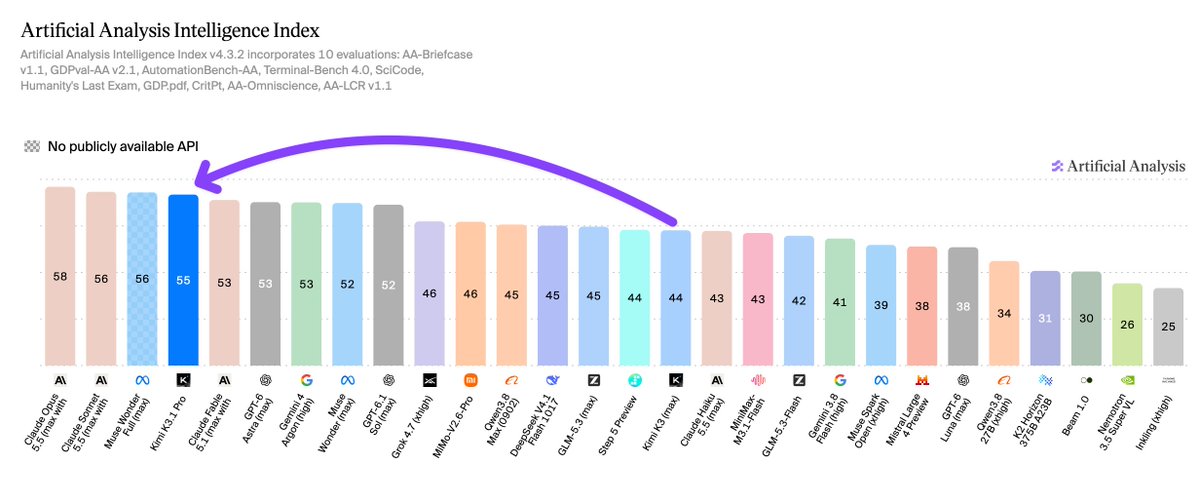
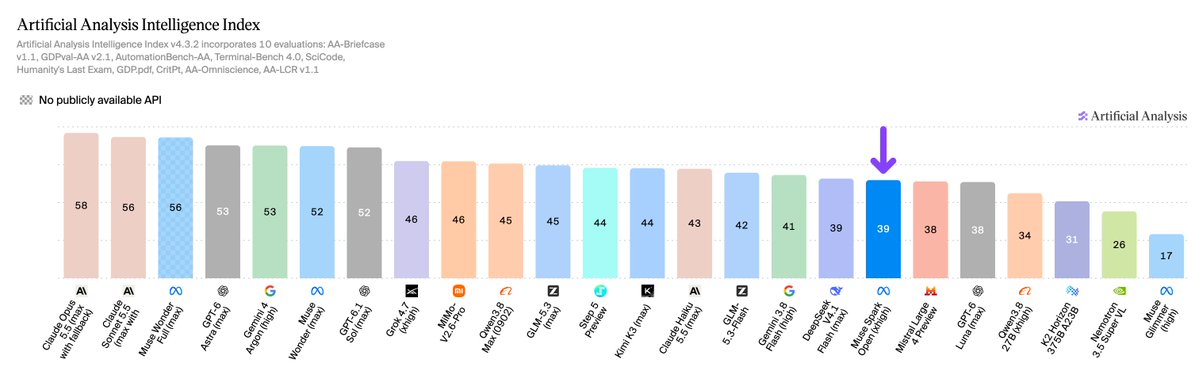
Results from Muse Spark Open, Meta’s newly released 816B (42B active) open-weights model, are now live on AA-AgentPerf. In our initial testing, the model reaches up to ~150M tokens/s throughput per MW of power used on 4x NVIDIA GB300 or B300 GPUs Muse Spark Open scores 39 on the Artificial Analysis Intelligence Index. It is an MoE with 62 layers, of which 46 use 2,048-token sliding-window attention, cutting the KV cache requirement at 1M context by ~75% vs. full attention. Meta published an NVFP4 checkpoint and AMD published an MXFP4 checkpoint, which we use for the NVIDIA and AMD hardware respectively Initial results: ➤ NVIDIA B300 and GB300 lead, each reaching ~150M tokens/s per MW in throughput-oriented (lower per-user speed) configs. GB300 pulls ahead at higher output speeds (~108M vs ~92M at 100 tok/s), but both have only been tested in aggregated serving configs so far, and we expect GB300's lead over B300 to grow with multi-node disaggregated configs ➤ Serving configs are improving quickly. On the same B300 node, NVIDIA's tuned SGLang configs deliver ~1.6-1.8x the throughput per MW of the launch-week cookbook configs at 50-100 tok/s. The gains come from TP4 deployments…

Throughput per megawatt for an 816B open MoE varies by hardware and serving recipe: tuned SGLang configs gave 1.6-1.8x over launch cookbook settings. That matters when you size self-hosted deployments.
- Per Artificial Analysis, Meta's Muse Spark Open is an 816B-parameter with 42B active. 46 of its 62 layers use 2,048-token sliding-window , which cuts needs at 1M by about 75% versus full attention.
- On AA-AgentPerf, B300 and GB300 each reach about 150M tokens/s per MW in throughput-oriented configs. GB300 leads at higher per-user speed (about 108M vs 92M at 100 tok/s), and AA expects that lead to grow with multi-node disaggregated serving.
- Tuning moved results fast: NVIDIA's SGLang configs gave 1.6-1.8x the per-MW throughput of launch-week cookbook configs on the same B300 node, at the cost of longer time to first token, and AMD's Oct 22 recipe lifted MI355X about 1.7x.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.

Checking sign-in…
Loading comments…