Cursor Adds Claude Opus 5.5, Tops Its Own Benchmark
- Source
- x.com
- Date

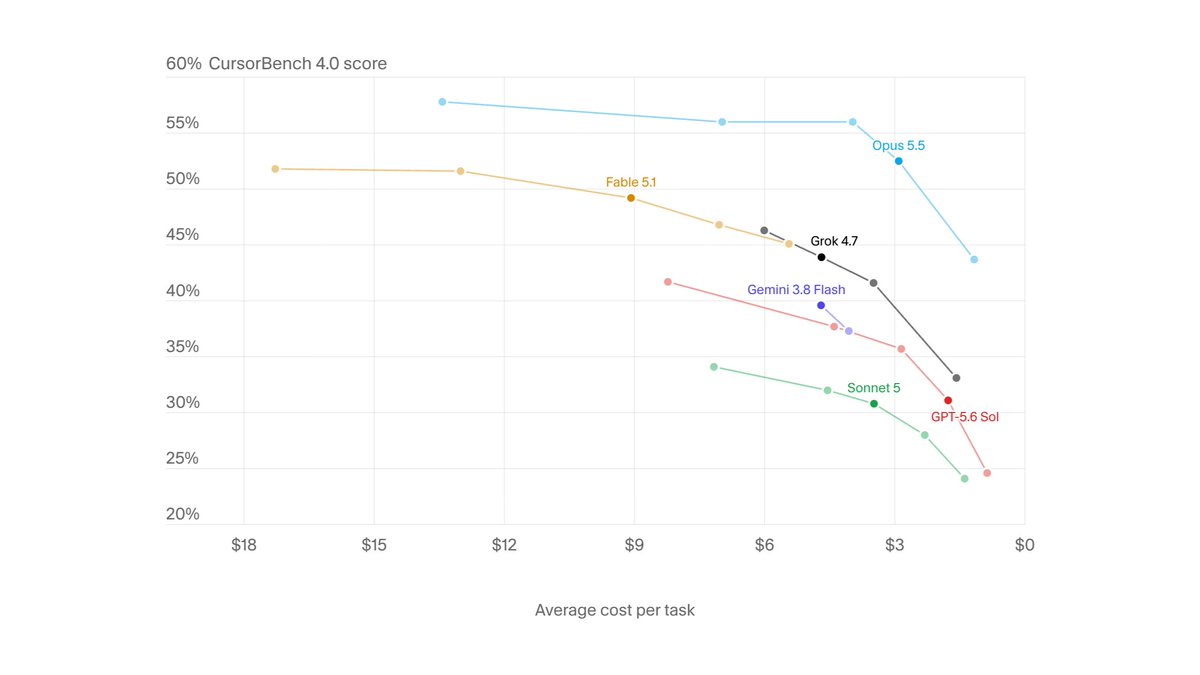
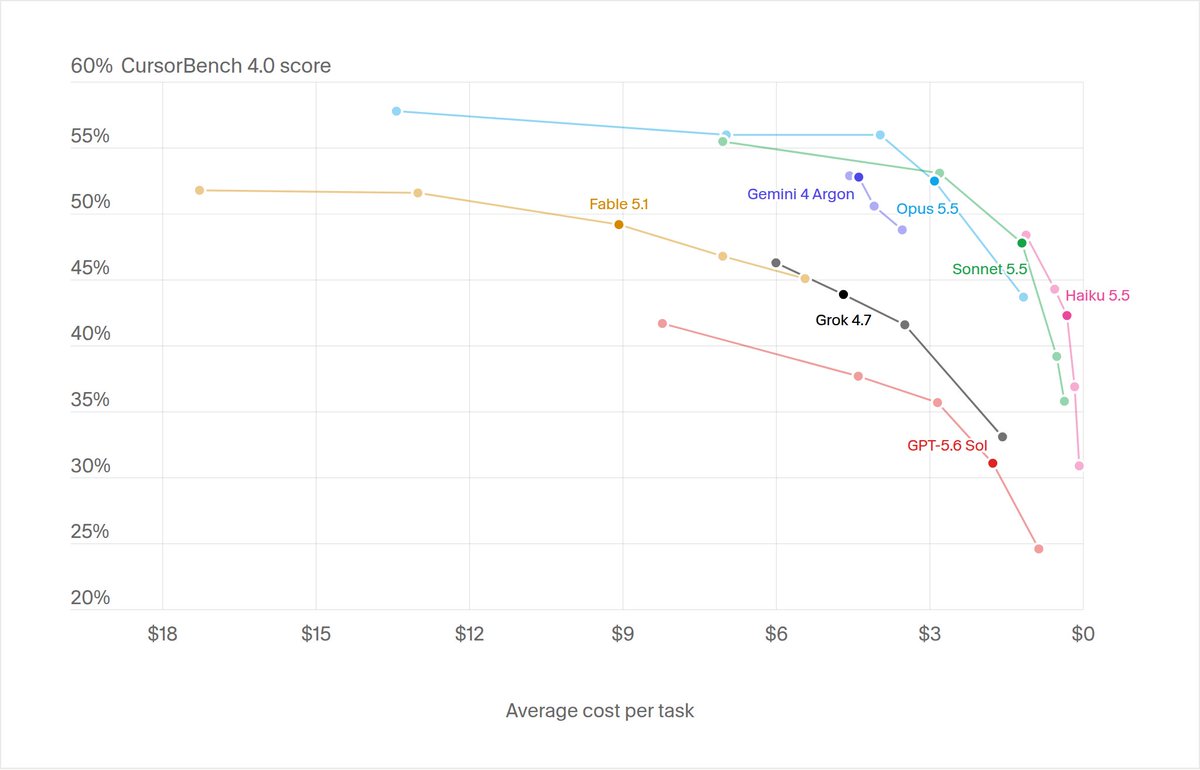
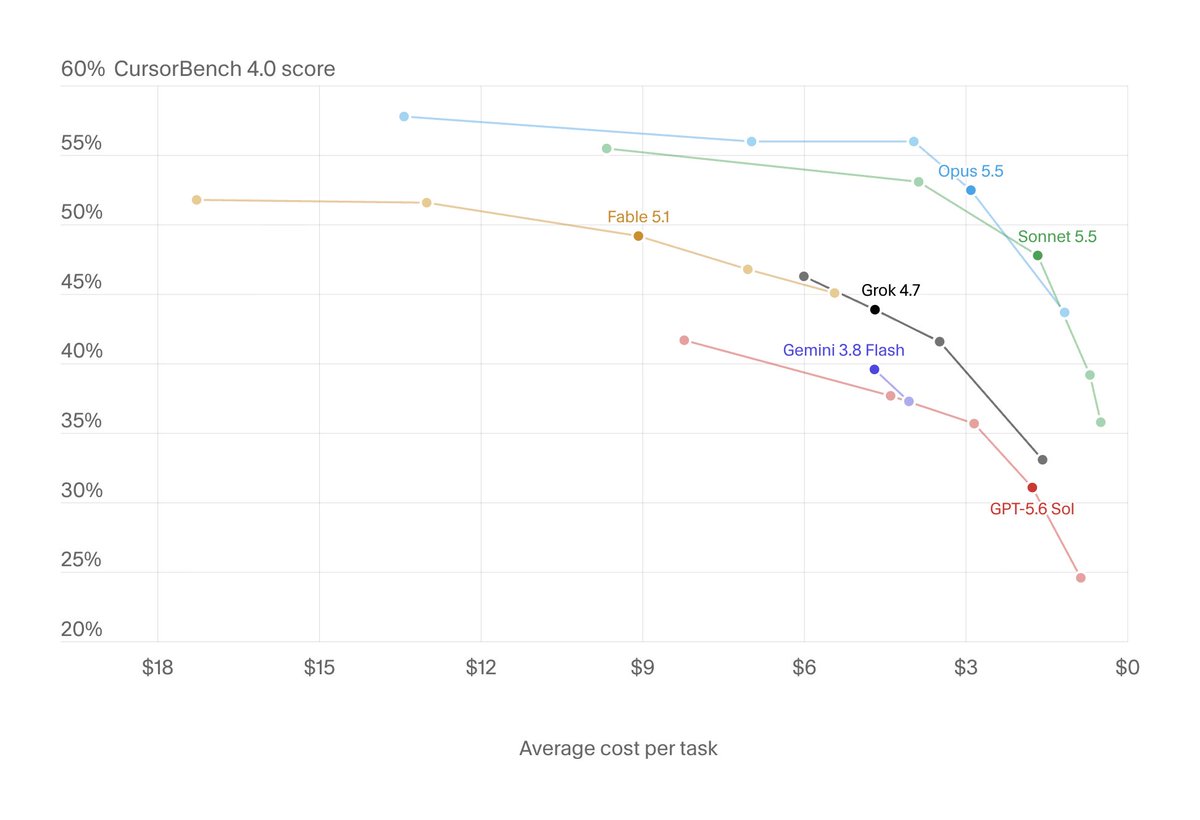
Claude Opus 5.5 is now available in Cursor! It's the new top model on CursorBench at 57.8% (Max) and costs 40% less per task than Opus 5.
Context
Cursor said on September 22 that Anthropic's Claude Opus 5.5 was available to its users and had become the top model on CursorBench, Cursor's own coding , with a score of 57.8% at the Max setting. Cursor also said Opus 5.5 costs 40% less per task than Opus 5.
The cost figure is per task, not per . What a model costs to finish a task depends on the price of each token and on how many tokens it spends getting there, so a per-task saving can come from either. The post's text gives only the per-task number and does not say how much of the 40% comes from pricing and how much from the model doing the work in fewer tokens.
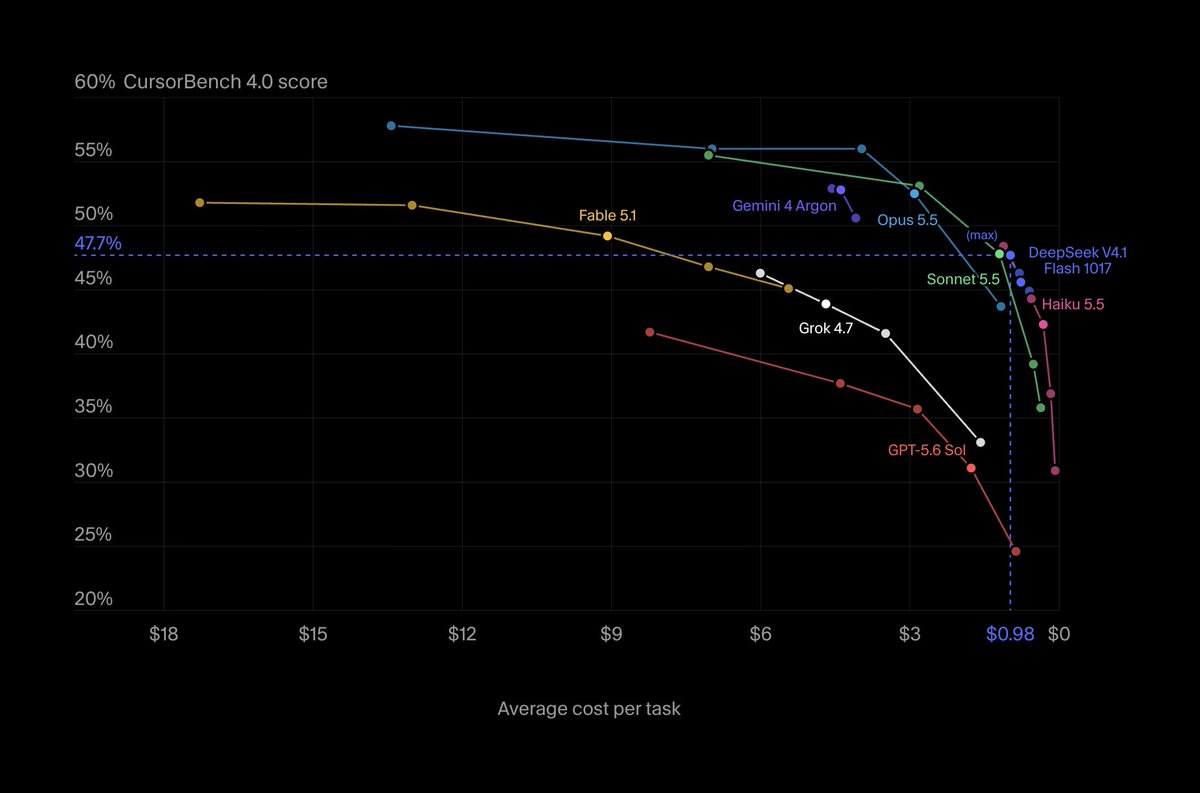
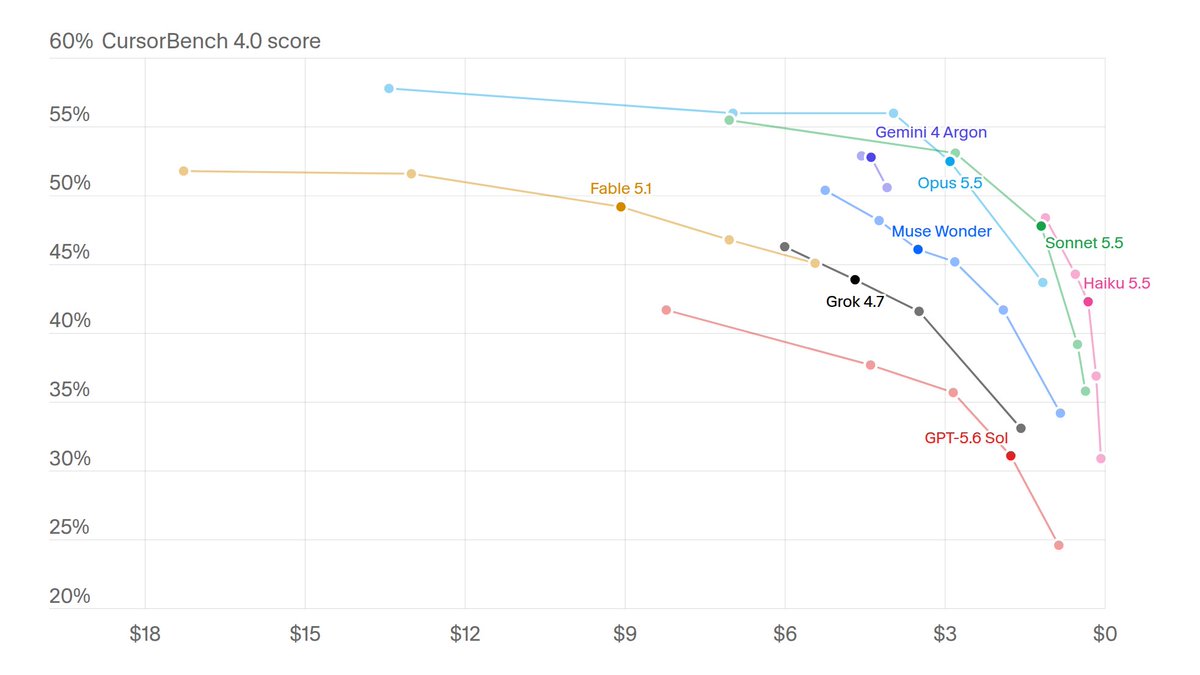
Both numbers are Cursor's own measurements, and the post's text does not name the CursorBench version. That makes the 57.8% hard to set against Cursor's other results. Earlier in September, Cursor reported Claude Fable 5.1 at 73.4% at max effort on CursorBench 3.2, a higher number than the one it now calls the top score, so the two posts cannot be compared without knowing which version produced 57.8%. The effort setting matters too: in October Cursor put Gemini 4 Argon at 52.8% at default effort and called that on par with Opus 5.5 without saying which Opus 5.5 setting it meant, while the 57.8% headline is the Max result.
Checking sign-in…
Loading comments…