Cursor puts Fable 5.1 at the top of its own coding bench
- Source
- x.com
- Date

Claude Fable 5.1 is now available in Cursor! It's the most capable model we’ve run on CursorBench 3.2, scoring 73.4% at max effort. We found it especially skilled at verifying its own work, allowing it to take on difficult coding tasks from start to finish.
Context
Cursor reported that Anthropic's Claude Fable 5.1 scored 73.4% on CursorBench 3.2 at maximum effort, the most capable result it had run on that at the time of the September 1 announcement. Cursor also attributed the model's usefulness on difficult coding tasks to its tendency to verify its own work.
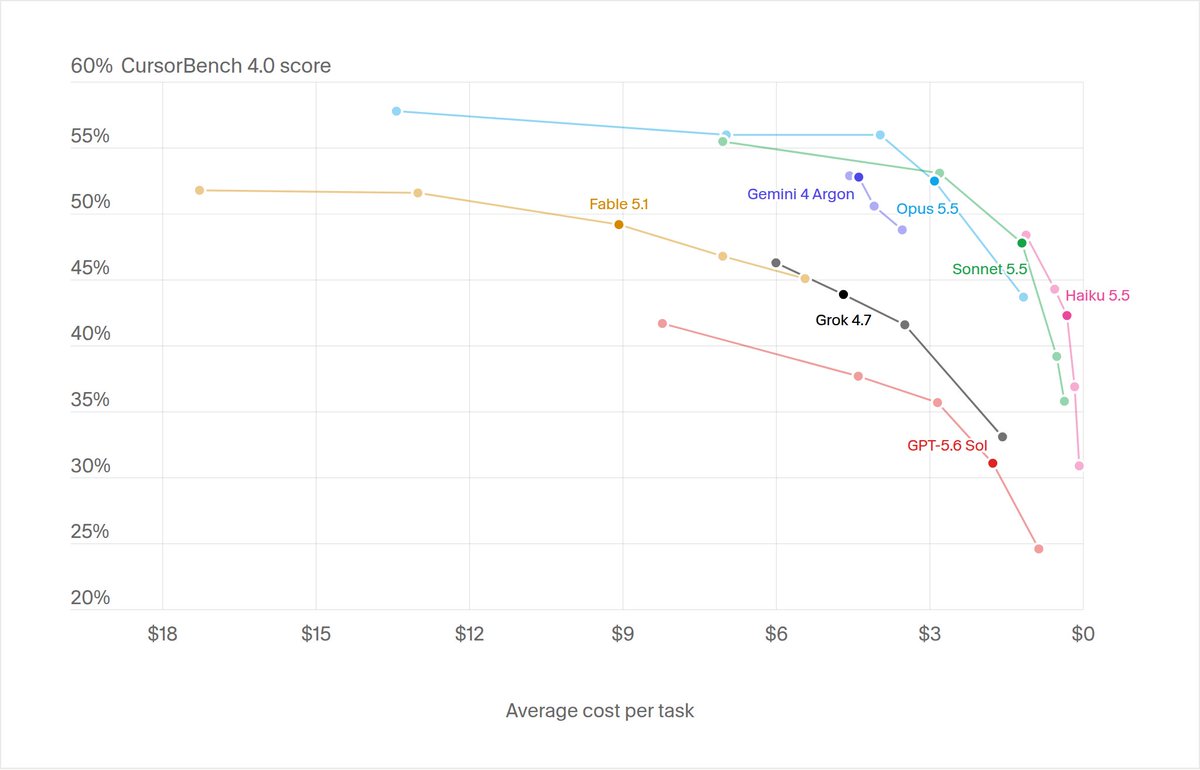
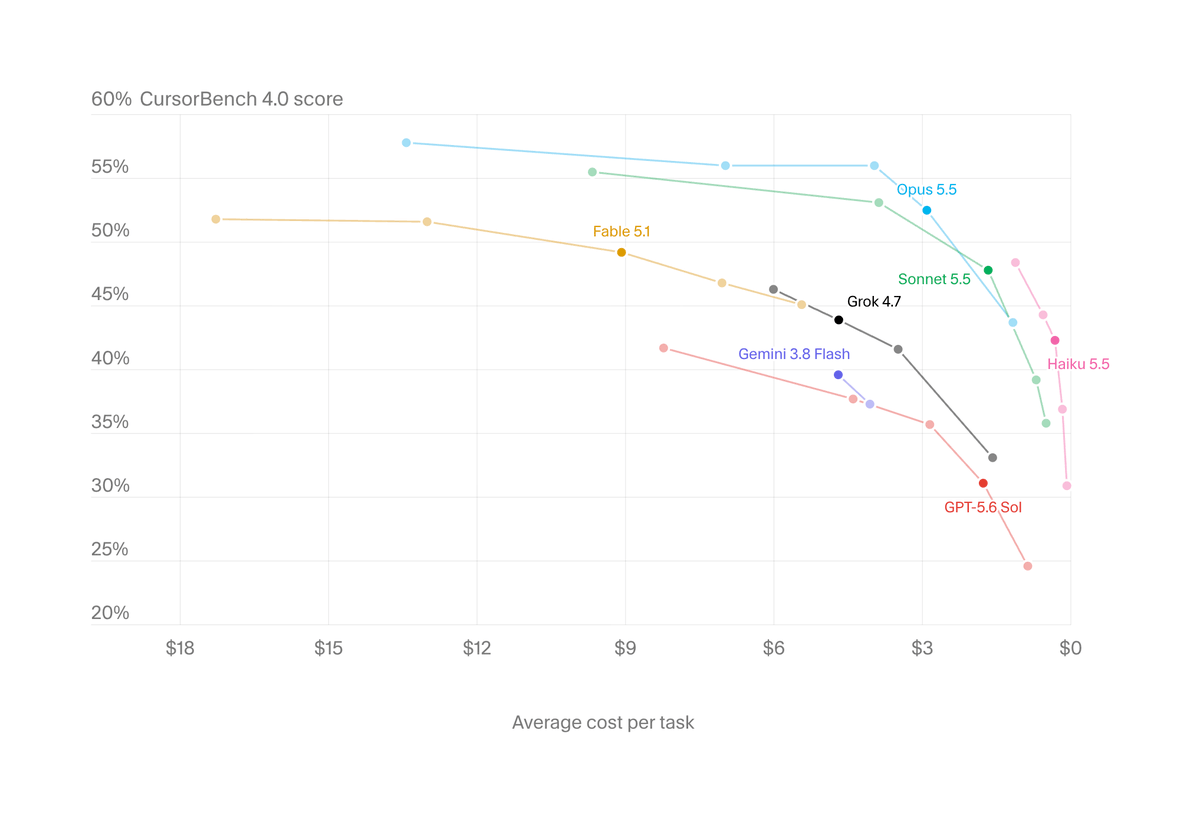
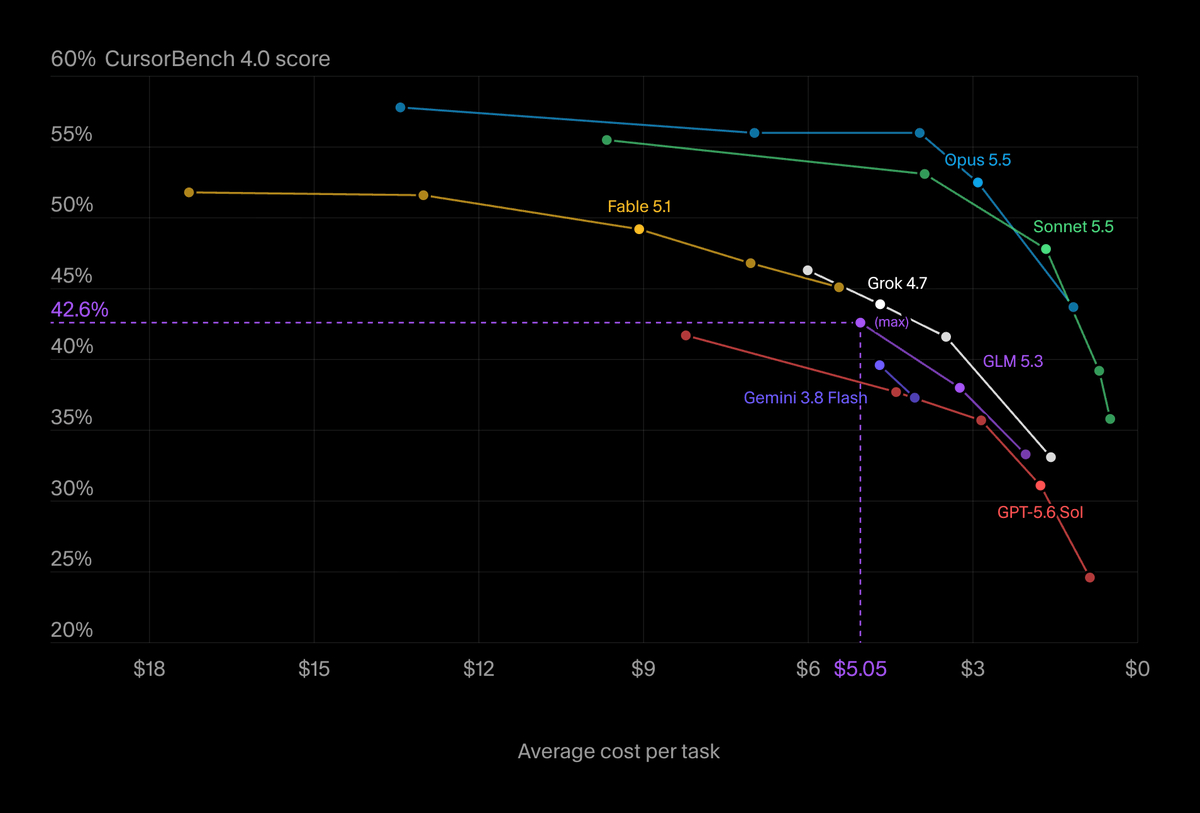
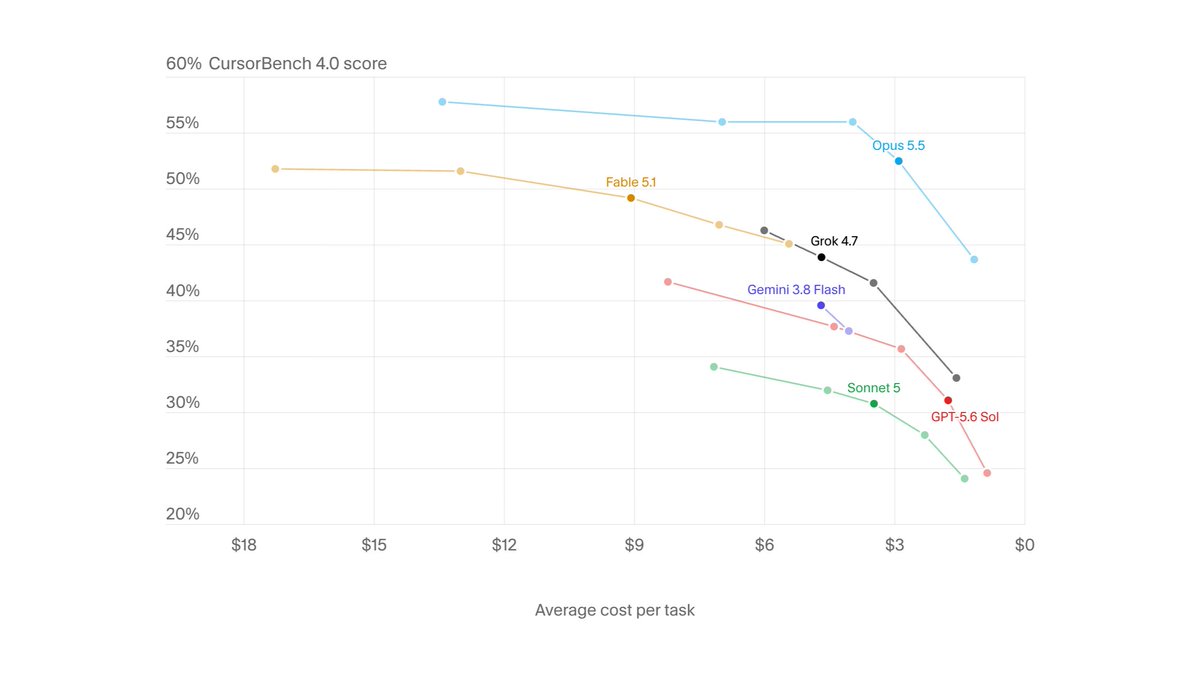
Cursor's benchmark description says the tests use ambiguous, multi-file tasks drawn from real Cursor sessions. That makes the result relevant to work inside a coding , while tying it to a particular task set and effort setting. The same page records that Cursor added CursorBench 4.0, with new long-horizon problems, on September 10, 2026, so the 3.2 score belongs to its own earlier version.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.

Checking sign-in…
Loading comments…