Tencent opens Hy4 preview: 770B sparse MoE with a 1M-token window
- Source
- x.com
- Date

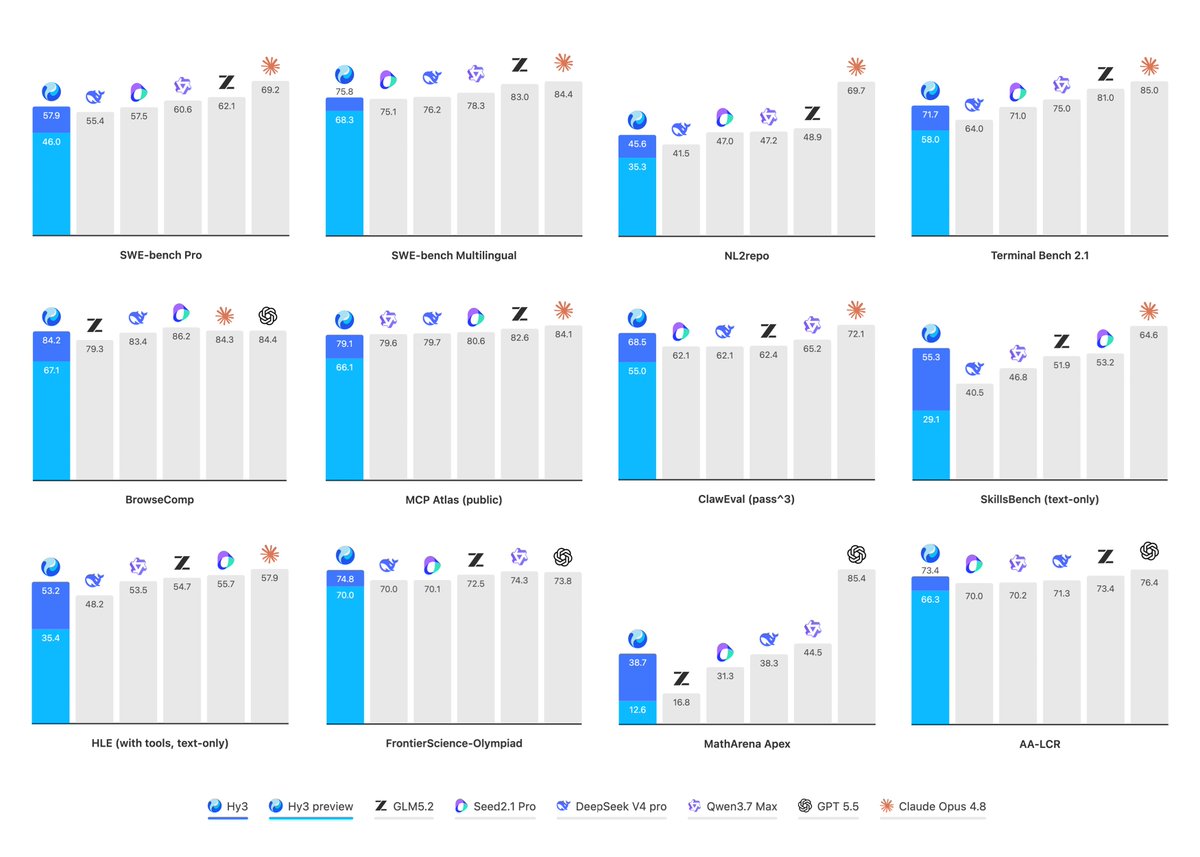
🚀 Hy4 preview is here. 770B, 49B active, 1M context. Built for productivity. Open source frontier. Consistent affordable price. Use it. Tell us what breaks. More on Hy blog:https://t.co/rbl1IWRk3C HuggingFace:https://t.co/mE9wevH5XR Github:https://t.co/pyl9zckpoL

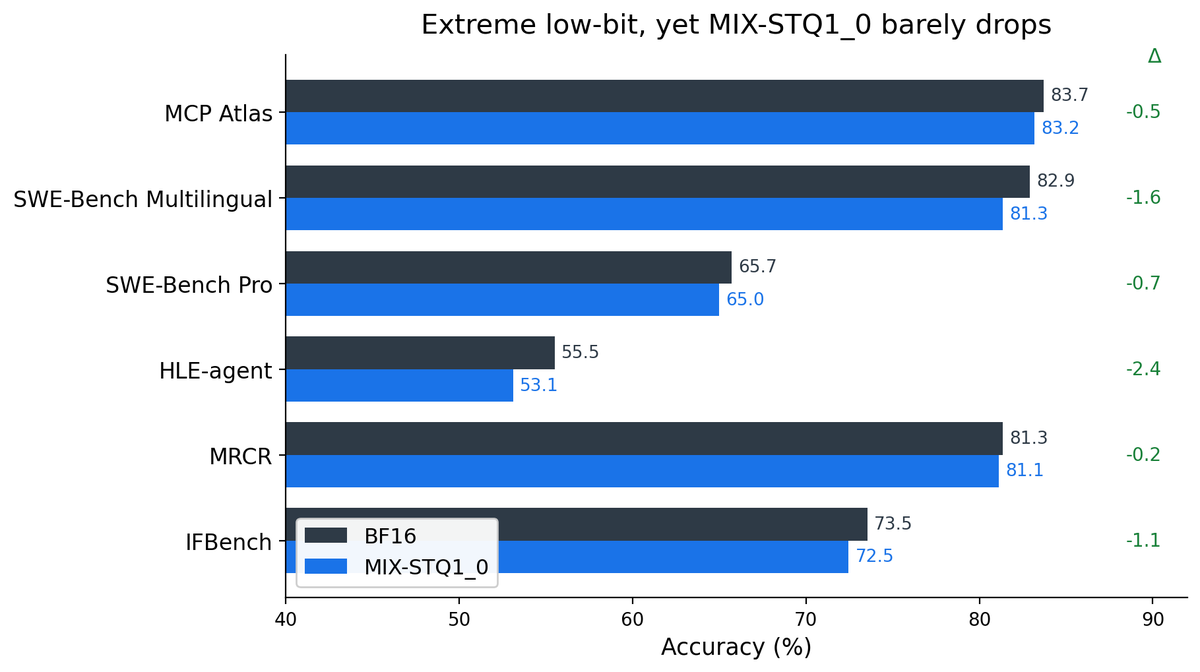
We compressed Hy4-preview from 1.5TB to ~200GiB GGUF and it still works well ! Meet MIX-STQ1_0.The trick isn’t just going low, it’s deciding where: calibration data picks each layer’s bit-width, some down to 1.31-bit STQ1_0, some up to 2.06-bit IQ2_XXS. Same budget, lower error. Accuracy barely moves vs BF16 📊 MCP Atlas 83.7→83.2 📊 SWE-Bench multi 82.9→81.3 📊 MRCR 81.3→81.1 📊 IFBench 73.5→72.5 See the details on HF : AngelSlim/Hy4-preview-GGUF Weights & low-bit GGUFs 👇 https://t.co/9uM9NT9Wem #LLM #Quantization #llamacpp #Hy

Context
Tencent's Hy4 preview separates total model capacity from the computation used for each piece of text. Its backbone contains 770 billion parameters, but activates 49 billion per token by routing work through selected expert blocks. The model specification also lists a one-million-token , describing how much text the model can work with at once. These numbers describe different properties: the size of the full network, the portion used during generation and the capacity of its working context.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- calibration — How well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.
 postExplorationBench tests how models explore, with exactly verifiable grading
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model
Checking sign-in…
Loading comments…