BenchMIRT: What are LLM benchmarks actually measuring?
- Source
- allenai.org
- Date
Context
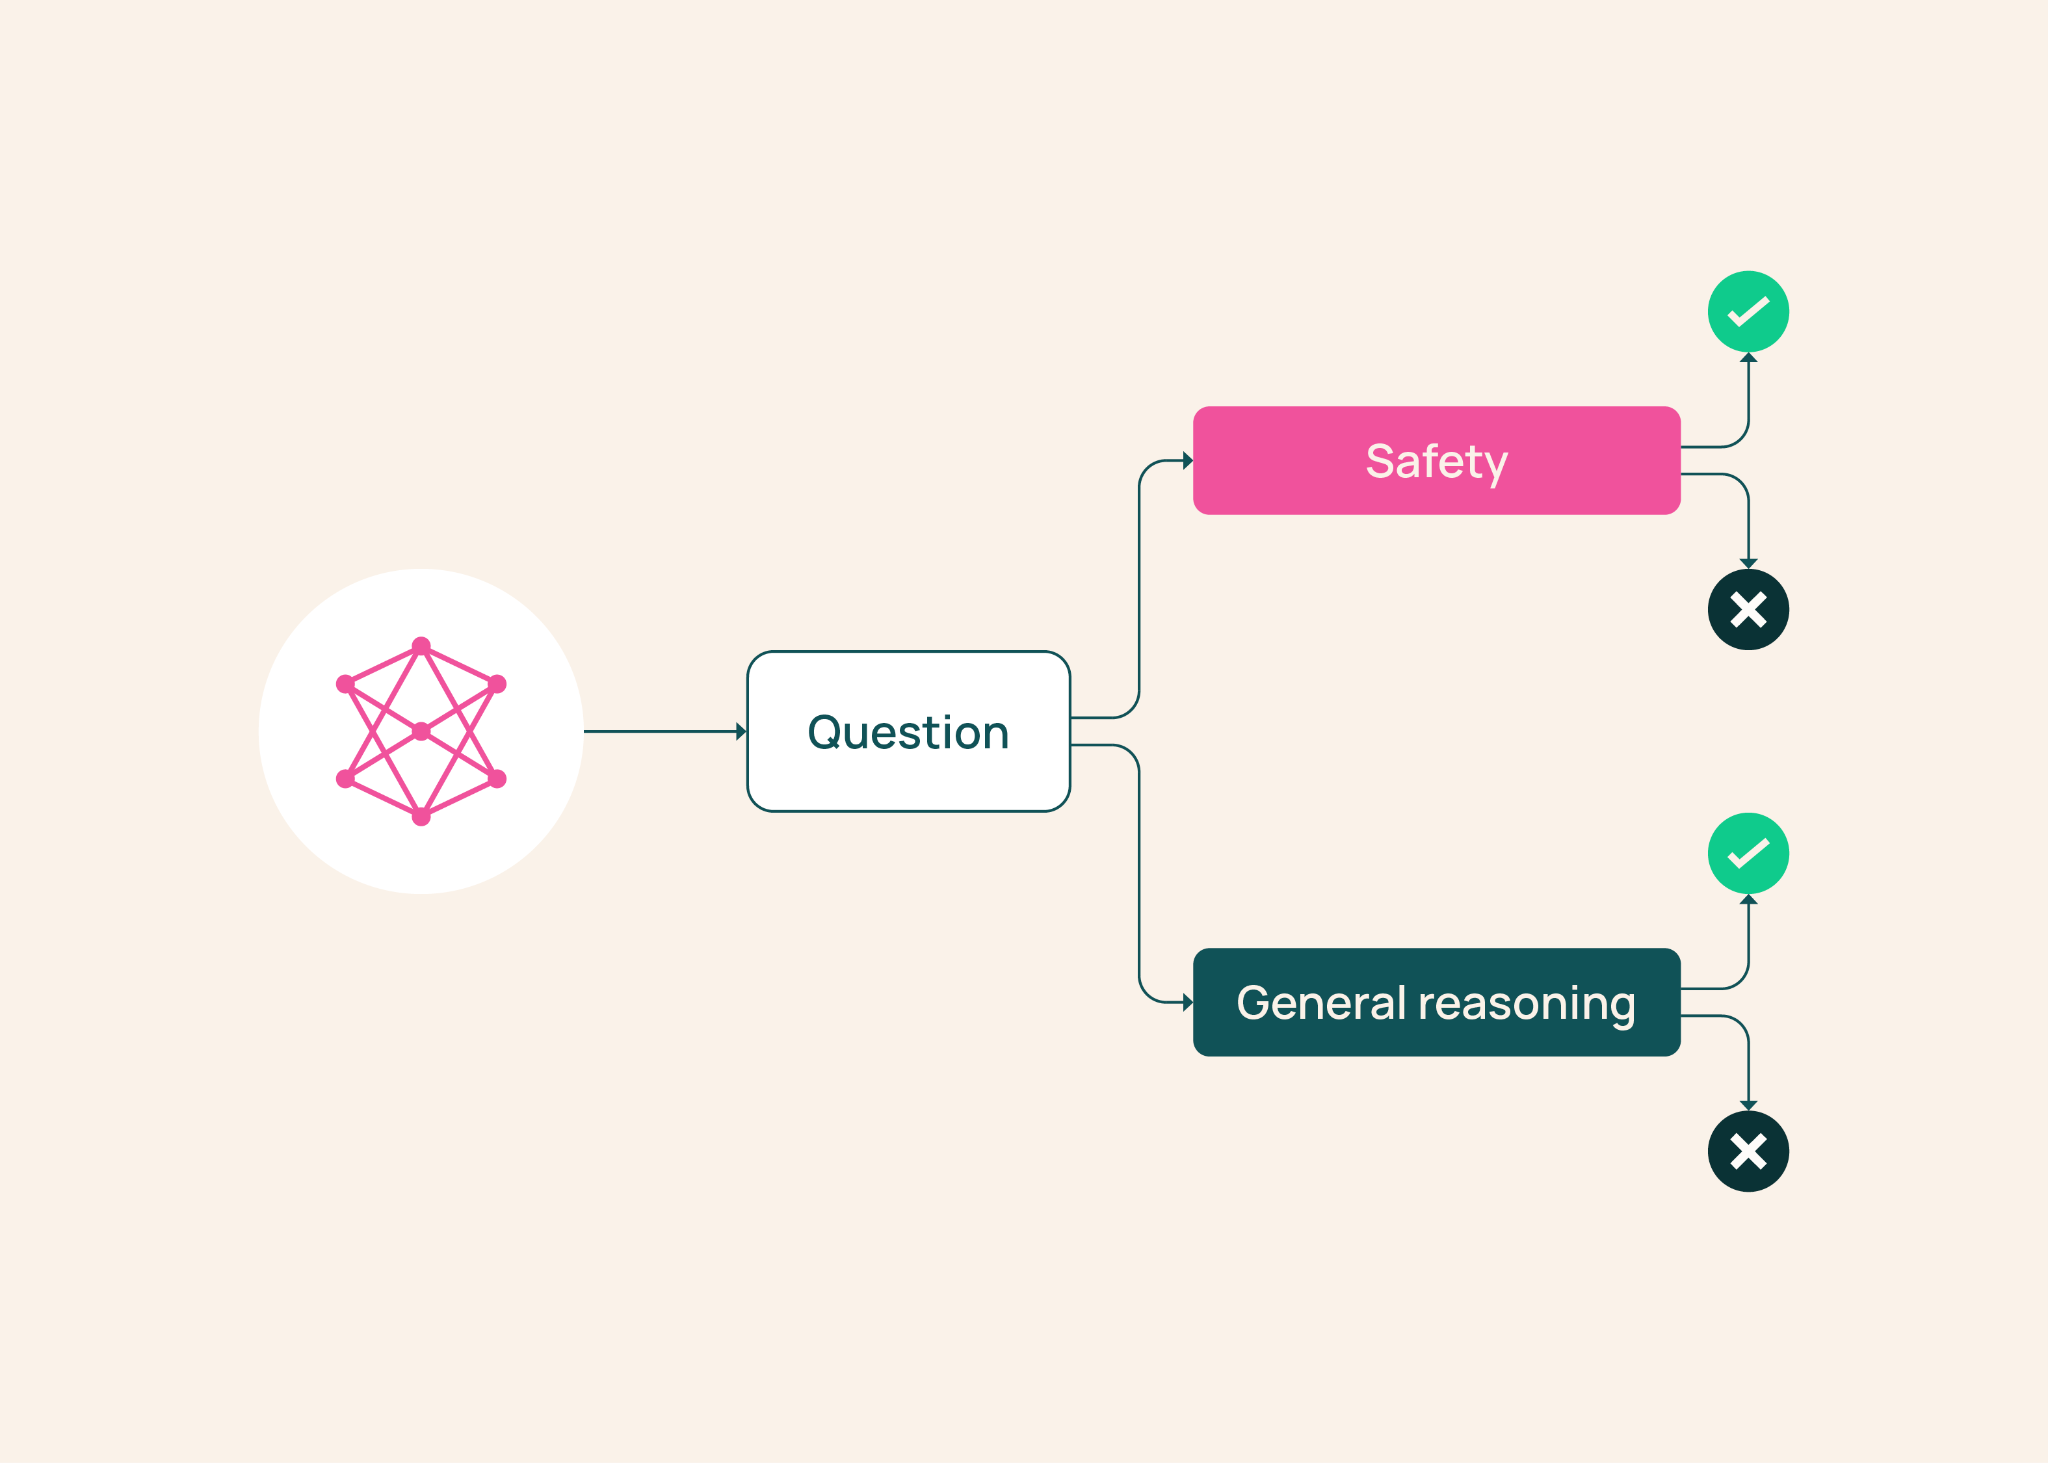
A labeled as a safety test can also measure whether a model understands the question. Ai2's BenchMIRT analysis examines individual answers across models to estimate which underlying abilities predict success, rather than assuming every question measures the benchmark's advertised purpose.
Across 100 models and 16 benchmarks, the analysis recovered dimensions associated with reasoning and safety. Questions in BBQ, a social-bias benchmark, tracked reasoning much more strongly. A poor score can therefore reflect difficulty interpreting the scenario as well as biased behavior. This finding concerns the selected evaluations and models released by March 2025; it does not establish that every AI capability reduces to those two dimensions.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
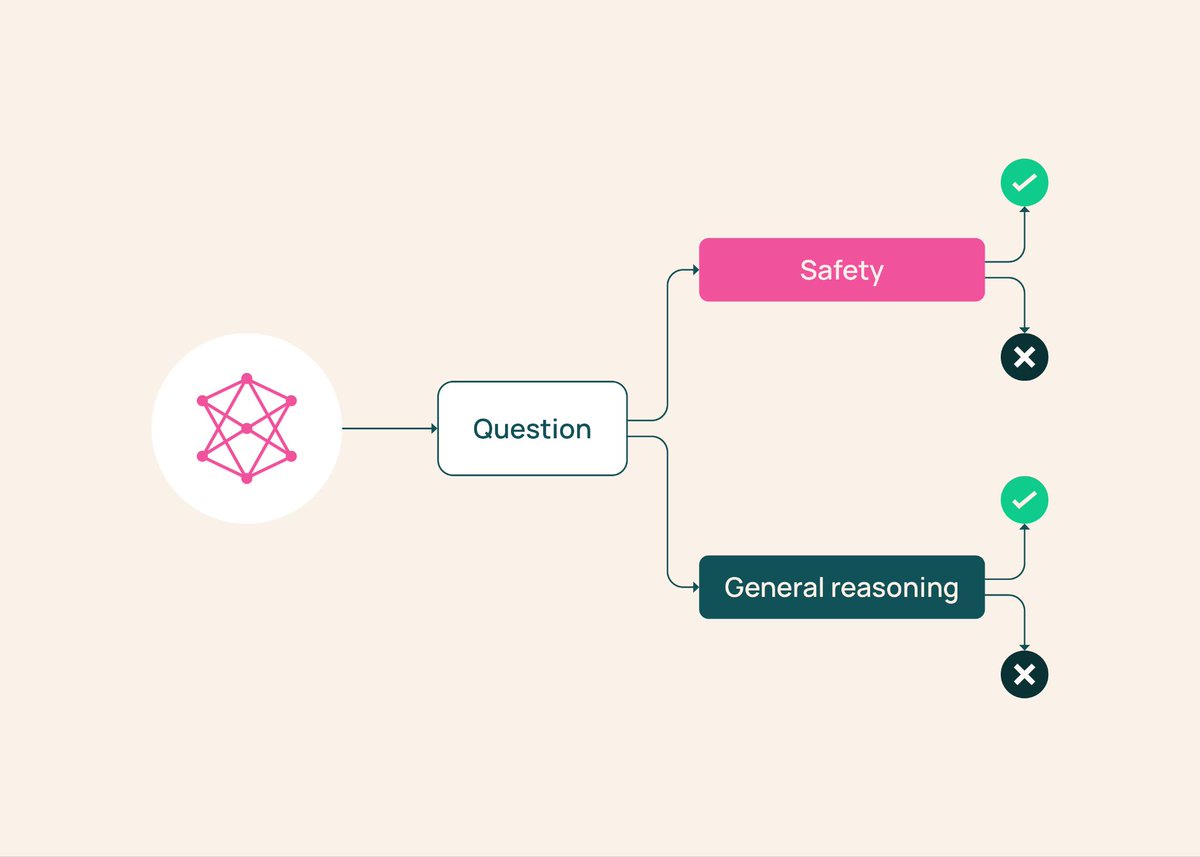 postAi2 uses psychometrics to audit what LLM safety benchmarks measureAi2
 articleFinding Flawed Questions in AI Benchmarks with PsychometricsStanford AI Lab
 articleEvalDetectBench: A Benchmark for Measuring Evaluation Awareness in Frontier Language ModelsXinning Li, Kemunto Ochwang'i, Aryasomayajula Ram Bharadwaj, Alexandra Souly, Robert Kirk
Checking sign-in…
Loading comments…