Artificial Analysis: Muse Wonder Full scores 56, agentic evals jump
- Source
- x.com
- Date
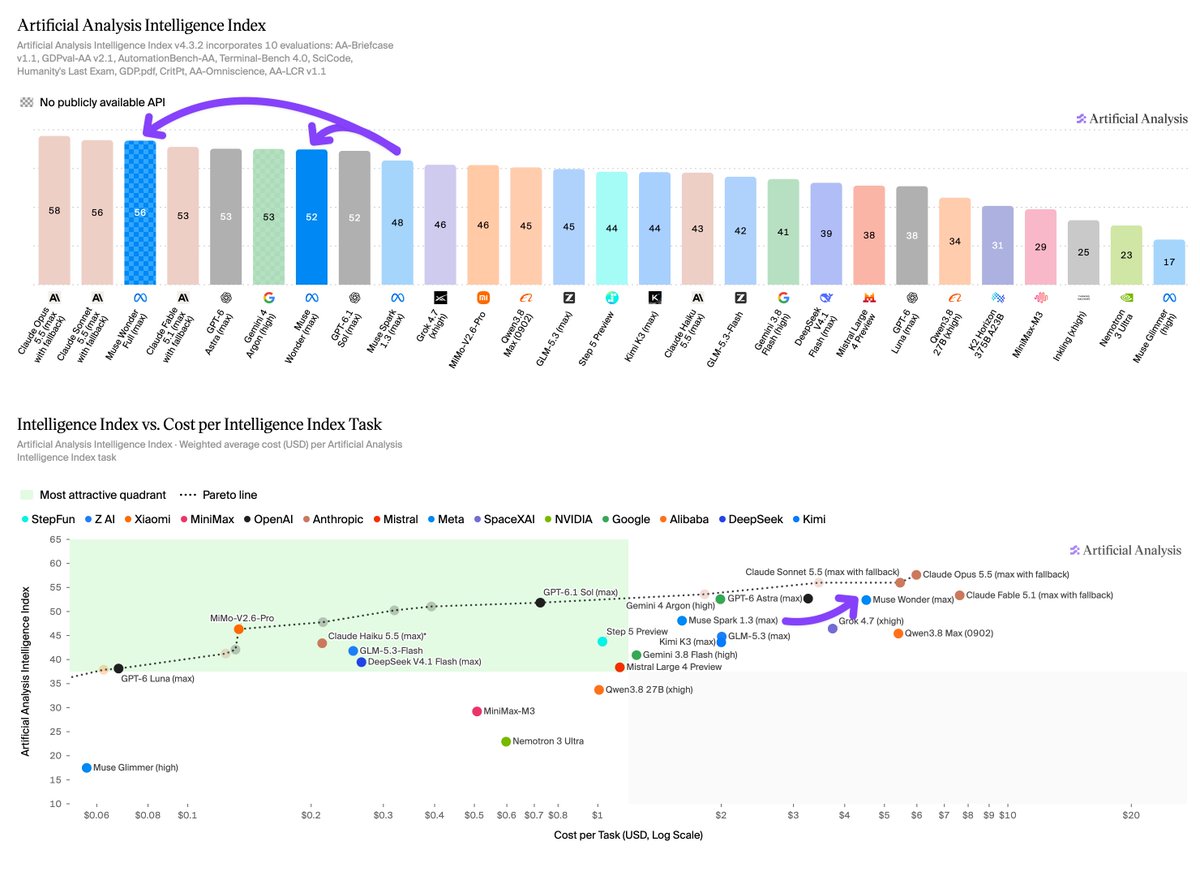
Meta has released Muse Wonder and Muse Wonder Full, achieving Artificial Analysis Intelligence Index v4.3 scores of 52 and 56 at max reasoning effort - each a material gain over Muse Spark 1.3 (max) at 48, with a release gap of only 6 weeks Muse Wonder is available for users on Meta’s first-party API, while Muse Wonder Full is currently only available for Muse Code users. Meta notes that each model is designed for personal and professional agent use Congratulations to @AIatMeta, @finkd, and @alexandr_wang on the release! Key Takeaways: ➤ Both models exhibit a material jump in overall Intelligence Index score. Muse Wonder Full (max) improves on Muse Spark 1.3 (max) across all ten Intelligence Index evaluations, gaining 8 points to 56. The largest gains were seen in agentic evaluations: Terminal-Bench 4.0 (+24 points, 33% to 57%), GDPval-AA v2.1 (+176 Elo, 1681 to 1857), and AA-Briefcase (+148 Elo, 1581 to 1729). Muse Wonder (max) gains 4 Intelligence Index points and lands at 52, with notable improvements vs. Muse Spark 1.3 (max) in Terminal-Bench 4.0 (33% to 52%) and AutomationBench-AA (58% to 68%) ➤ Muse Wonder Full (max) places in the top three on six of the ten…
Context
Artificial Analysis reports that Meta's Muse Wonder models improve most strongly on evaluations involving agents carrying out work. In its published results, Muse Wonder scores 52 and Muse Wonder Full scores 56 on Intelligence Index v4.3, compared with 48 for Muse Spark 1.3, all at maximum reasoning effort.
One concrete change is Terminal-Bench 4.0: the evaluator reports 57% for Wonder Full versus 33% for Spark 1.3. Wonder Full improved across all ten constituent evaluations. These results support a broader improvement than a single favorable test, while the composite index score remains a summary rather than a percentage of everyday tasks the model will complete.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…