Gemini 4 Neon goes live on OpenRouter
- Source
- x.com
- Date

Gemini 4 Neon from @GoogleDeepMind is live on OpenRouter! Built for complex software engineering, knowledge work, and science, sitting between Carbon and Hydrogen. Follow @ModelsOnOR for every model launch. https://t.co/i3djjsx25Y
Context
Gemini 4 Neon, the newest model in Google's Gemini 4 family, can now be called through OpenRouter (announcement). OpenRouter is a service that passes API requests on to model providers, so a developer with one OpenRouter account can switch between many companies' models by changing a model name. The listing is a new route to Google's model, not a model of OpenRouter's own: its model page lists Google AI Studio and Google Vertex AI as the providers serving Neon in its standard routing, at $3 per million input and $15 per million output tokens, the same rates Google charges on its own paid tier.
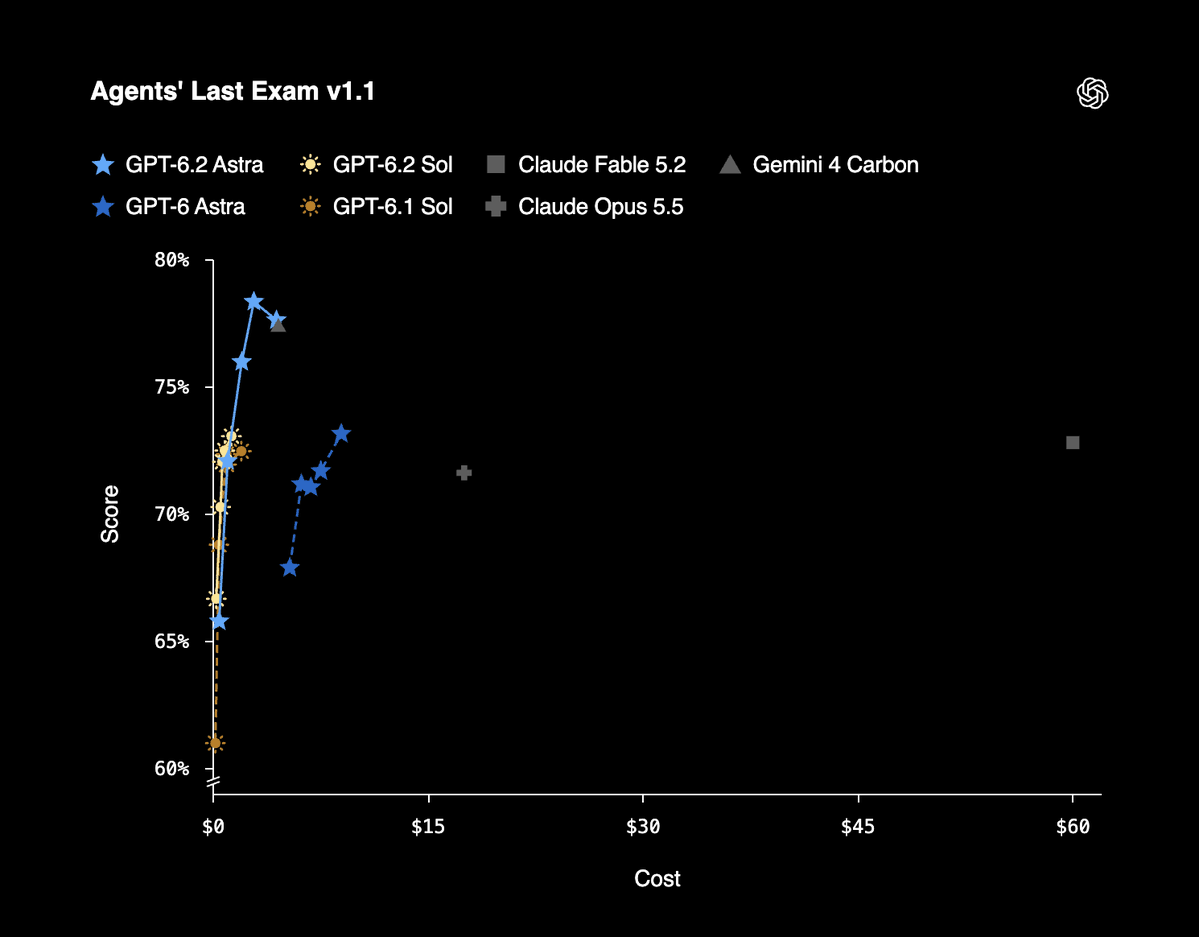
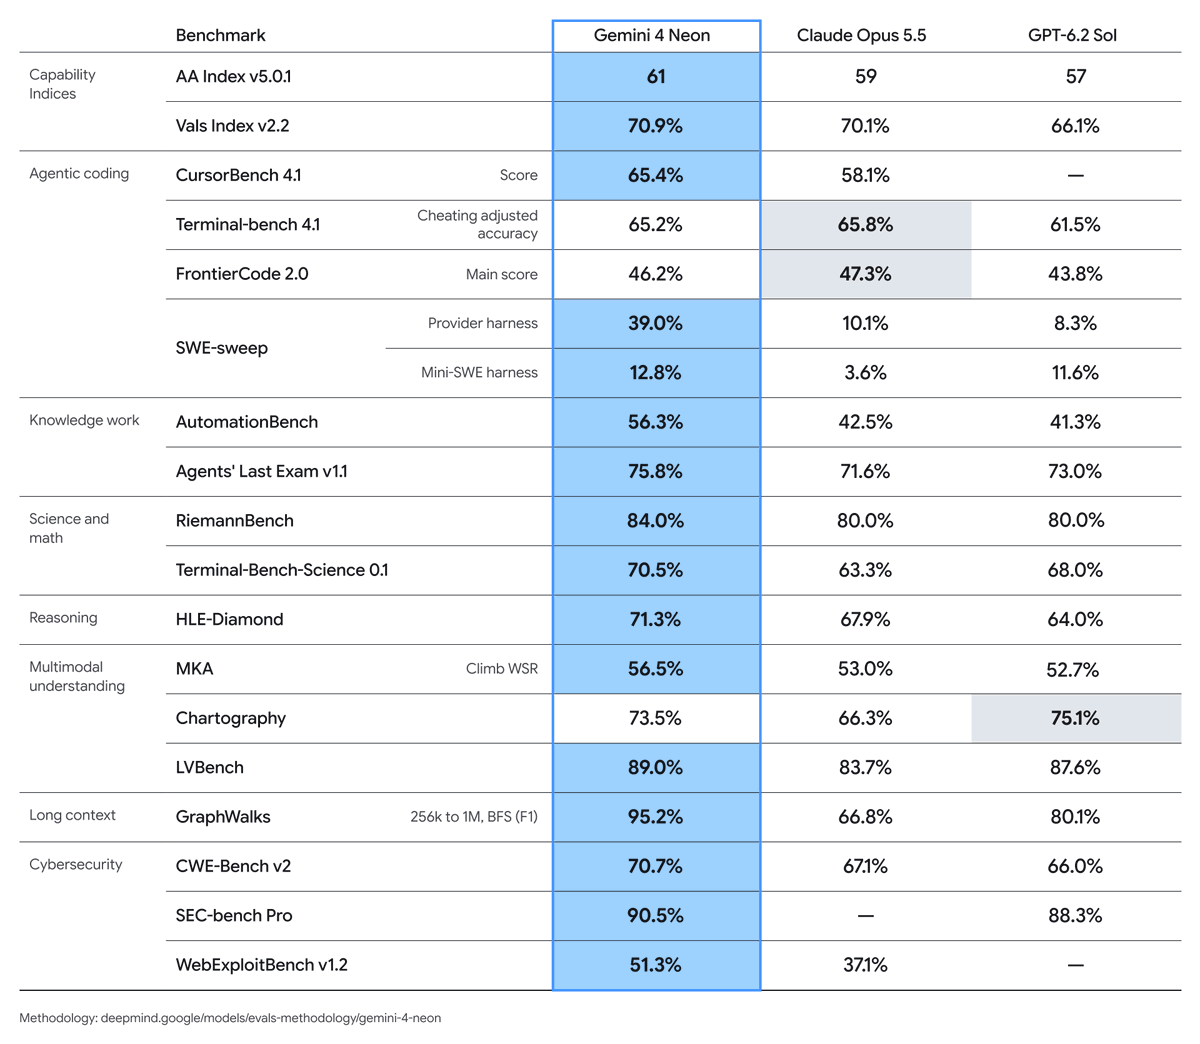
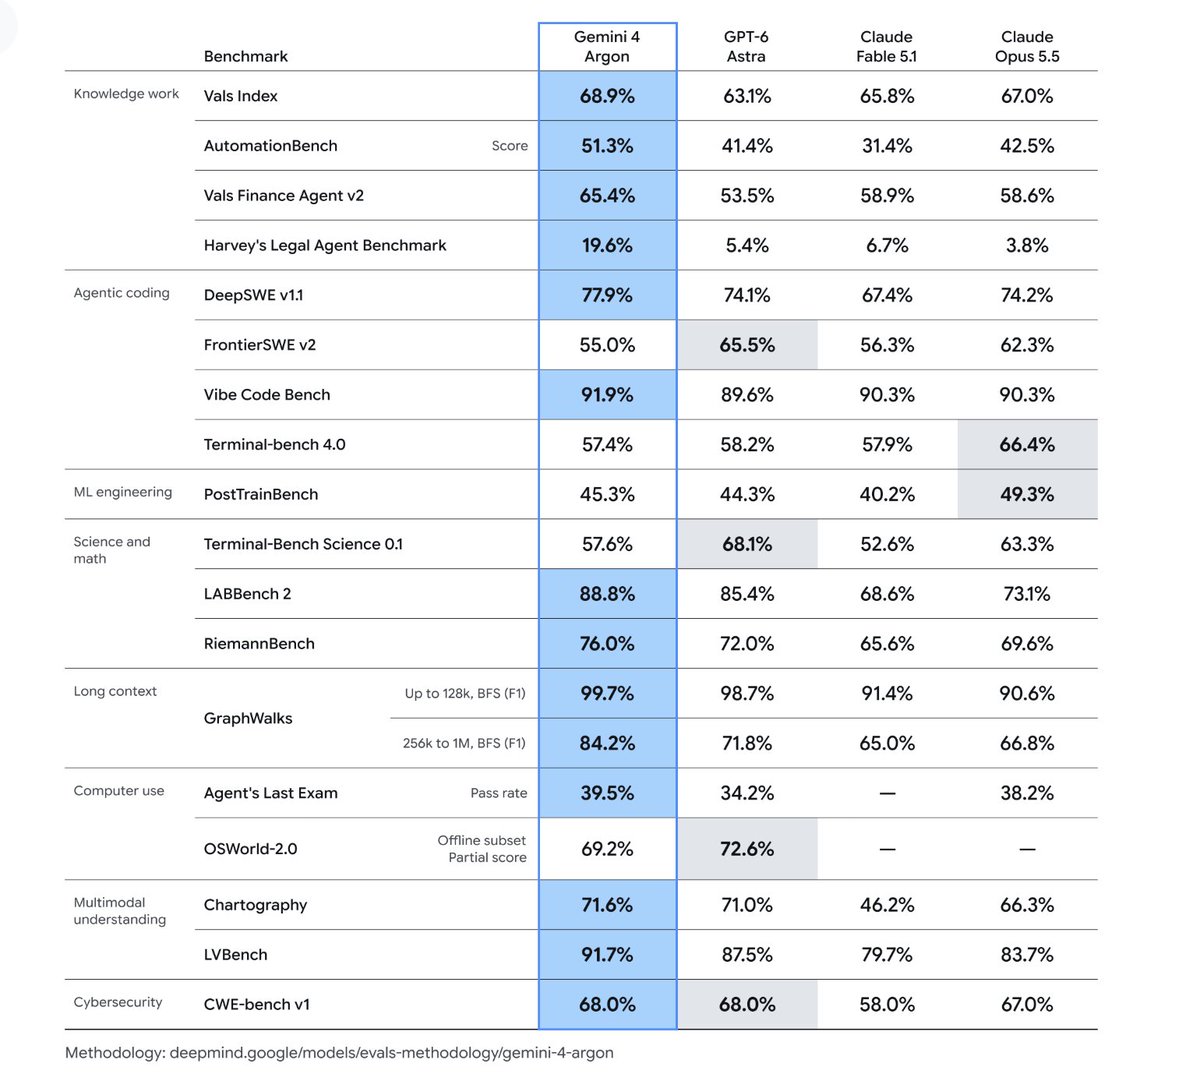
"Between Carbon and Hydrogen" describes the job Google intends for Neon. Google's launch post says Carbon "tackles your hardest, long-horizon projects" and Hydrogen "handles fast everyday execution", while Neon "balances depth and efficiency". It is not a ranking of current prices or measured scores. OpenRouter lists Gemini 4 Carbon at $2 and $10 per million tokens, below Neon, because Carbon is on introductory rates through November 30 and rises to $4 and $20 on December 1, according to Google's pricing page. And in Artificial Analysis's measurements, Neon at its highest thinking level scores one point above Carbon at high, Carbon's top setting, on that group's Intelligence Index, a composite of many benchmarks.
One setting is worth checking when calling Neon this way. Google says Neon's default thinking level, how much it reasons before answering, is high, and Cursor's headline CursorBench score for Neon is at high. OpenRouter's model data, checked November 19, lists medium as the default reasoning effort for Neon and for the other Gemini 4 models, and accepts low, medium, high and xhigh. On Cursor's coding benchmark, Neon scored 57.7% at medium and 63.7% at high, so developers who want the behavior behind those headline figures should set the effort level explicitly rather than rely on the default.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…