GLM-5.3 vs. GLM-5.3 Flash on DeepSWE: Cost, Coding, and Routing
Source
together.ai
Date
Context
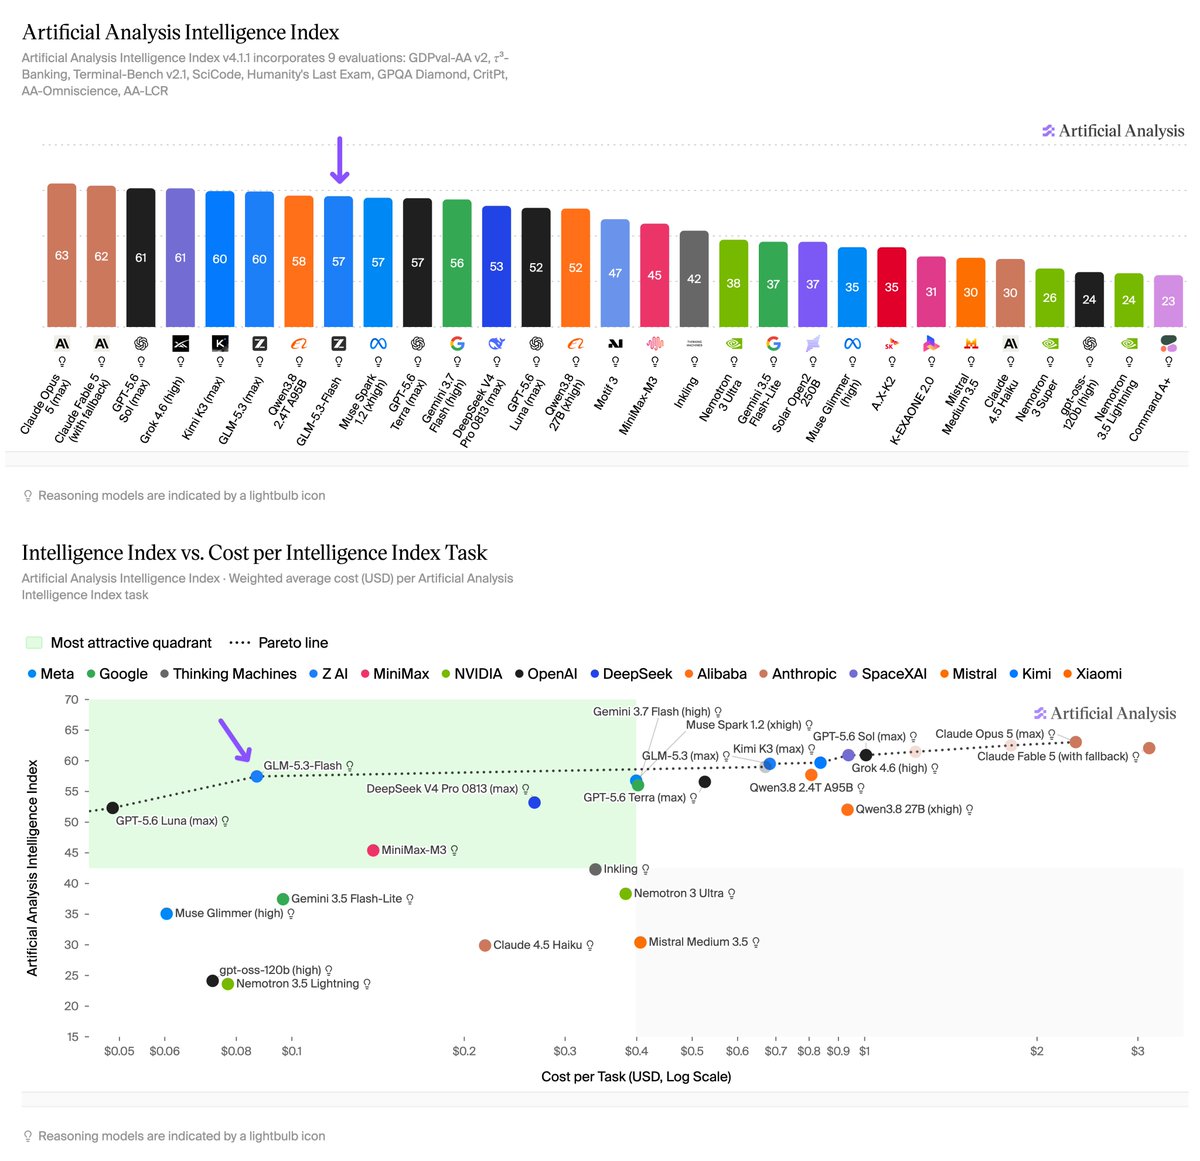
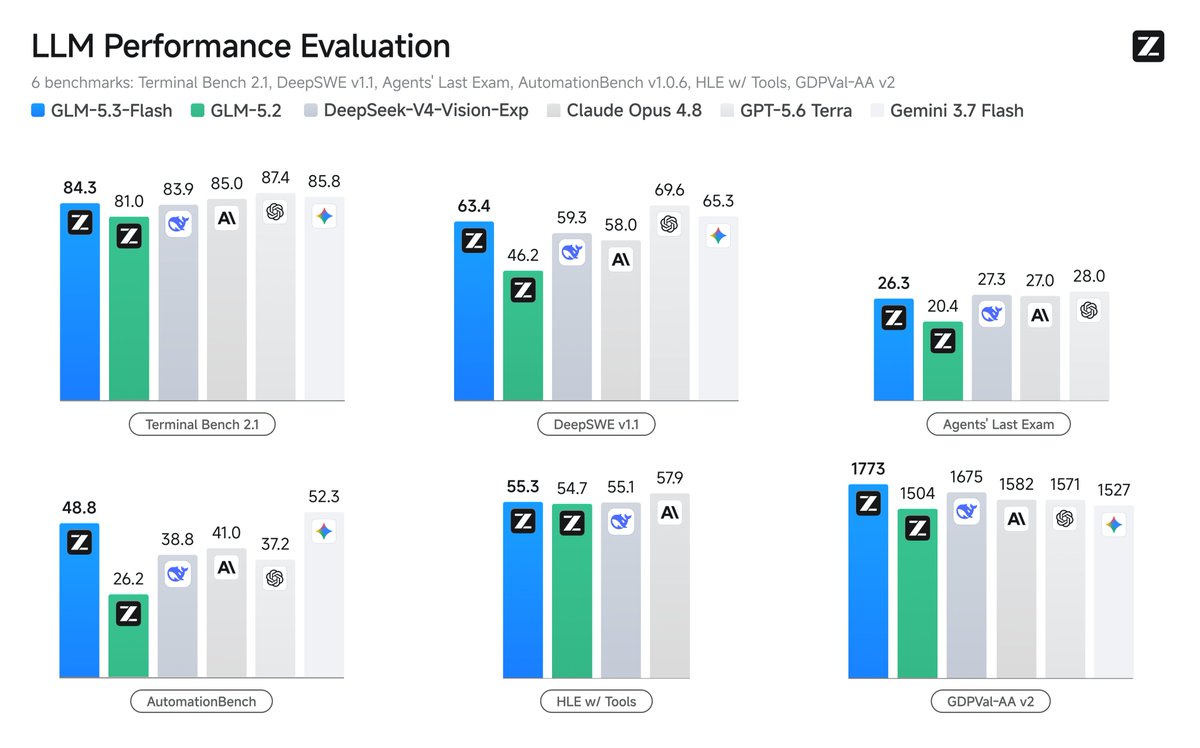
A cheaper coding model can become more competitive when a workflow allows retries and can check the results. In Together AI's own DeepSWE comparison, GLM-5.3 Flash achieved 63.4% single-attempt success against 69.0% for the full model. Average cost per attempt was $0.24 versus $3.99.
Across 113 software-engineering tasks with up to four attempts per model, the share solved at least once reached 85.0% for Flash and 87.6% for the full model. Those figures make retry tolerance central to the comparison: eventual success is useful only when a workflow can recognize a passing solution. They do not establish that the models are equally reliable on the first attempt.
Terms in this piece · Glossary
distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.