Gemini 3.8 Flash TTS takes the top spot for pronunciation robustness
- Source
- Artificial Analysis
- Date

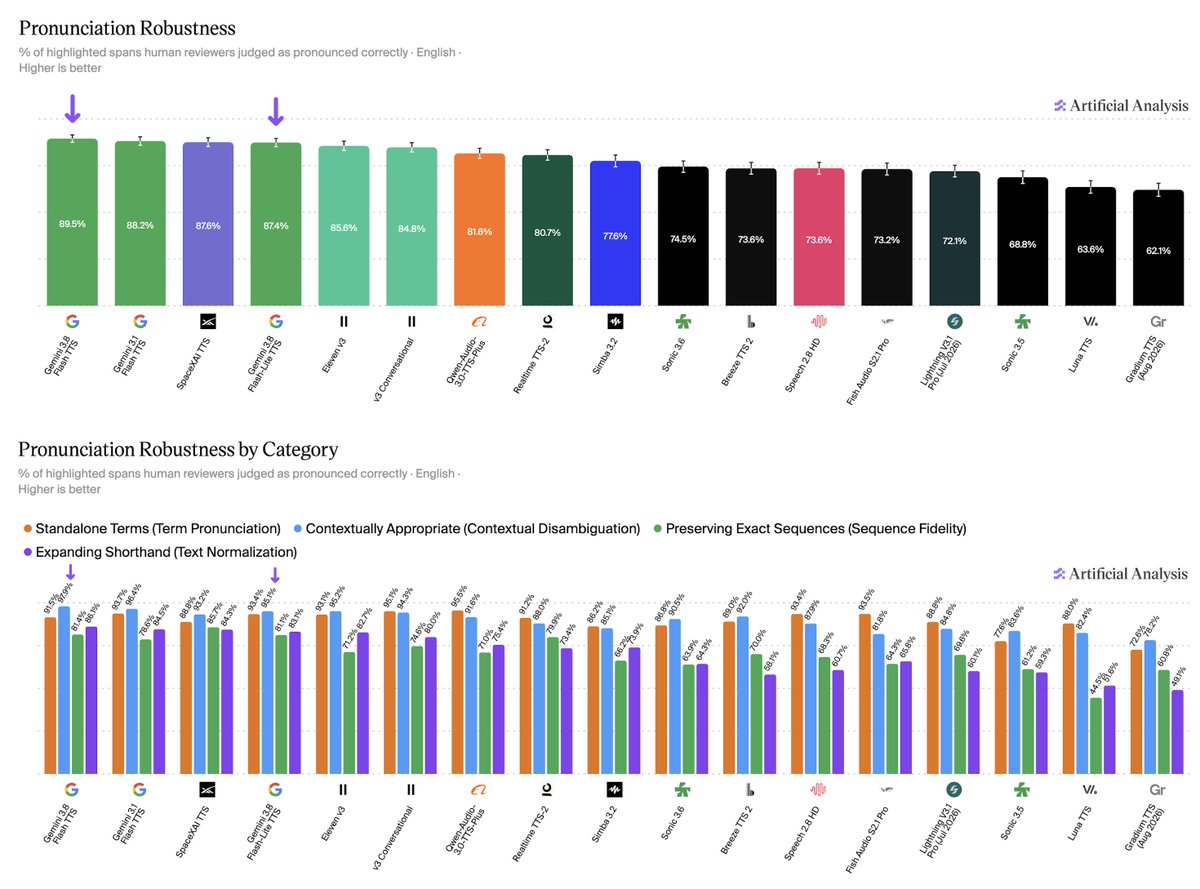
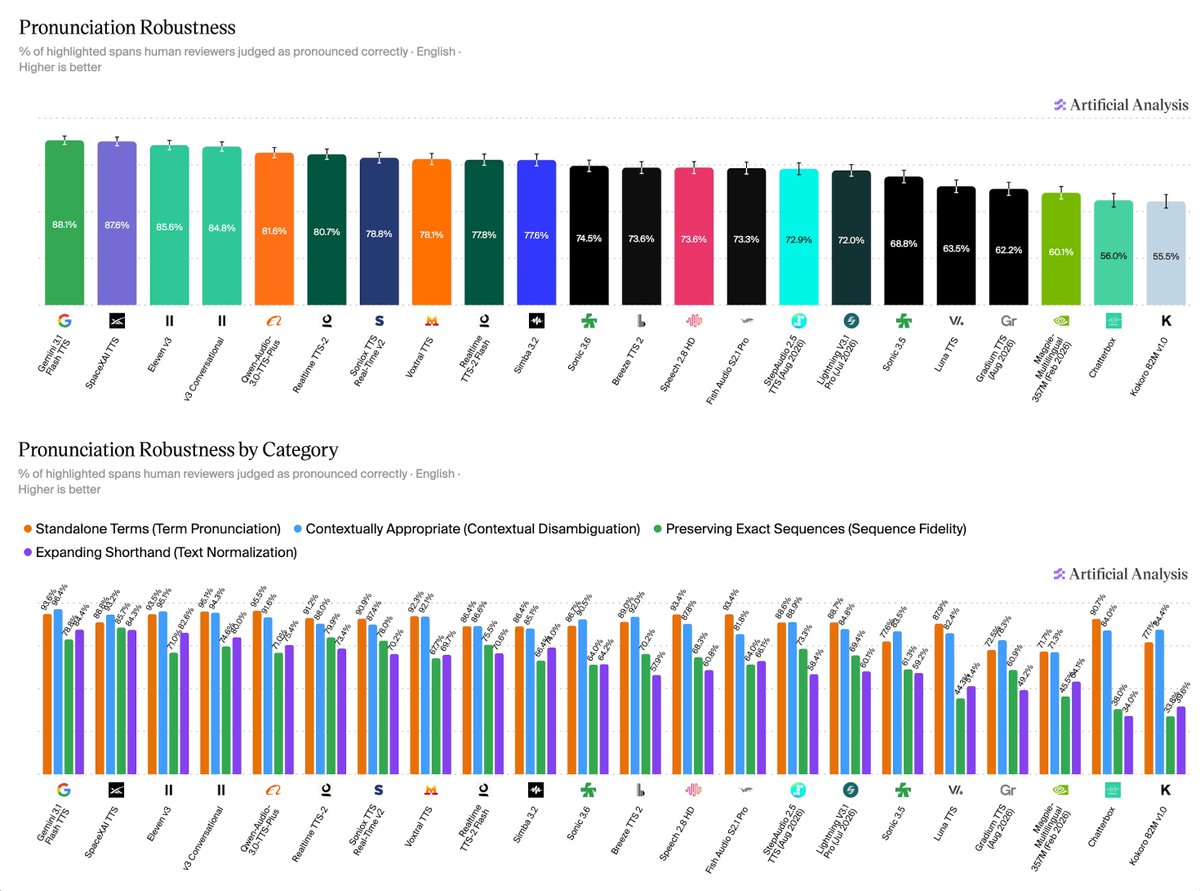
Gemini 3.8 Flash TTS takes the #1 spot on the Artificial Analysis Pronunciation Robustness benchmark at 89.5%, ahead of Gemini 3.1 Flash TTS at 88.2%, SpaceXAI TTS at 87.6%, and Gemini 3.8 Flash-Lite TTS at 87.4%. Gemini 3.8 Flash TTS leads on Contextually Appropriate pronunciation at 97.9% and Expanding Shorthand at 86.1%, while SpaceXAI TTS leads on Preserving Exact Sequences at 85.7% and Qwen-Audio-3.0-TTS-Plus leads on Standalone Terms at 95.5%. Listen to examples from our Pronunciation Robustness benchmark below ⬇️
Example audio generated by Gemini 3.8 Flash TTS for the Contextually Appropriate category of speech generation including "St. Mary's is on Church St.", "That excuse does not excuse the delay.", and "The instructions say to wait 30 sec. before reading sec. 4."

Example audio generated by Gemini 3.8 Flash TTS for the Expanding Shorthand category of speech generation including "Median latency was 12 ms, reported as p50.", "Take the elevator to the 3rd Fl and turn left.", and "The Class of '09 reunion is on 9/9, of all days."

Compare Text to Speech models across all benchmarks: https://t.co/gdkyEw7YDB Learn more about our Pronunciation Robustness Benchmark: https://t.co/mLJRAEFMYg
- Artificial Analysis' Pronunciation Robustness scores how accurately TTS models read tricky text: Gemini 3.8 Flash TTS leads at 89.5%, ahead of Gemini 3.1 Flash TTS (88.2%), SpaceXAI TTS (87.6%) and Gemini 3.8 Flash-Lite TTS (87.4%).
- Category leaders differ: Gemini 3.8 Flash TTS leads Contextually Appropriate (97.9%) and Expanding Shorthand (86.1%), SpaceXAI TTS leads Preserving Exact Sequences (85.7%), and Qwen-Audio-3.0-TTS-Plus leads Standalone Terms (95.5%).
- Test sentences target real ambiguity: 'St.' as both Saint and Street, homographs like 'excuse', abbreviations like 'sec.' and 'ms', floor labels like '3rd Fl', and dates like '9/9' and 'Class of '09'.
Identifies which TTS model most reliably handles ambiguous real-world text like abbreviations and homographs, a common failure point for voice- and accessibility products.
Checking sign-in…
Loading comments…