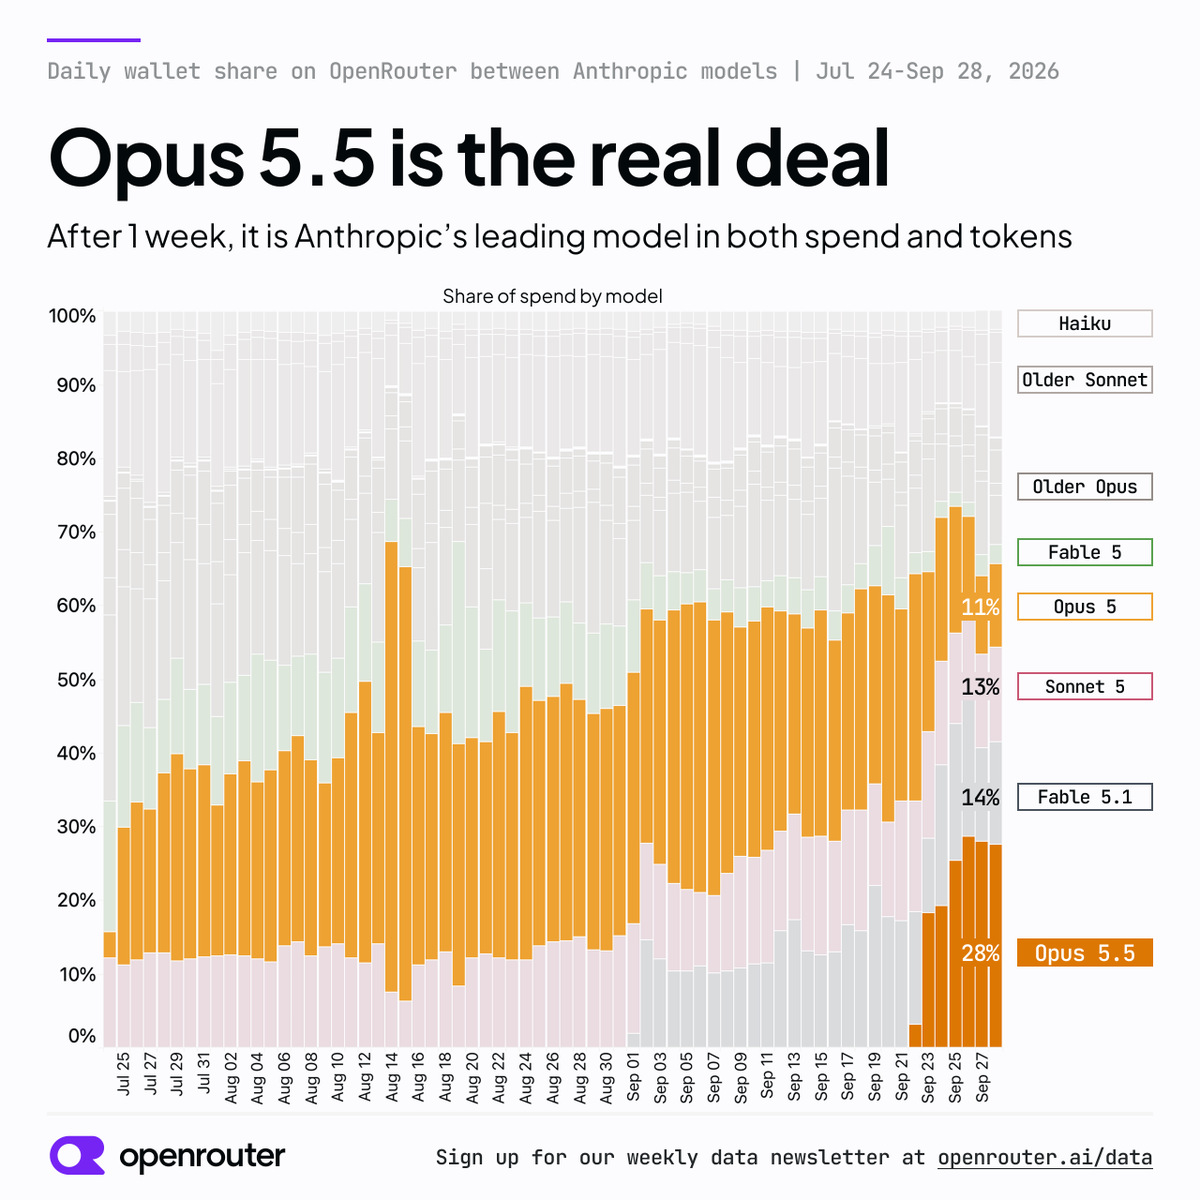
GPT-6 Astra and Claude 5.5 Opus race to create the best StarCraft bot
Source
starskirmish.com
Author
__cayenne__
Date
Why it matters
Removes the one-hour reasoning cap from an agentic coding benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition →, showing how frontier models perform on long-horizon implementation tasks against strong human-written bots.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.