ExecRetrieval: Measuring the Functional-Correctness Gap in Code-Embedding Retrieval
Source
arxiv.org
Author
Aaryan Kapoor, Md Abdullah Al Hafiz Khan
Date
Context
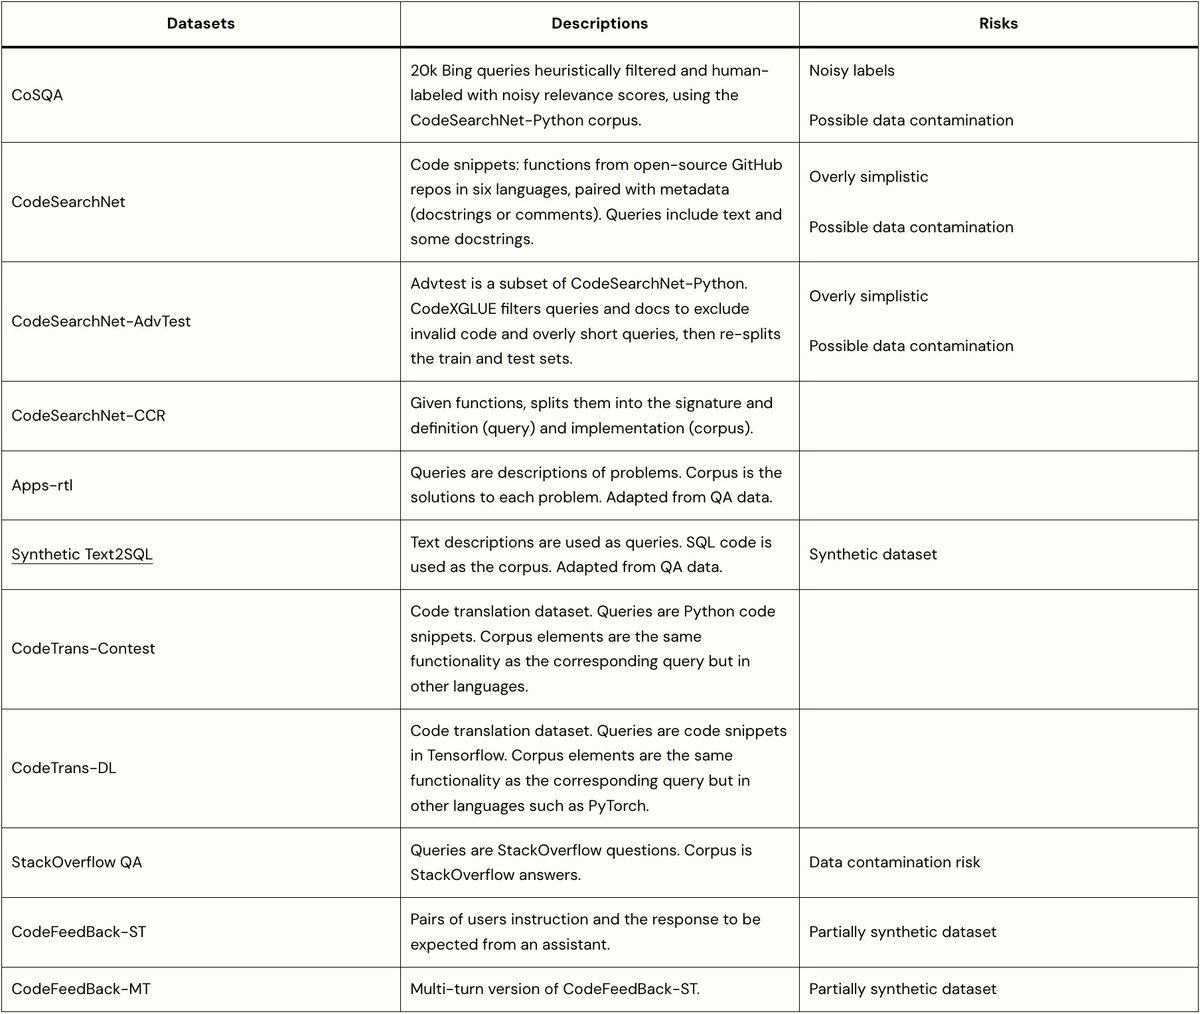
Code search can find the right neighborhood while putting a broken implementation first. ExecRetrieval tests that problem with 939 Python tasks, placing a tested correct solution beside near-identical versions containing a single deliberate bug. In the reported evaluation, the leading hosted search system included the correct implementation among its first ten results for every task, but ranked it first only 33.1% of the time.
This comparison matters when a coding AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → uses retrieved code directly: success at finding a relevant set of examples can conceal failure to select the working one. The benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → measures whether search rankings distinguish behavior when surface similarity offers little help.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.