[AINews] Reflection Beam - 501B-A23B American Open Model
Source
latent.space
Date
Why it matters
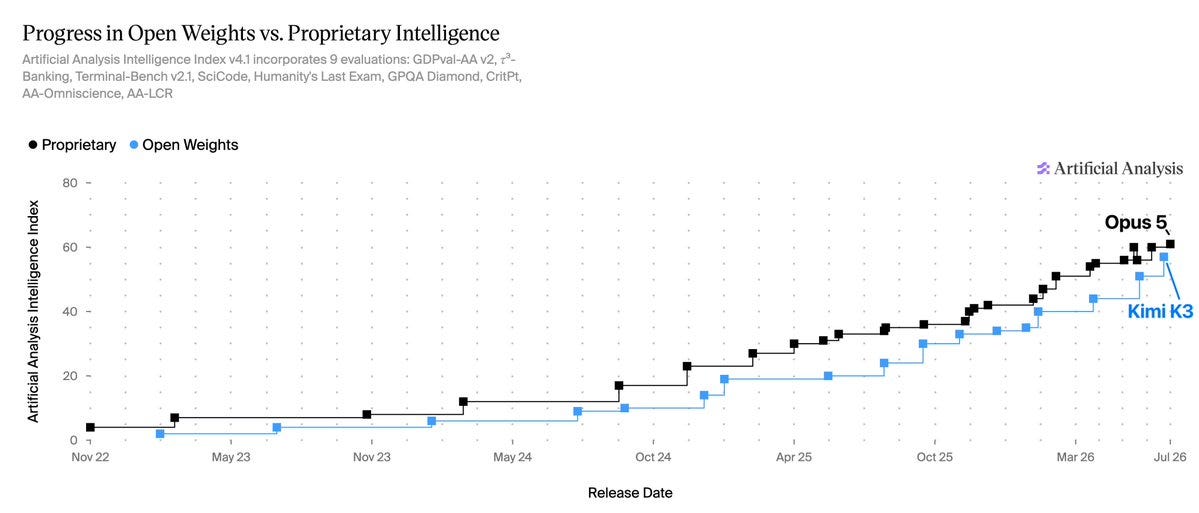
A US-trained open weightsA model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.Full definition →mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → for coding and agentic work arrives with Apache 2.0 weights due this month. It trails the best open models but widens options for teams needing US-origin weights.
Key takeaways · AI-distilled
Reflection's team says Beam's 23.8T pretrainingThe first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.Full definition → tokens came partly from an OCR pipeline over hundreds of millions of PDFs, followed by a stable RL/OPD run on 10K GB300s with more than 100M rollouts across about 1M tasks.
Reflection's claimed results include 80.9 on SWE-benchThe standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.Full definition → and 3 to 4x the inference efficiency of GLM 5.2. A tech report and open-source integrations are promised but had not shipped at the time of the digest.
Independent reads are mixed: Elie Bakouch estimates only about 12% BF16 MFU in pretraining and reads the design as 3:1 interleaved global and sliding-window attention, while observers place Beam near GLM 5.2 and below DeepSeek V4 Flash on some benchmarks.
The same issue reports a Hugging Face capture proxy that turned 10 unmodified agent harnesses into RL environments. Identical weights scored 62% under Mini-SWE-Agent and 33% under Claude Code, from a run with one task family and one seed.
Terms in this piece · Glossary
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.