Better prompt caching for GPT-6
- Source
- openai.com
- Date
Context
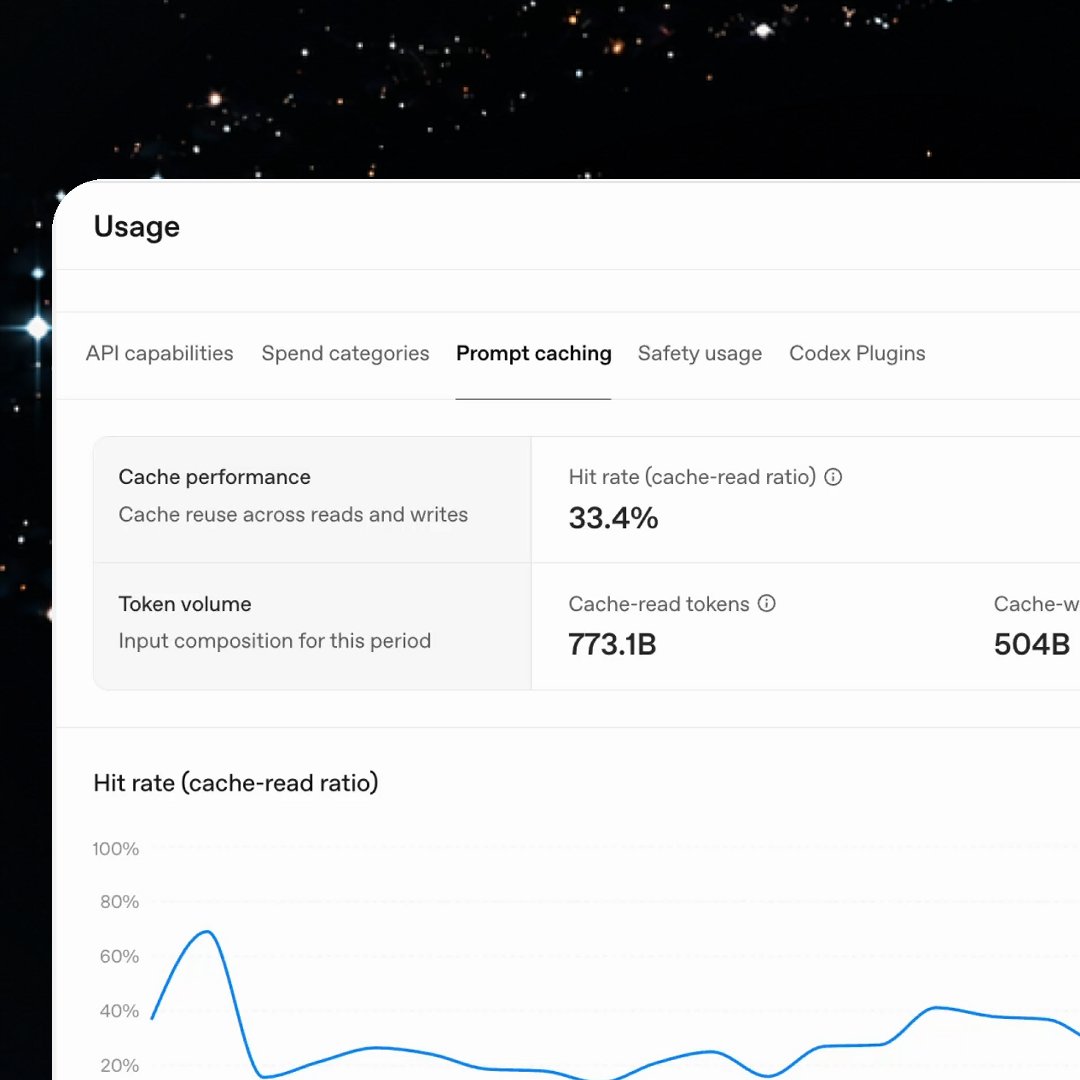
OpenAI's GPT-6 prompt-caching update is aimed at applications that resend the same long instructions, tool definitions or earlier with every request. lets a service reuse work already done on the shared beginning of a prompt instead of processing it again, which is how it can lower both latency and cost. OpenAI's announcement says the cache discount applies to eligible shared prefixes reused within a 30-minute window. It also introduces tools for monitoring cache performance, diagnosing why a request missed the cache, and choosing how much of a prompt to cache, including new diagnostics and explicit breakpoints. The announcement describes what developers can now observe and control; it does not by itself show how much any particular application would save.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.
Checking sign-in…
Loading comments…