Vibeleaderboard
← All Intel
Intel / post

Epoch: GPT-6.1 Sol long-context speedup hints at architecture change

Source
x.com
Date
EpochAIResearch@EpochAIResearch

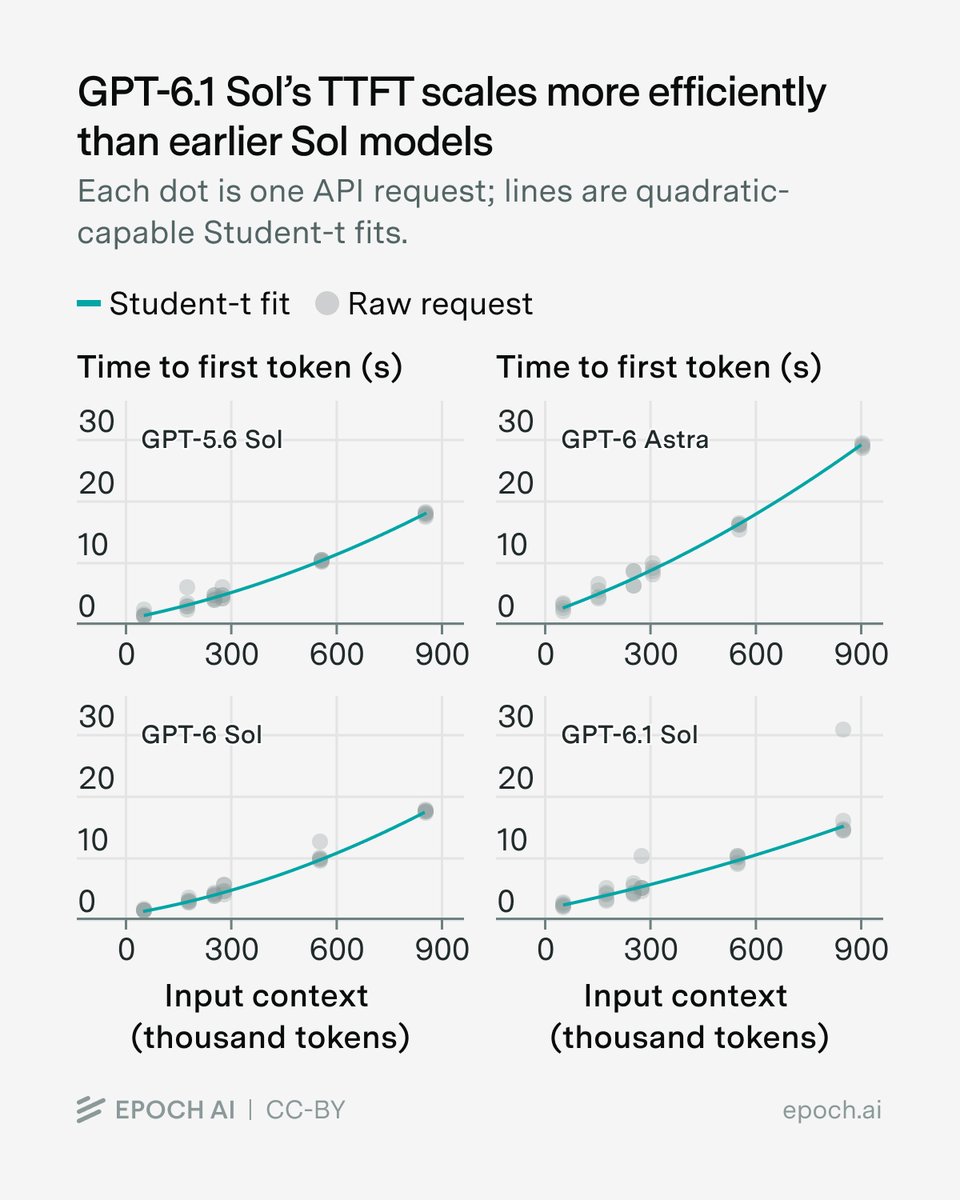
A new architecture for GPT-6.1 Sol? OpenAI halved its cached-input price compared with GPT-6 Sol. Our measurements show it also handles long prompts faster.

Four-panel chart of time to first token versus input context up to 900,000 tokens for GPT-5.6 Sol, GPT-6 Astra, GPT-6 Sol and GPT-6.1 Sol, with Student-t fits. GPT-6.1 Sol starts higher but rises more slowly, reaching about 15 seconds at the longest context versus about 17 seconds for GPT-5.6 Sol and GPT-6 Sol.
Why it matters

Cached input on GPT-6.1 Sol costs half that of GPT-6 Sol and long prompts run faster in Epoch's measurements. Agents with large repeated contexts get cheaper and quicker. Architecture change is speculation.

Terms in this piece · Glossary
  • context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
More from EpochAIResearch
Recommended reads
Comments

Checking sign-in…

Loading comments…