Simplifying Model Serving Across Multiple GPUs with NVIDIA TensorRT Multi-Device Integration in NVIDIA Dynamo-Triton
Source
Tanya Lenz
Author
Tanya Lenz
Date
Key takeaways · AI-distilled
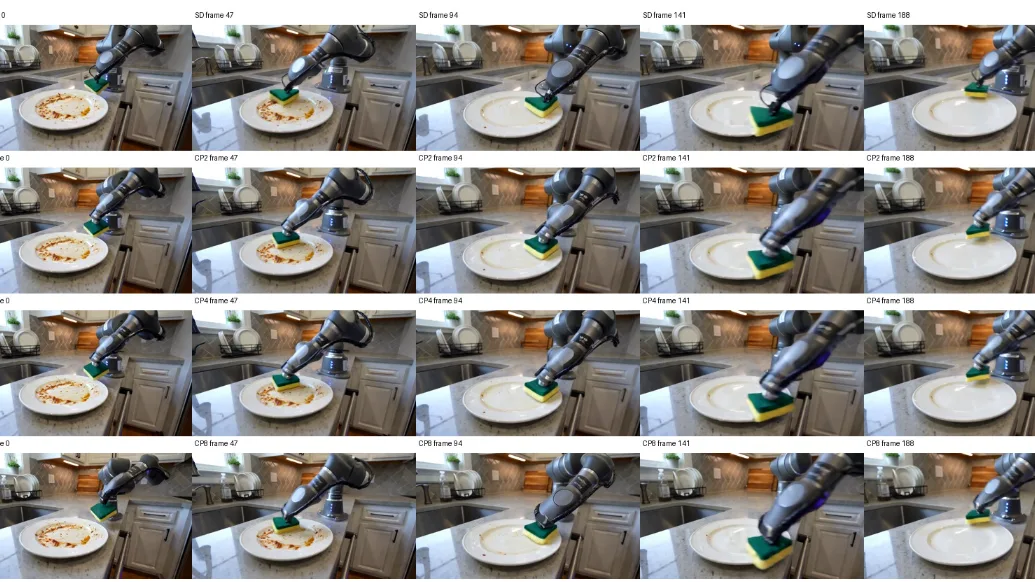
Demonstrated on Cosmos 3 Nano video generation: Ulysses context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → parallelism splits 44,160 video tokens across up to 8 GPUs, with each CP8 rank handling 5,520 tokens outside attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → while the 2,992-token text path stays replicated.
transformerThe neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.Full definition → RPC speedup reached 6.09x at 8-way parallelism, but end-to-end latency only improved 4.58x, because roughly 10.2-10.5 seconds of fixed overhead (prompt work, scheduling, VAE decode, postprocessing) stays constant and becomes a bigger share of a much shorter total.
On one GPU the transformer accounts for 93.4% of generation time; at 8-way parallelism that share falls to 70.2%, quantifying how much of the remaining latency now sits outside the accelerated path.
Output isn't pixel-identical to the single-GPU baseline: CP8 measured MAE 16.316 / PSNR 19.400 dB against validation thresholds of MAE <=25 / PSNR >=18dB, while CP2 and CP4 stayed closer (MAE 12.759 / PSNR 21.111 dB).
The distributed graph is compiled into each TensorRT plan before deployment rather than converted at runtime; the CP8 plan's topology alone contains two initial reduce-scatters, 108 all-to-alls across 36 transformer layers, and one final all-gather.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
Why it matters
Serving teams running multi-GPU inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → for large generative models get a supported path to split a single TensorRT network across GPUs via one gRPC endpoint, with measured throughput gains they can reproduce via the 26.07 release.
 articleHow to Use AI Agents to Prepare 3D Scenes for Simulation
 articleTranslating CUDA Tile Operations from Python to Rust Using Agentic AI
 articleHow NVIDIA Groq 3 LPX Deterministic Execution Drives Power-Efficient High-Interactivity Inference on NVIDIA Vera Rubin
 articleAccelerating Dropless MoE Training in JAX with NVIDIA Transformer Engine
 articleHow Full-Stack NIM Optimizations Deliver 2.5x More Users on Nemotron 3 UltraElizabeth Goodman
 articleTensorRT Edge-LLM Completes the MLPerf Edge Agentic Benchmark 6.4x Faster on Jetson AGX ThorElizabeth Goodman
 postNVIDIA Details Nemotron 3 Ultra NIM Serving Optimizations for 2.5x ConcurrencyNVIDIAAI