A decodability criterion predicts when hidden-state selection beats majority voting in large language models
Source
arxiv.org
Author
Zhixiang wang, Ziliang Hong, Ulas Bagci
Date
Why it matters
Gives a measurable criterion for choosing between self-consistency voting and hidden-state answer selection on a given task, and warns that probe accuracy reported without leakage controls is inflated.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
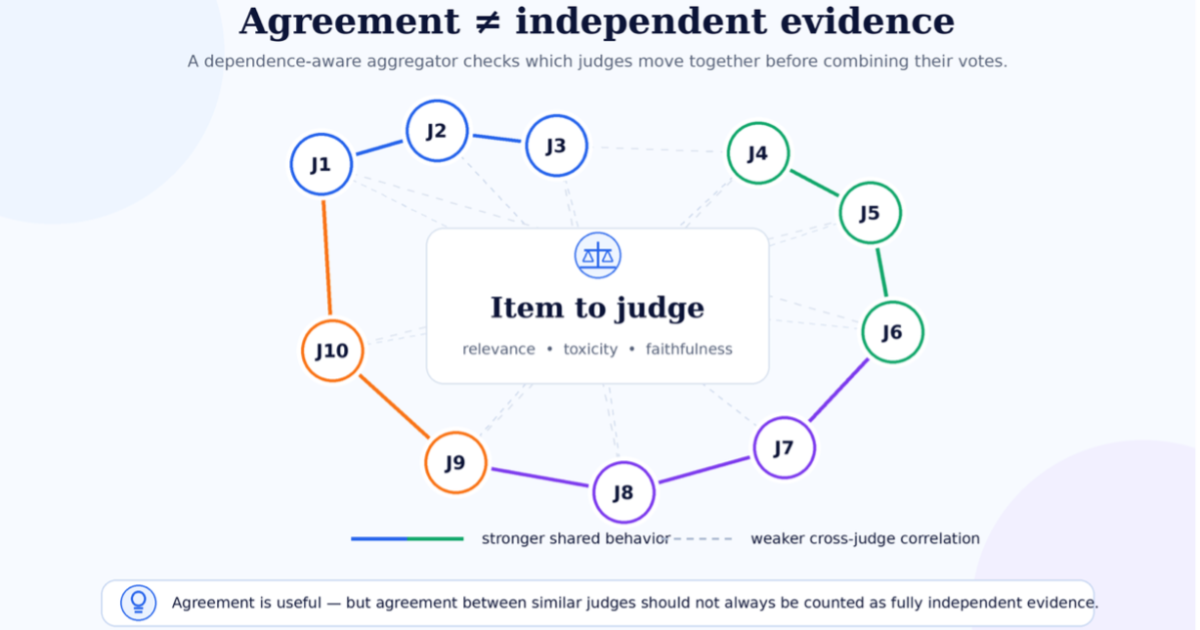 articleWhen LLM judges agree, should we believe them?www.amazon.science
 articleWhen Is a Multi-Agent Code Judge Actually Grounded? Two Label-Free Measurements, and a Judge That Declines to GuessSalma Roshdy Aly, Hussein Assaf, Ziad Kobti
 articleBeyond the Sycophancy Score: How Task, Model, and Pressure Shape LLM YieldingGuang Yang, Homa Hosseinmardi, Fengchen Liu, Amir Ghasemian