Accelerating Transformers Fine-Tuning with NVIDIA NeMo AutoModel
Source
huggingface.co
Date
Context
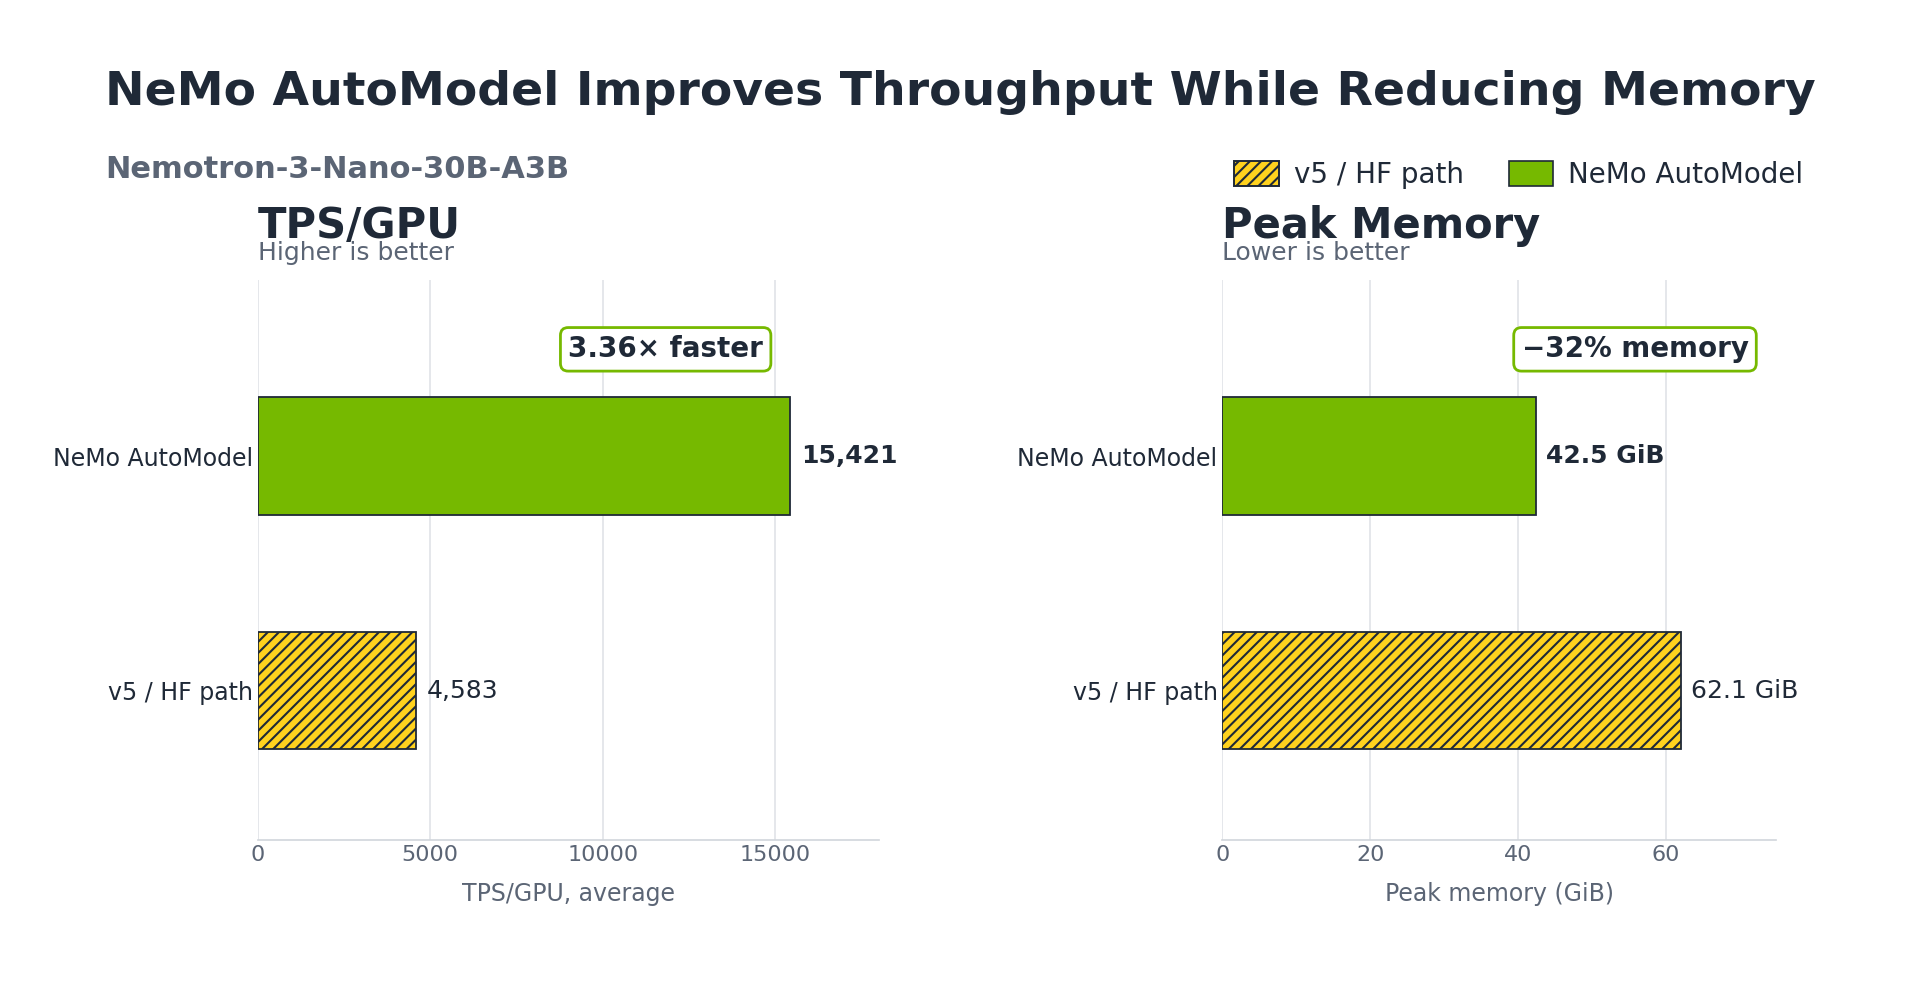
NVIDIA's NeMo AutoModel spreads a mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → model's specialized networks across GPUs and overlaps their communication with computation. Its fine-tuning report measures roughly 3.4 to 3.7 times the training throughput of Transformers v5 on two 30-billion-parameter models using eight H100 GPUs. The comparison has a consequential qualification: NeMo used forced, evenly balanced routing, while the baseline used its native routing on dummy inputs. Those results show performance under the stated benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → conditions; the routing difference prevents treating the multiplier as an assured speedup on a team's training data.
Terms in this piece · Glossary
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.