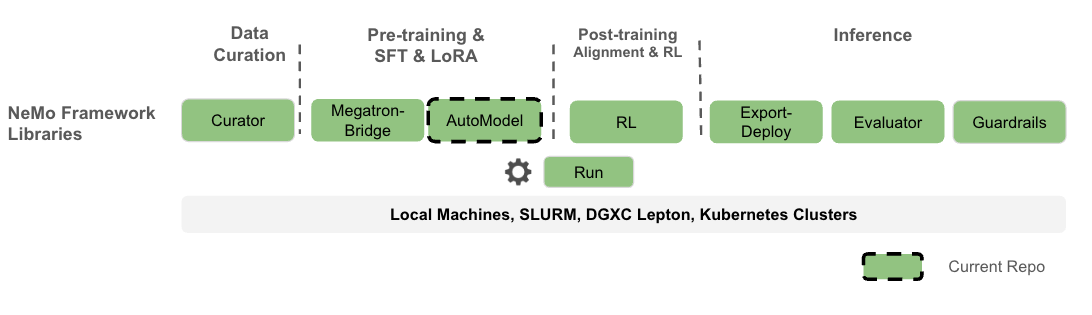
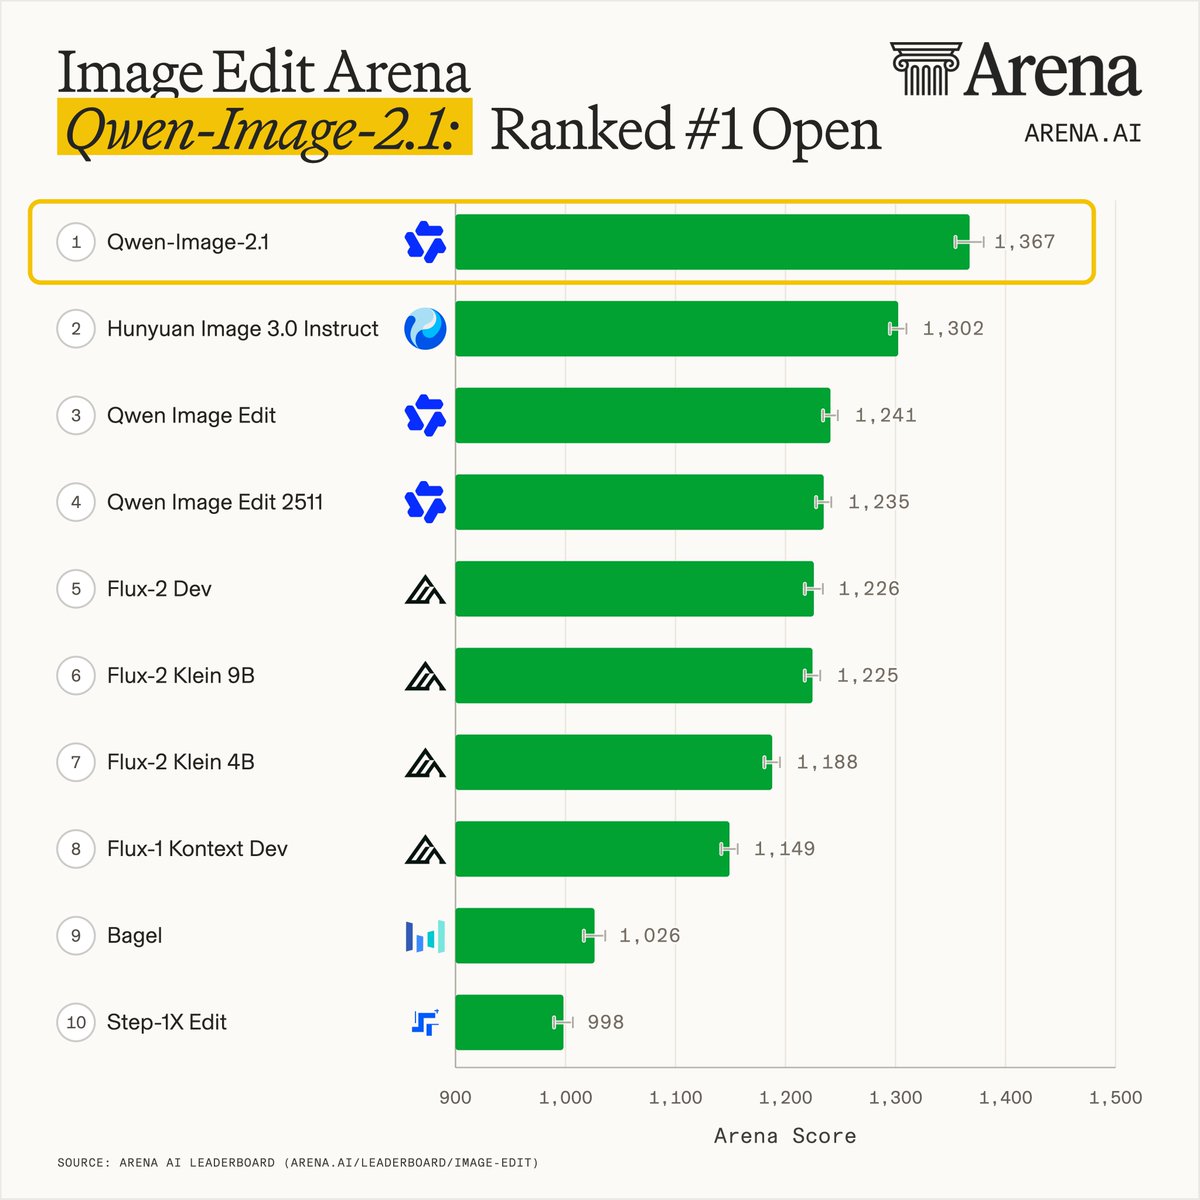
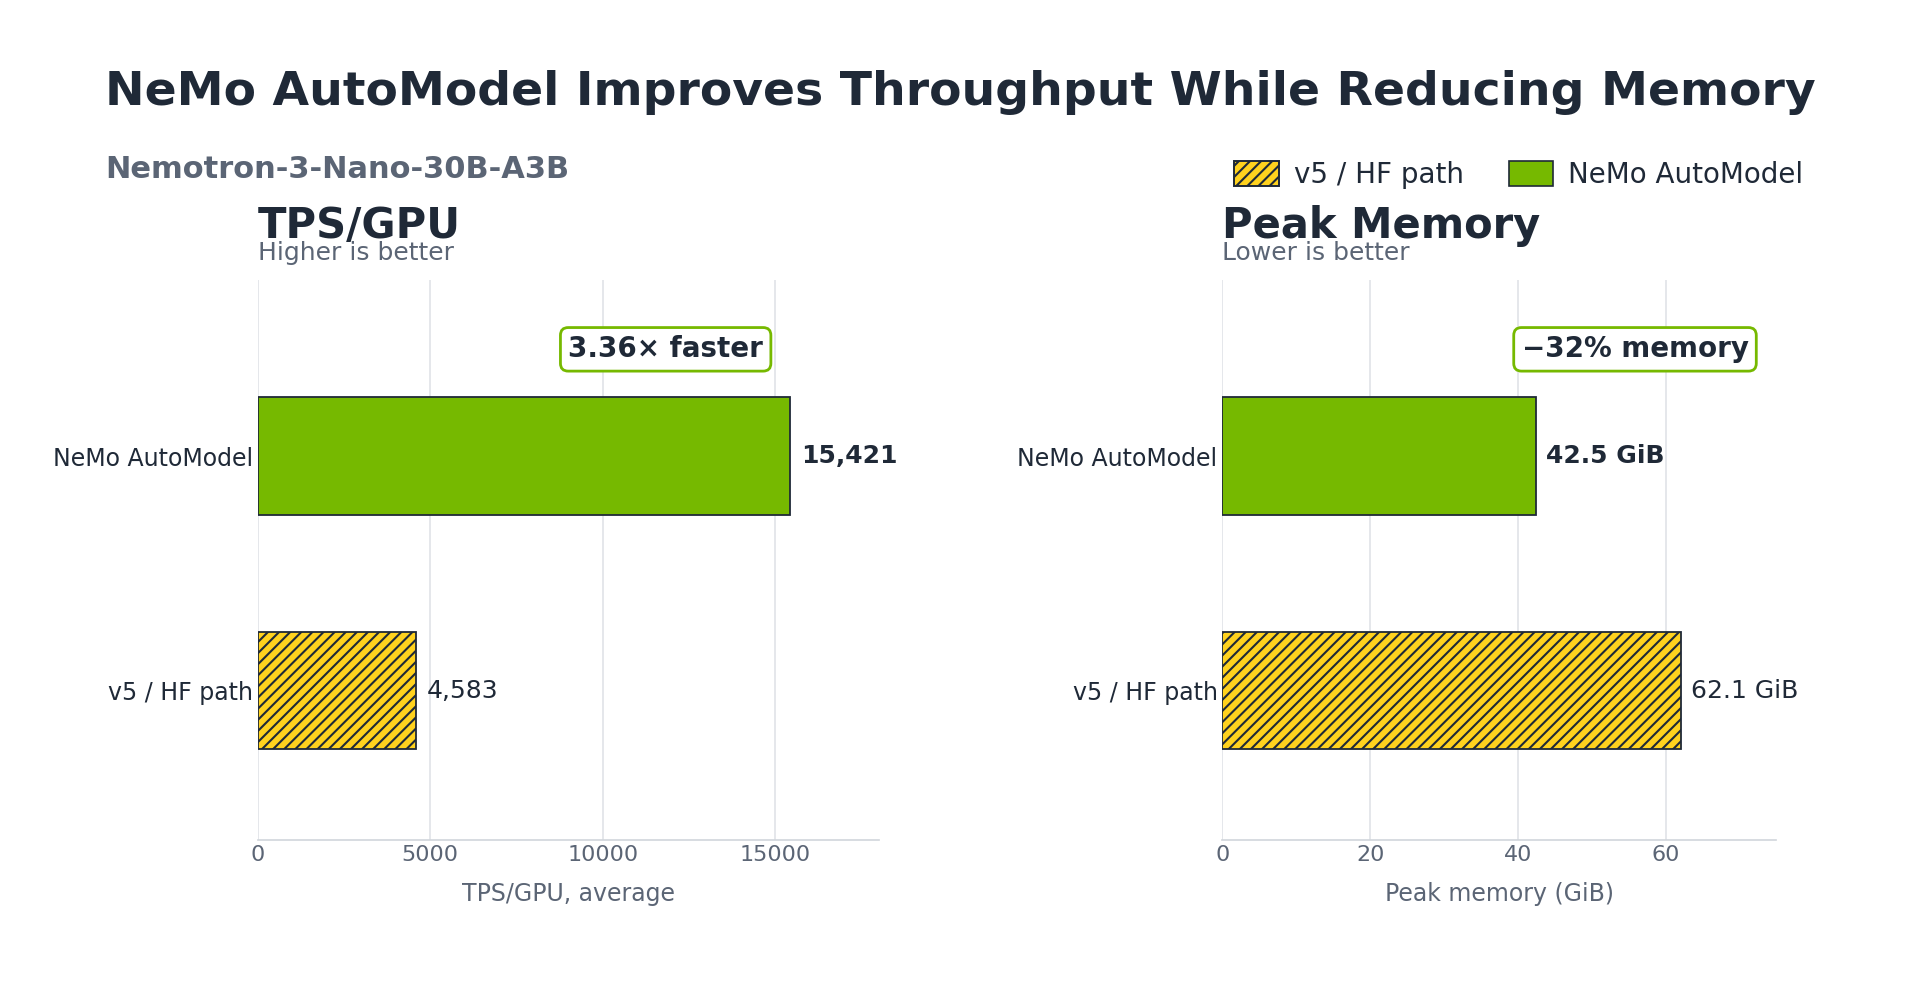
Thank you @NVIDIAAI for the day-0 support! 🙌 Developers can finetune the model…
Source
github.com
Author
Qwen
Date
Why it matters
You can fine-tune Qwen's new Engram mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → checkpoint on day one with FSDP2, expert and context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → parallelism, instead of waiting for community trainer support to catch up to the architecture.
Terms in this piece · Glossary
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.